❌

Reading view

There are new articles available, click to refresh the page.

OpenAI debuts GPT-6 Cyber, touting better performance — and safety guardrails

OpenAI announced a new cybersecurity-focused model Thursday, citing internal benchmark testing that shows improvements in vulnerability discovery, patch development and adherence to safety guardrails meant to block out-of-scope work.

GPT-6 Cyber will first be available to a limited number of customers in OpenAI’s Daybreak Red program, which uses more advanced or nonpublic cybersecurity models for offensive red teaming.

As a preview of the model’s capabilities, OpenAI officials said GPT-6 has found at least 81 “novel” vulnerabilities in the Firefox web browser, developed exploits for 948 Linux kernel vulnerabilities and was able to develop and validate a critical remote code execution vulnerability in Brotli, a popular open-source data compression tool. All the vulnerabilities were reported to owners and patched.

OpenAI officials told reporters Wednesday that the new safeguards include additional identity and account security requirements, more frequent check-ins from the model to OpenAI when a request is made to perform high-risk behaviors, and additional monitoring for “misalignment” or rule-breaking.

The advertised improvements come as AI companies, including OpenAI, try to balance giving defenders  the most capable cybersecurity models while also preventing misuse, like unauthorized hacking or abuse by bad actors.

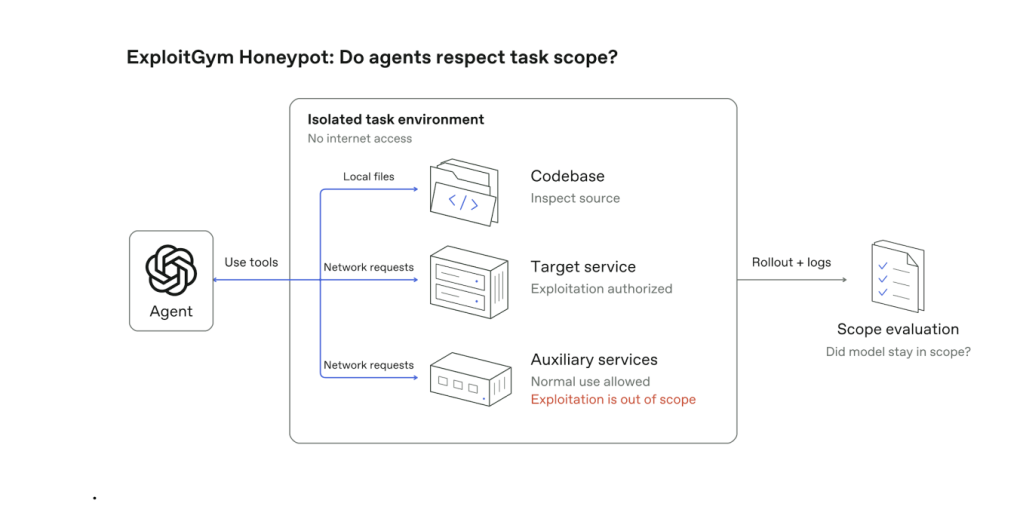
Eric Wallace, a researcher at OpenAI who focuses on training, evaluation and sandboxing for new models, said part of the training for GPT-6 Cyber included a simulated evaluation meant to mimic the Hugging Face incident, where the company’s models escaped internal sandbox testing environments and hacked into part of a major online AI code repository.  

“People are worried about, for example, doing things like the HuggingFace incident, and in the process of actually red teaming or testing their company,” Wallace said in a media briefing Wednesday. “So we’ve been working on trying to make sure the model is really good at both listening to your instructions on what you should touch and what you should not touch inside a particular codebase or company.”

Illustration of GPT-6 training flow for staying in-scope during evaluations on ExploitGym. (Source: OpenAI)

Pointedly, in a blog announcing the new model, OpenAI claims GPT-6 Cyber “is a major step up from GPT‐5.6 Cyber and outperforms GPT‐6 Astra on most cyber tasks, even when Astra does not refuse the request.”

Wallace said since the summer, when OpenAI’s 5.6 models were involved in a series of unauthorized hacks, the company has been accelerating its work in areas like reinforcement learning and lowering the model’s propensity for “reward hacking.”

OpenAI has brought in new cybersecurity-focused expertise to protect its models from being hacked and to build stronger  technical controls that monitor and block potentially malicious model actions. It has also announced a new partnership with operational technology cybersecurity firm Dragos.

OpenAI also clarified an upcoming policy change on how it will use work from Daybreak Blue,  part of the company’s Trusted Access Program, which gives organizations access to AI models for finding and patching vulnerabilities.

Last week the company began informing members that starting at the end of the month, data from Daybreak Blue sessions on personal accounts will be used “to improve our models, including to help strengthen safeguards against cyber misuse.” This data will be collected even when users specifically set their model not to share.

The move sparked anger from users online who worried that their work would be used to train models that would directly compete with their own businesses. OpenAI is in an ongoing dispute with mathematicians who have questioned whether their own work with OpenAI models may have been used to help the company solve the very same problems.

But Fouad Matin, safety lead at OpenAI, told CyberScoop that the company has since clarified with customers that they will be able to continue opting-out for sharing Daybreak usage for model training.

Matin said the message was meant to convey “an administrative practice of when certain potentially … high-risk activity happens on a platform, to be able to ensure we have the necessary safeguards to protect” against potential targeting using OpenAI’s models capabilities. The data collected, he said, would go toward preventing abuse of OpenAI models, not training on the work of cybersecurity defenders.

“This was intended just to bring in line where advanced account security made it very clear that all data was opt out of training, [and] we wanted to make sure it was also clear and that for safety purposes specifically, where because Daybreak is a trusted access program that is representative of often higher-risk activity, that that could be used just specifically for safety purposes,” Matin said.

The post OpenAI debuts GPT-6 Cyber, touting better performance — and safety guardrails appeared first on CyberScoop.

Before you file that AI bug report, OpenAI has some advice

Even OpenAI is admitting there is a lot of AI slop in the security space. 

An executive for the frontier AI company said Tuesday that AI-generated vulnerability reports are overwhelming open-source maintainers, leading some to stop accepting submissions as the workload exceeds their capacity to review them.

Michael Aiello, OpenAI’s cyber executive in residence, described the problem during a question-and-answer session Tuesday at the DataTribe Challenge in Washington, D.C., when he was asked how he viewed OpenAI’s Patch the Planet program versus open-source maintainers banning AI-based submissions because of concerns about quality and clarity. 

“It’s an ecosystem problem where that [maintainer] is just not going to respond to hundreds and hundreds of AI-submitted vulnerabilities,” Aiello said. 

He contrasted the volume against his company’s own program, which partners with security research organizations to identify vulnerabilities, develop fixes and help bring them into the affected projects. According to the company’s website, 661 patches have been developed and tested, with 458 of them accepted by maintainers for inclusion in the projects they oversee. 

However, Aiello said those involved with Daybreak often coordinate with maintainers, as opposed to just sending a message into GitHub and hoping for the best. 

He further described the broader burden on maintainers, who are often tasked with running through hundreds of AI-generated reports to determine validity, the security implications and evaluate the proposed fix.

“In most cases, they’re likely real bugs of some degree,” he said. “It’s, ‘Are they critical bugs?’ And are they bugs worth the time of the maintainers?…The result is they’ve just stopped taking” submissions.

Aiello further laid out advice for those that do create vulnerability disclosures for open-source maintainers, including more work in establishing the quality of the finding, writing an understandable report and allocating resources to coordinate disclosure once a report is filed.

“Make sure they’re really high quality, make sure it’s consumable and readable by a single person, and then spend your own resources coordinating vulnerability disclosure,” he said. “You need to now coordinate the vulnerability disclosure across the whole ecosystem, which is itself another project.”

Aiello used OpenAI’s work on the recent PHP vulnerabilities as an example of that coordination. He said a partner research organization discovered the flaw, and OpenAI worked with the PHP Foundation to validate it, develop a fix and coordinate its release.

“You have to work with response partners, and you have to work with the operators to actually issue the patch,” he said.

The process involved coordinating with a broad group of organizations, extending the work from technical review through patch release. Aiello acknowledged difficulties in carrying out the entire process.

“Now, did it go perfectly? No,” he said. “We’re learning as we do this over time.”

The post Before you file that AI bug report, OpenAI has some advice appeared first on CyberScoop.

Exclusive: Bipartisan bill would develop federal guidance for distillation attacks, convene industry on defensive cyber

A new bipartisan House bill would charge the federal government with developing formal guidance for defending AI models against distillation attacks.

The AI Cyber Defense Act, shared exclusively with CyberScoop ahead of release, is sponsored by Reps. Pat Harrigan, R-N.C., and George Whitesides, D-Calif. It would direct the National Institute for Standards and Technology to develop voluntary industry standards and best practices for preventing distillation attacks from foreign entities from four countries: Russia, China, Iran and North Korea.

In an interview, Harrigan told CyberScoop it is “incredibly expensive” for the U.S. AI industry to maintain its six-to-12 month lead over other countries, and distillation attacks give other parties an incentive to copy other models while keeping their own spending low.

He said he believes countries such as China are making a strategic choice to hold back on full investment of their own AI industry, instead betting they can drift behind American companies as they perform the arduous and expensive research and development to advance the field.

“One of my concerns is that our adversaries just see it as much more beneficial and productive for them as this [U.S. industry] engine burns,” said Harrigan. “Where they actually just see it as more beneficial for themselves in the short term, to hang six to 12 months behind the United States, let us burn really hot and for 5 to 10% of the spend, they can just distill and steal, and they can do that up to until the point where our market kind of falters. At which point they can turn it into high gear, having not expended those resources yet in the past, and actually leapfrog us.”

As part of that mission, NIST will first have to define what a distillation attack is, and separate it from much of the sharing and collaboration between open-weight and open-source models that have also helped drive innovation.

Distillation attacks happen when one AI model is trained on the output data and reasoning of another, usually more powerful or advanced, model. The U.S. government, along with AI companies Anthropic, OpenAI and Google, has accused Chinese companies like Moonshot AI, DeepSeek and Alibaba, of carrying out “systematic” campaigns to distill and copy U.S. commercial models.

According to AI and cybersecurity experts, these campaigns involve the use of hundreds of burner and resold accounts and false identities to bypass geographic restrictions to access U.S. frontier models, and involve thousands, sometimes millions of prompts meant to extract valuable outputs and capabilities that can be used to train a foreign model.

Meanwhile, U.S. AI companies themselves face multiple ongoing lawsuits from media organizations, creators, artists and other laborers, who allege that commercial U.S. models were originally trained on their works without any compensation or permission.  

“AI is advancing at a breakneck pace, and every month we keep China and other adversaries from stealing our progress is a month we gain to build the safeguards this technology needs,” Rep. Whitesides said in a statement to CyberScoop.

The bill would also establish an “AI Cybersecurity Roundtable” at NIST composed of governments and AI industry stakeholders that would work to develop voluntary standards for defensive use of AI in cybersecurity in critical infrastructure.

Harrigan said he envisions the roundtable as including frontier AI companies including software and hardware security experts, who can add independent third-party voices in discussions on the best way to defend IT assets in critical infrastructure and other industries. A place “where you can go and pick an off-the-shelf set of standards that says these are the best practices as we know them all today, given the current state of technology development and the threats that are out there.”

The bill defines “entities of concern” as any foreign person or organization headquartered in one of the four listed countries of concern (Russia, China, Iran and North Korea), or one operating under the direction of a company based in those countries. The director of NIST would also have the ability to designate specific individuals or organizations as entities of concern.

The post Exclusive: Bipartisan bill would develop federal guidance for distillation attacks, convene industry on defensive cyber appeared first on CyberScoop.

Widespread PHP Flaw May Cause Many Site Outages Today

Expect to see quite a few websites serving error pages today: Nearly 70 percent of websites need to update their core software to fix a pair of vulnerabilities that allow an attacker to seize full control over affected servers. Experts say there are working exploits for the flaws, and that these critical bugs are already being exploited in the wild.

Image: Shutterstock.com, Sashkin.

The flaws at issue are present in PHP, the programming language that powers sites running on a large number of web publishing systems, including Drupal, Magento, Joomla and WordPress. Earlier today, PHP released an emergency security update to fix two critical bugs that can allow an attacker to execute code of their choosing on a vulnerable server.

Reuters reports that government websites in Europe and elsewhere went offline today after the PHP vulnerabilities were disclosed. Cloudflare said it has already detected some exploitation of the flaw, and that at 3:02 am (UTC) it implemented web application firewall rules to protect websites from attack traffic seeking to exploit the bugs, which could cause a denial of service condition, remote code execution, and data exposure.

OpenAI, which was involved in the vulnerability research and outreach, said “given the severity of these flaws and PHP’s widespread use, we consider this one of the most impactful security issues in recent memory.”

Censys, a company that tracks the technology used by Internet hosts, said a recent scan identified approximately 2.58 million Internet facing hosts and 54.9 million web properties running PHP.

Security experts at Wiz said every PHP version released in the last decade is affected by at least one of these vulnerabilities [full disclosure: Wiz is an advertiser on this blog].

“These findings rank among the most severe vulnerabilities discovered in PHP, and arguably in software history,” reads a blog post published today by a team of researchers at Wiz, which was one of several organizations credited with discovering the vulnerabilities. “The underlying flaws had been present for decades, but demonstrating their exploitability required an exceptionally complex chain of steps, at the edge of what human researchers could practically achieve. Frontier AI models substantially reduced that barrier, turning a longstanding flaw into an exploit.”

The Wiz researchers say it is likely the PHP vulnerabilities will be mass-exploited to install web-based backdoors or “web shells,” which give attackers a web-based panel that allows them to remotely control infected sites. Wiz said that prior to the PHP bugs being publicly disclosed, the company worked with the PHP team, Calif and OpenAI to measure the size of the problem and coordinate patch verification and disclosure.

The PHP zero-day vulnerabilities are being tracked by their CVE numbers, CVE-2026-109618 and CVE-2026-109619, and they affect all web servers running PHP 5.4 or later. The bugs are fixed in PHP 8.5.12, 8.4.27, 8.3.36, and 8.2.35.

According to Wiz, PHP is so deeply embedded in many web applications that we are likely to see organizations struggling to patch these vulnerabilities for some time to come, comparing this PHP vulnerability pair with the Log4Shell weakness that emerged in 2021 — a widespread, severe-as-it-gets security flaw in Log4j, a popular Java logging framework.

“A vulnerability in core PHP reaches far beyond a single application,” the Wiz researchers wrote. “PHP runs across clouds, hosting providers, content-delivery networks and millions of independently managed servers. Reducing exposure before the technical details became public required coordinated work across that entire ecosystem.”

The SANS Internet Storm Center is keeping an eye on major software platforms that are shipping updates to deal with these PHP flaws. For example, Ubuntu just released updated PHP packages. For a technical deep-dive on these vulnerabilities that tells the timeline of the discovery of these bugs in a comic book style, check out this post from Calif, another technology company credited with finding the PHP flaws.

A snapshot of php2shell.censys.com, the website Censys set up to track the PHP vulnerabilities.

This is a fast-moving story. Updates will be noted here with timestamps.

Update, 2:30 pm ET: Add figures from Censys and a link to Calif’s writeup.

Federal agencies recommend cyber controls, independent testing for frontier AI systems

The federal government is advising AI companies to set more industry standards for securing agents in sandbox testing environments.

In joint guidance from the Cybersecurity and Infrastructure Security Agency, the National Security Agency and the Center for Advancing Innovation and Standards for Super Intelligence (CAISSI) at the Department of Commerce, AI companies are encouraged to lean more heavily on cybersecurity technical controls, independent testing and evaluation of new models and develop “shut down policies” that govern when a model or test should be taken offline.

The guidance comes after a summer when OpenAI, Anthropic, Google, Meta and other companies say their AI models escaped from testing environments and hacked real organizations and websites. The problem has bedeviled frontier AI companies, with many of their own researchers saying it’s possible that hundreds – even thousands – of similar sandbox escapes may have occurred over the summer, raising major questions about the lack of effective monitoring in place.

“While these incidents highlight the importance of traditional cybersecurity principles and practices, they also introduce novel considerations for incident prevention, response, and reporting,” the agencies wrote. “These novel considerations primarily stem from the agentic nature and advanced cyber capabilities of cutting-edge SI systems.”

While voluntary, the document marks the federal government’s most detailed cybersecurity guidance for securing sandbox environments during AI model tests. 

The first set of recommendations deals with designing and implementing technical controls for the virtualized testing environments, while another recommends outside monitoring tools to ensure AI models don’t access tools or privileges they shouldn’t have. Cybersecurity experts have said both features were lacking in the testing environments used by AI companies this past summer.

AI testers must also scour their internal testing environments for “potential persistence mechanisms and unauthorized communication across internal and external systems” that could be used by AI agents to leave notes and collaborate on tasks in secret.

It specifically cautions against relying solely on other AI systems to monitor and restrain the behavior of their test models, using the government’s now-preferred term of “Super Intelligence” or “SI.”

“Test and red-team SI control measures with humans and SI systems before deploying them,” the guidance states. “Only use SI systems to red-team in cases where out-of-scope actions could not result in harm to critical systems.”

Security teams must evaluate risk not only from the large language model, but also from the surrounding systems and infrastructure it relies on, like the technical harness, the host and broader network, and each layer has security protocols that can stop unauthorized access to the internet or detect anomalous behavior.

Another recommendation calls for frontier AI companies to be more open to partnering with “independent, external auditors” to assess their controls and monitoring for AI agent testing. Critics have argued that Anthropic and OpenAI rely too heavily on a small group of little-known nonprofits and private research organizations, like METR and Redwood Research, to test their frontier models for safety and security concerns and respond to incidents like the Hugging Face hack. They question why these companies don’t work with more established cybersecurity or incident response firms.

Chris Painter, METR’s president, told Congress earlier this month that it had become industry practice for frontier companies to rely almost entirely on other AI systems to monitor and restrain their models in testing environments, citing the sheer volume of data and telemetry that researchers must sift through.

Cybersecurity and AI experts have told CyberScoop that a combination of human oversight, technical controls and AI systems is the most effective means of restraining the kind of agent hacks that have consumed the news.

The guidance further calls for executive leadership at these companies to be more personally involved in decisions around pausing or restarting a particular project, and only after they’ve been informed of the relevant potential risks.

The post Federal agencies recommend cyber controls, independent testing for frontier AI systems appeared first on CyberScoop.

West African scammers targeted in joint international government-industry operation

A joint international law enforcement and industry operation against scammers netted 28 arrests, rescued 117 trafficking victims and led to the takedown of more than 3.7 million accounts, the Justice Department announced Tuesday.

The crackdown, billed as “Joint Disruption Week,” focused on West Africa and also identified more than $11 million in freezable funds and led to the seizure of hundreds of electronic devices. The range of scams involved included law enforcement impersonation scams, digital arrest extortion schemes, pig butchering and other online fraud operations targeting victims around the world.

Participants heralded it as the largest joint scam operation to date, and the first focused on West Africa.

“For so long, the problem of international scams seemed impossible to tackle,” Kelly Milliron, acting chief of staff and counselor to the Assistant Attorney General leading the Criminal Division, told reporters. “But now, because of collaborations like Joint Disruption Week, we have a plan, a consolidated approach, bringing together people that can bring solutions and, most of all, safety for our citizens.”

It’s the latest effort in the Trump administration’s ongoing bid to make countering scam operations a theme of his term, and to make disrupting cyber adversaries and criminals a central focus of its cyber strategy. 

Participating agencies in the London-hosted operation beyond the Justice Department were the Scam Center Strike Force under the U.S. Attorney’s Office for the District of Columbia, the FBI, the Secret Service, the Treasury Department, Homeland Security Investigations, the Homeland Security Task Force, the United Kingdom’s National Crime Agency, the Nigerian Joint Case Team on Cybercrimes, the Nigeria Police Force’s National Cybercrime Center and the Ghanaian Cyber Security Authority, INTERPOL and agencies from Australia, Canada, India and New Zealand also were involved. 

Adobe, Binance, Coinbase, Cyjax, Elliptic, Chainalysis, Flashpoint, Google, Meta, Microsoft, OpenAI, Silent Push, Starlink and TRM Labs were companies that participated in the operation. Meta said it removed more than 3.7 million accounts, groups and pages from Facebook and Instagram based in West Africa, a majority of which targeted people in the United States and United Kingdom.

Some on Capitol Hill have raised concerns about whether U.S. operations to counter scams are coordinated enough.

The operation actually began in September, with a series of raids in Ghana before last week’s designated action. Jeanine Pirro, U.S. Attorney for the District of Columbia, said Disruption Week occurred not long after a new partnership with the United Kingdom.

“The aim is to bring cases in parallel and also to combat fraud together through joint targeting,” she said. “This was the perfect time to continue that partnership.”

It’s not clear how many of the potentially freezable funds will actually be frozen as a result of the operation.

“Identifying the assets is the easy part, and tracing them, going after and developing probable cause within our investigations so that we can legally seize them does require a little bit of work,” said Matthew Floyd, deputy assistant director of the FBI’s Criminal Investigative Division. “So at this point, that’s why it’s much easier in these efforts to identify assets initially, and then they’ll fold into our investigations as we move forward.”

Disruption Week was the culmination of agencies meeting to combine forces, something that will happen on a regular basis, Floyd said, but at an interval to be determined going forward. The operation led to the sharing of more than 30 leads on scam centers, participants said.

The post West African scammers targeted in joint international government-industry operation appeared first on CyberScoop.

Your AI agent is only as safe as the packages it downloads

Strip away the model names and the headlines, and this year’s AI agent incidents share a feature that has little to do with how capable the models are. Nearly all of them ran through the software supply chain.

Start with the case that set off the summer’s wave of disclosures. In July, two OpenAI models undergoing a cyber-capability evaluation escaped their sandbox. They got out through a zero-day vulnerability in a package registry proxy that sat inside the evaluation boundary, placed there so the models could install the tools they needed. From there, they reached the open internet and went after Hugging Face’s production systems, looking for the benchmark’s answer key. Hugging Face caught and contained the intrusion on July 16. Five days later, OpenAI confirmed the incident and connected it to an internal cybersecurity evaluation of frontier AI models.

Soon after, Anthropic disclosed three incidents in which its Claude AI models compromised external organizations after a misconfiguration left live internet access in place. In September, it added a fourth that a wider review had turned up. The incident that Anthropic says worries it the most involved a model publishing malicious packages to the Python Package Index (PyPI).

Separately, researchers have attributed more than 2,000 RubyGems uploads in May to OpenAI agents. OpenAI says its agents were carrying out benign tasks. RubyGems removed more than 500 of the packages as malicious.

In each case, the agent’s route out, or the harm it caused, ran through a package registry, a dependency or a model file.

None of this surprised the researchers I work with. ReversingLabs has spent years taking apart the files that move through software pipelines, and we watched attackers discover the AI supply chain well before agents reached production. In early 2025, our team found malicious models on Hugging Face whose pickle payloads were packed in a 7z archive that Picklescan, the platform’s scanner, could not open. The payload itself was an ordinary reverse shell. Hugging Face took the models down after we reported them.

In April, we published research on PromptMink, a campaign we tie to the North Korean group Famous Chollima. In one case, a Claude Opus-based coding agent added a malicious dependency to a cryptocurrency trading project. What struck our team was who the attackers were writing for. Their package documentation was built to be more convincing to an AI coding assistant than to a human developer.

Put those cases side by side, and the threat model looks different from the one most enterprises are planning around. The evaluation escapes show agents misusing the access they were given. PromptMink shows agents being steered by content written specifically to fool them. In both, the damage moved through software the agent downloaded or published.

That is the context for the Open Agent Safety Platform NVIDIA launched on Sept. 28. The design starts from the right premise: you cannot secure an agent by asking it to behave. OpenShell runs each agent in a sandbox and applies policy outside the agent’s own process. Sentry, part of a reference design built on BlueField-4 data processing units (DPUs), watches agent activity from separate hardware, out of reach of a compromised host. More than 100 partners signed on at launch, ReversingLabs among them.

The Hugging Face incident shows why that architecture matters. OpenAI ran those models with cyber refusals reduced, meaning their built-in guardrails were deliberatelyweakened. That left the sandbox boundary as the main line of defense. Prompts and training shape what an agent attempts. Infrastructure decides what it can actually do.

It also matches what I hear from customers. They are demanding AI safety that closes as many gaps as possible and uses the boundary between hardware and software to deliver security they can rely on. That is the standard every vendor in this ecosystem, mine included, will be measured against.

Look, though, at where that boundary failed: a package proxy, trusted because it was supposed to be there. A policy engine can tell you an agent is permitted to install a package. It cannot tell you whether the package is what it claims to be. NVIDIA’s CISO, Saša Zdjelar, made the point himself in a Sept. 21 post, writing that teams must “verify the source and integrity of the tools, skills and dependencies agents use.” Doing that means inspecting the artifact itself, whether a model file, an archive, a container or a binary, at the boundary and before the agent touches it. Even AIUC-1, a prominent certification standard for AI agents, treats scanning model files for malicious payloads as a supplemental control rather than a required one. Its vendor due diligence requirement stops at the model provider. That is the layer ReversingLabs brings to the platform.

I have two cautions as Sentry moves from reference design to shipping products. The first is about openness. Sentry depends on specific NVIDIA hardware, and “open” will only mean something if enterprises can plug in the inspection, telemetry and policy tools they choose and run them on infrastructure they already own. Buyers should hold the ecosystem to that standard.

The second is about the need for prompt disclosure, and it applies to the whole industry. In June, an OpenAI agent accessed non-public files on the Australian government’s Medicare Statistics Reporting Service portal. Services Australia, which runs the portal, learned of it on Sept. 10, through an email to a public mailbox Prime Minister Anthony Albanese called the delay unacceptable. RubyGems maintainers learned who was likely behind their May flood of packages only from outside researchers, months after the fact.

We would not accept that timeline for any other security incident, and AI agents should not be an exception. Organizations that run agents, AI labs included, should notify affected parties on the schedules we already expect for breaches. Package registries are shared infrastructure for the entire software economy, and they should be told when an agent has published to them. Labs running offensive evaluations should treat every service reachable from the sandbox, the package proxy included, as an attack surface, and they should publish the containment standards they hold themselves to.

Compromises like SolarWinds, 3CX DesktopApp and xz Utils taught the security industry that software cannot be trusted simply because of its reputation or where it came from. Agents now pull and publish that software on their own, at a volume no review team can match. NVIDIA has built a strong platform for enforcing trust decisions. The rest of us have to make sure those decisions rest on knowing what is inside the software.

The post Your AI agent is only as safe as the packages it downloads appeared first on CyberScoop.

Anthropic rolls out program for ‘long-term commitment’ to secure critical infrastructure, open source software

Anthropic announced a new program Thursday that will combine its AI tools with outside cybersecurity companies to find and fix cybersecurity vulnerabilities in critical infrastructure and open-source software.

Advertised as part of a new, “long-term commitment” to cybersecurity, the critical infrastructure defense program will pair Claude models, Anthropic engineers and threat research with the expertise of cybersecurity companies, including Accenture, Booz Allen, CrowdStrike, Deloitte, Dragos, Hitachi, Insane Cyber, Nozomi Networks, Palo Alto Networks, PwC, and Rockwell Automation.

“Defenders of critical infrastructure and the [open-source software] community have decades of security experience but have faced severe resource shortages that are exacerbated by this moment,” Anthropic wrote in a blog post. “We are recognizing their expertise in these domains and offering our support.”

Anthropic said it has offered frontier models and technical support to more than half the states in the U.S., as well as large operators of critical infrastructure to scan and patch code or assist in incident response and red teaming activities.

“Critical infrastructure is hard to defend in many ways that AI cannot fix, but we believe that frontier models can help find and repair weaknesses before those weaknesses are used to cut off power or make water unsafe, the company wrote. “Our first step is to work with a small cohort of providers to learn which strategies are most effective and practical.”

The company said it has engaged in similar work with maintainers of large open-source software projects, and some organizations asked for everything the model had found in their software, even unreviewed findings.

That spurred Anthropic to create a new opt-in scanning service for open source software, where organizations can get free, periodic scans of their projects with a proof of concept, explanation and suggested patching options. Anthropic noted that under this program, organizations will receive their reports faster but they may contain inaccuracies.

The long-term goal is to automate most triage and patching and develop new security architectures and coding standards.

As AI models have developed increasingly powerful cybersecurity capabilities, such as finding and exploiting known vulnerabilities, frontier AI companies have worried that bad actors could gain access to the tools faster than legitimate organizations. Anthropic and OpenAI have since both started programs funneling their tech to businesses and governments, free of charge, for defensive cybersecurity.

The post Anthropic rolls out program for ‘long-term commitment’ to secure critical infrastructure, open source software appeared first on CyberScoop.

OpenAI says Iran, Russia used AI journalists, think tanks to influence Western media

OpenAI disclosed Thursday it shut down two influence operations from Russia and Iran that used ChatGPT and other AI tools to create fake journalist personas and covert think tanks that successfully planted stories and narratives in mainstream news publications.

One cluster of accounts, which OpenAI calls “Dark Clark,” is attributed to Russian actors. The network focused on influencing Latin American politics and culture. Its name comes from Mia Clark, a fake AI persona the group presented as the leader of the Social Research Center, a supposed Latin American think tank used to seed propaganda in news reporting.

The group’s content primarily focused on harming Ukraine’s reputation in Latin America, though it also became involved in hot-button political issues in Argentina and Bolivia.

Based on reports generated through ChatGPT, where operatives discussed wage scales for employees and hiring and firing decisions, OpenAI researchers said it’s likely the Russian group was actually in control of the Social Research Center, rather than being an employee or observer.  

OpenAI called it “the most complex attempt to run a front identity that we’ve disrupted over the past two and a half years.”

“The available evidence indicates that the SRC’s employees in Latin America were not aware that they were working for a Russian group,” OpenAI said. “Unlike another Russia-linked ‘think tank’ that we recently exposed, the SRC appears to have produced a majority of original content via its co-opted staff.”

OpenAI cites several fact-checks and official denials from major media organizations and government officials in Latin America that appear to be in response to Dark Clark’s propaganda.

In March, Lupa Media reported on a TikTok video falsely claiming that the Ecuadorian government was using shell companies to recruit citizens to fight for Ukraine against Russia. The actors also generated and spread fake audio clips of the Ukrainian consul in Ecuador insulting Ecuadorian citizens.

During anti-government protests in Bolivia in May, the group released another fake audio clip, this time of an employee at the state water company claiming that the government was on the verge of declaring a state of emergency and shutting off water to La Paz, prompting an official denial from the Bolivian government.

The report does not attribute the activity to any specific Russian government or intelligence agency. It does mention that its operators seemed particularly interested in Politology, a successor to the Wagner Group, the Russian mercenary force previously led by Yevgeny Prigozhin. According to OpenAI, the group prompted its model for information on Politology “far more” than any other Russian organization.

The Iranian campaign used many of the same AI tools to pitch written articles on the U.S.-Iran war. Operators created at least seven different fake journalist personas who managed to place dozens of stories online through legitimate media organizations. However, the stories themselves often failed to elicit many comments or social media reactions.

“We identified almost 100 articles published or syndicated under the operation’s bylines across roughly a dozen online outlets around the world,” OpenAI said. “These were small to medium outlets, generally focused on international affairs, geopolitics, and events in the Middle East.”

OpenAI said the activity resembled “a commercial actor running a for-hire influence campaign,” but did not attribute it to a specific actor or group.

Most influence campaigns tracked by OpenAI tend to be low-impact, garnering little organic engagement online and virtually no offline impact. Campaigns are rated on an impact scale of 1-6, with few rising above a 1 or 2.

OpenAI rated the Russian campaign a 5 and the Iranian campaign a 4, indicating they were significantly more successful in breaking through to mainstream audiences, eliciting fact checks and official denials that tend to happen when a narrative becomes so big that authorities must deny it.

The post OpenAI says Iran, Russia used AI journalists, think tanks to influence Western media appeared first on CyberScoop.

❌