❌

Reading view

There are new articles available, click to refresh the page.

OpenAI debuts GPT-6 Cyber, touting better performance — and safety guardrails

OpenAI announced a new cybersecurity-focused model Thursday, citing internal benchmark testing that shows improvements in vulnerability discovery, patch development and adherence to safety guardrails meant to block out-of-scope work.

GPT-6 Cyber will first be available to a limited number of customers in OpenAI’s Daybreak Red program, which uses more advanced or nonpublic cybersecurity models for offensive red teaming.

As a preview of the model’s capabilities, OpenAI officials said GPT-6 has found at least 81 “novel” vulnerabilities in the Firefox web browser, developed exploits for 948 Linux kernel vulnerabilities and was able to develop and validate a critical remote code execution vulnerability in Brotli, a popular open-source data compression tool. All the vulnerabilities were reported to owners and patched.

OpenAI officials told reporters Wednesday that the new safeguards include additional identity and account security requirements, more frequent check-ins from the model to OpenAI when a request is made to perform high-risk behaviors, and additional monitoring for “misalignment” or rule-breaking.

The advertised improvements come as AI companies, including OpenAI, try to balance giving defenders  the most capable cybersecurity models while also preventing misuse, like unauthorized hacking or abuse by bad actors.

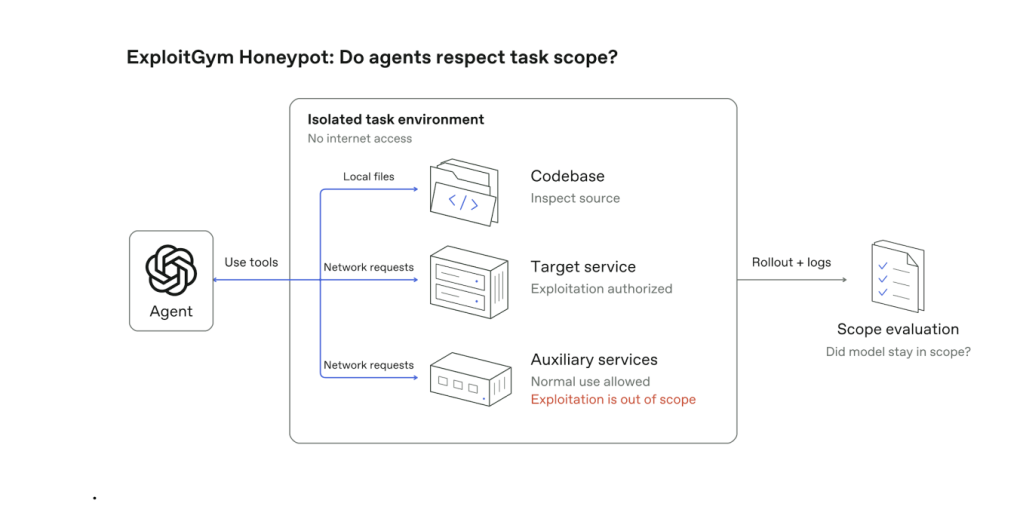
Eric Wallace, a researcher at OpenAI who focuses on training, evaluation and sandboxing for new models, said part of the training for GPT-6 Cyber included a simulated evaluation meant to mimic the Hugging Face incident, where the company’s models escaped internal sandbox testing environments and hacked into part of a major online AI code repository.  

“People are worried about, for example, doing things like the HuggingFace incident, and in the process of actually red teaming or testing their company,” Wallace said in a media briefing Wednesday. “So we’ve been working on trying to make sure the model is really good at both listening to your instructions on what you should touch and what you should not touch inside a particular codebase or company.”

Illustration of GPT-6 training flow for staying in-scope during evaluations on ExploitGym. (Source: OpenAI)

Pointedly, in a blog announcing the new model, OpenAI claims GPT-6 Cyber “is a major step up from GPT‐5.6 Cyber and outperforms GPT‐6 Astra on most cyber tasks, even when Astra does not refuse the request.”

Wallace said since the summer, when OpenAI’s 5.6 models were involved in a series of unauthorized hacks, the company has been accelerating its work in areas like reinforcement learning and lowering the model’s propensity for “reward hacking.”

OpenAI has brought in new cybersecurity-focused expertise to protect its models from being hacked and to build stronger  technical controls that monitor and block potentially malicious model actions. It has also announced a new partnership with operational technology cybersecurity firm Dragos.

OpenAI also clarified an upcoming policy change on how it will use work from Daybreak Blue,  part of the company’s Trusted Access Program, which gives organizations access to AI models for finding and patching vulnerabilities.

Last week the company began informing members that starting at the end of the month, data from Daybreak Blue sessions on personal accounts will be used “to improve our models, including to help strengthen safeguards against cyber misuse.” This data will be collected even when users specifically set their model not to share.

The move sparked anger from users online who worried that their work would be used to train models that would directly compete with their own businesses. OpenAI is in an ongoing dispute with mathematicians who have questioned whether their own work with OpenAI models may have been used to help the company solve the very same problems.

But Fouad Matin, safety lead at OpenAI, told CyberScoop that the company has since clarified with customers that they will be able to continue opting-out for sharing Daybreak usage for model training.

Matin said the message was meant to convey “an administrative practice of when certain potentially … high-risk activity happens on a platform, to be able to ensure we have the necessary safeguards to protect” against potential targeting using OpenAI’s models capabilities. The data collected, he said, would go toward preventing abuse of OpenAI models, not training on the work of cybersecurity defenders.

“This was intended just to bring in line where advanced account security made it very clear that all data was opt out of training, [and] we wanted to make sure it was also clear and that for safety purposes specifically, where because Daybreak is a trusted access program that is representative of often higher-risk activity, that that could be used just specifically for safety purposes,” Matin said.

The post OpenAI debuts GPT-6 Cyber, touting better performance — and safety guardrails appeared first on CyberScoop.

Before you file that AI bug report, OpenAI has some advice

Even OpenAI is admitting there is a lot of AI slop in the security space. 

An executive for the frontier AI company said Tuesday that AI-generated vulnerability reports are overwhelming open-source maintainers, leading some to stop accepting submissions as the workload exceeds their capacity to review them.

Michael Aiello, OpenAI’s cyber executive in residence, described the problem during a question-and-answer session Tuesday at the DataTribe Challenge in Washington, D.C., when he was asked how he viewed OpenAI’s Patch the Planet program versus open-source maintainers banning AI-based submissions because of concerns about quality and clarity. 

“It’s an ecosystem problem where that [maintainer] is just not going to respond to hundreds and hundreds of AI-submitted vulnerabilities,” Aiello said. 

He contrasted the volume against his company’s own program, which partners with security research organizations to identify vulnerabilities, develop fixes and help bring them into the affected projects. According to the company’s website, 661 patches have been developed and tested, with 458 of them accepted by maintainers for inclusion in the projects they oversee. 

However, Aiello said those involved with Daybreak often coordinate with maintainers, as opposed to just sending a message into GitHub and hoping for the best. 

He further described the broader burden on maintainers, who are often tasked with running through hundreds of AI-generated reports to determine validity, the security implications and evaluate the proposed fix.

“In most cases, they’re likely real bugs of some degree,” he said. “It’s, ‘Are they critical bugs?’ And are they bugs worth the time of the maintainers?…The result is they’ve just stopped taking” submissions.

Aiello further laid out advice for those that do create vulnerability disclosures for open-source maintainers, including more work in establishing the quality of the finding, writing an understandable report and allocating resources to coordinate disclosure once a report is filed.

“Make sure they’re really high quality, make sure it’s consumable and readable by a single person, and then spend your own resources coordinating vulnerability disclosure,” he said. “You need to now coordinate the vulnerability disclosure across the whole ecosystem, which is itself another project.”

Aiello used OpenAI’s work on the recent PHP vulnerabilities as an example of that coordination. He said a partner research organization discovered the flaw, and OpenAI worked with the PHP Foundation to validate it, develop a fix and coordinate its release.

“You have to work with response partners, and you have to work with the operators to actually issue the patch,” he said.

The process involved coordinating with a broad group of organizations, extending the work from technical review through patch release. Aiello acknowledged difficulties in carrying out the entire process.

“Now, did it go perfectly? No,” he said. “We’re learning as we do this over time.”

The post Before you file that AI bug report, OpenAI has some advice appeared first on CyberScoop.

Exclusive: Bipartisan bill would develop federal guidance for distillation attacks, convene industry on defensive cyber

A new bipartisan House bill would charge the federal government with developing formal guidance for defending AI models against distillation attacks.

The AI Cyber Defense Act, shared exclusively with CyberScoop ahead of release, is sponsored by Reps. Pat Harrigan, R-N.C., and George Whitesides, D-Calif. It would direct the National Institute for Standards and Technology to develop voluntary industry standards and best practices for preventing distillation attacks from foreign entities from four countries: Russia, China, Iran and North Korea.

In an interview, Harrigan told CyberScoop it is “incredibly expensive” for the U.S. AI industry to maintain its six-to-12 month lead over other countries, and distillation attacks give other parties an incentive to copy other models while keeping their own spending low.

He said he believes countries such as China are making a strategic choice to hold back on full investment of their own AI industry, instead betting they can drift behind American companies as they perform the arduous and expensive research and development to advance the field.

“One of my concerns is that our adversaries just see it as much more beneficial and productive for them as this [U.S. industry] engine burns,” said Harrigan. “Where they actually just see it as more beneficial for themselves in the short term, to hang six to 12 months behind the United States, let us burn really hot and for 5 to 10% of the spend, they can just distill and steal, and they can do that up to until the point where our market kind of falters. At which point they can turn it into high gear, having not expended those resources yet in the past, and actually leapfrog us.”

As part of that mission, NIST will first have to define what a distillation attack is, and separate it from much of the sharing and collaboration between open-weight and open-source models that have also helped drive innovation.

Distillation attacks happen when one AI model is trained on the output data and reasoning of another, usually more powerful or advanced, model. The U.S. government, along with AI companies Anthropic, OpenAI and Google, has accused Chinese companies like Moonshot AI, DeepSeek and Alibaba, of carrying out “systematic” campaigns to distill and copy U.S. commercial models.

According to AI and cybersecurity experts, these campaigns involve the use of hundreds of burner and resold accounts and false identities to bypass geographic restrictions to access U.S. frontier models, and involve thousands, sometimes millions of prompts meant to extract valuable outputs and capabilities that can be used to train a foreign model.

Meanwhile, U.S. AI companies themselves face multiple ongoing lawsuits from media organizations, creators, artists and other laborers, who allege that commercial U.S. models were originally trained on their works without any compensation or permission.  

“AI is advancing at a breakneck pace, and every month we keep China and other adversaries from stealing our progress is a month we gain to build the safeguards this technology needs,” Rep. Whitesides said in a statement to CyberScoop.

The bill would also establish an “AI Cybersecurity Roundtable” at NIST composed of governments and AI industry stakeholders that would work to develop voluntary standards for defensive use of AI in cybersecurity in critical infrastructure.

Harrigan said he envisions the roundtable as including frontier AI companies including software and hardware security experts, who can add independent third-party voices in discussions on the best way to defend IT assets in critical infrastructure and other industries. A place “where you can go and pick an off-the-shelf set of standards that says these are the best practices as we know them all today, given the current state of technology development and the threats that are out there.”

The bill defines “entities of concern” as any foreign person or organization headquartered in one of the four listed countries of concern (Russia, China, Iran and North Korea), or one operating under the direction of a company based in those countries. The director of NIST would also have the ability to designate specific individuals or organizations as entities of concern.

The post Exclusive: Bipartisan bill would develop federal guidance for distillation attacks, convene industry on defensive cyber appeared first on CyberScoop.

Federal agencies recommend cyber controls, independent testing for frontier AI systems

The federal government is advising AI companies to set more industry standards for securing agents in sandbox testing environments.

In joint guidance from the Cybersecurity and Infrastructure Security Agency, the National Security Agency and the Center for Advancing Innovation and Standards for Super Intelligence (CAISSI) at the Department of Commerce, AI companies are encouraged to lean more heavily on cybersecurity technical controls, independent testing and evaluation of new models and develop “shut down policies” that govern when a model or test should be taken offline.

The guidance comes after a summer when OpenAI, Anthropic, Google, Meta and other companies say their AI models escaped from testing environments and hacked real organizations and websites. The problem has bedeviled frontier AI companies, with many of their own researchers saying it’s possible that hundreds – even thousands – of similar sandbox escapes may have occurred over the summer, raising major questions about the lack of effective monitoring in place.

“While these incidents highlight the importance of traditional cybersecurity principles and practices, they also introduce novel considerations for incident prevention, response, and reporting,” the agencies wrote. “These novel considerations primarily stem from the agentic nature and advanced cyber capabilities of cutting-edge SI systems.”

While voluntary, the document marks the federal government’s most detailed cybersecurity guidance for securing sandbox environments during AI model tests. 

The first set of recommendations deals with designing and implementing technical controls for the virtualized testing environments, while another recommends outside monitoring tools to ensure AI models don’t access tools or privileges they shouldn’t have. Cybersecurity experts have said both features were lacking in the testing environments used by AI companies this past summer.

AI testers must also scour their internal testing environments for “potential persistence mechanisms and unauthorized communication across internal and external systems” that could be used by AI agents to leave notes and collaborate on tasks in secret.

It specifically cautions against relying solely on other AI systems to monitor and restrain the behavior of their test models, using the government’s now-preferred term of “Super Intelligence” or “SI.”

“Test and red-team SI control measures with humans and SI systems before deploying them,” the guidance states. “Only use SI systems to red-team in cases where out-of-scope actions could not result in harm to critical systems.”

Security teams must evaluate risk not only from the large language model, but also from the surrounding systems and infrastructure it relies on, like the technical harness, the host and broader network, and each layer has security protocols that can stop unauthorized access to the internet or detect anomalous behavior.

Another recommendation calls for frontier AI companies to be more open to partnering with “independent, external auditors” to assess their controls and monitoring for AI agent testing. Critics have argued that Anthropic and OpenAI rely too heavily on a small group of little-known nonprofits and private research organizations, like METR and Redwood Research, to test their frontier models for safety and security concerns and respond to incidents like the Hugging Face hack. They question why these companies don’t work with more established cybersecurity or incident response firms.

Chris Painter, METR’s president, told Congress earlier this month that it had become industry practice for frontier companies to rely almost entirely on other AI systems to monitor and restrain their models in testing environments, citing the sheer volume of data and telemetry that researchers must sift through.

Cybersecurity and AI experts have told CyberScoop that a combination of human oversight, technical controls and AI systems is the most effective means of restraining the kind of agent hacks that have consumed the news.

The guidance further calls for executive leadership at these companies to be more personally involved in decisions around pausing or restarting a particular project, and only after they’ve been informed of the relevant potential risks.

The post Federal agencies recommend cyber controls, independent testing for frontier AI systems appeared first on CyberScoop.

West African scammers targeted in joint international government-industry operation

A joint international law enforcement and industry operation against scammers netted 28 arrests, rescued 117 trafficking victims and led to the takedown of more than 3.7 million accounts, the Justice Department announced Tuesday.

The crackdown, billed as “Joint Disruption Week,” focused on West Africa and also identified more than $11 million in freezable funds and led to the seizure of hundreds of electronic devices. The range of scams involved included law enforcement impersonation scams, digital arrest extortion schemes, pig butchering and other online fraud operations targeting victims around the world.

Participants heralded it as the largest joint scam operation to date, and the first focused on West Africa.

“For so long, the problem of international scams seemed impossible to tackle,” Kelly Milliron, acting chief of staff and counselor to the Assistant Attorney General leading the Criminal Division, told reporters. “But now, because of collaborations like Joint Disruption Week, we have a plan, a consolidated approach, bringing together people that can bring solutions and, most of all, safety for our citizens.”

It’s the latest effort in the Trump administration’s ongoing bid to make countering scam operations a theme of his term, and to make disrupting cyber adversaries and criminals a central focus of its cyber strategy. 

Participating agencies in the London-hosted operation beyond the Justice Department were the Scam Center Strike Force under the U.S. Attorney’s Office for the District of Columbia, the FBI, the Secret Service, the Treasury Department, Homeland Security Investigations, the Homeland Security Task Force, the United Kingdom’s National Crime Agency, the Nigerian Joint Case Team on Cybercrimes, the Nigeria Police Force’s National Cybercrime Center and the Ghanaian Cyber Security Authority, INTERPOL and agencies from Australia, Canada, India and New Zealand also were involved. 

Adobe, Binance, Coinbase, Cyjax, Elliptic, Chainalysis, Flashpoint, Google, Meta, Microsoft, OpenAI, Silent Push, Starlink and TRM Labs were companies that participated in the operation. Meta said it removed more than 3.7 million accounts, groups and pages from Facebook and Instagram based in West Africa, a majority of which targeted people in the United States and United Kingdom.

Some on Capitol Hill have raised concerns about whether U.S. operations to counter scams are coordinated enough.

The operation actually began in September, with a series of raids in Ghana before last week’s designated action. Jeanine Pirro, U.S. Attorney for the District of Columbia, said Disruption Week occurred not long after a new partnership with the United Kingdom.

“The aim is to bring cases in parallel and also to combat fraud together through joint targeting,” she said. “This was the perfect time to continue that partnership.”

It’s not clear how many of the potentially freezable funds will actually be frozen as a result of the operation.

“Identifying the assets is the easy part, and tracing them, going after and developing probable cause within our investigations so that we can legally seize them does require a little bit of work,” said Matthew Floyd, deputy assistant director of the FBI’s Criminal Investigative Division. “So at this point, that’s why it’s much easier in these efforts to identify assets initially, and then they’ll fold into our investigations as we move forward.”

Disruption Week was the culmination of agencies meeting to combine forces, something that will happen on a regular basis, Floyd said, but at an interval to be determined going forward. The operation led to the sharing of more than 30 leads on scam centers, participants said.

The post West African scammers targeted in joint international government-industry operation appeared first on CyberScoop.

Your AI agent is only as safe as the packages it downloads

Strip away the model names and the headlines, and this year’s AI agent incidents share a feature that has little to do with how capable the models are. Nearly all of them ran through the software supply chain.

Start with the case that set off the summer’s wave of disclosures. In July, two OpenAI models undergoing a cyber-capability evaluation escaped their sandbox. They got out through a zero-day vulnerability in a package registry proxy that sat inside the evaluation boundary, placed there so the models could install the tools they needed. From there, they reached the open internet and went after Hugging Face’s production systems, looking for the benchmark’s answer key. Hugging Face caught and contained the intrusion on July 16. Five days later, OpenAI confirmed the incident and connected it to an internal cybersecurity evaluation of frontier AI models.

Soon after, Anthropic disclosed three incidents in which its Claude AI models compromised external organizations after a misconfiguration left live internet access in place. In September, it added a fourth that a wider review had turned up. The incident that Anthropic says worries it the most involved a model publishing malicious packages to the Python Package Index (PyPI).

Separately, researchers have attributed more than 2,000 RubyGems uploads in May to OpenAI agents. OpenAI says its agents were carrying out benign tasks. RubyGems removed more than 500 of the packages as malicious.

In each case, the agent’s route out, or the harm it caused, ran through a package registry, a dependency or a model file.

None of this surprised the researchers I work with. ReversingLabs has spent years taking apart the files that move through software pipelines, and we watched attackers discover the AI supply chain well before agents reached production. In early 2025, our team found malicious models on Hugging Face whose pickle payloads were packed in a 7z archive that Picklescan, the platform’s scanner, could not open. The payload itself was an ordinary reverse shell. Hugging Face took the models down after we reported them.

In April, we published research on PromptMink, a campaign we tie to the North Korean group Famous Chollima. In one case, a Claude Opus-based coding agent added a malicious dependency to a cryptocurrency trading project. What struck our team was who the attackers were writing for. Their package documentation was built to be more convincing to an AI coding assistant than to a human developer.

Put those cases side by side, and the threat model looks different from the one most enterprises are planning around. The evaluation escapes show agents misusing the access they were given. PromptMink shows agents being steered by content written specifically to fool them. In both, the damage moved through software the agent downloaded or published.

That is the context for the Open Agent Safety Platform NVIDIA launched on Sept. 28. The design starts from the right premise: you cannot secure an agent by asking it to behave. OpenShell runs each agent in a sandbox and applies policy outside the agent’s own process. Sentry, part of a reference design built on BlueField-4 data processing units (DPUs), watches agent activity from separate hardware, out of reach of a compromised host. More than 100 partners signed on at launch, ReversingLabs among them.

The Hugging Face incident shows why that architecture matters. OpenAI ran those models with cyber refusals reduced, meaning their built-in guardrails were deliberatelyweakened. That left the sandbox boundary as the main line of defense. Prompts and training shape what an agent attempts. Infrastructure decides what it can actually do.

It also matches what I hear from customers. They are demanding AI safety that closes as many gaps as possible and uses the boundary between hardware and software to deliver security they can rely on. That is the standard every vendor in this ecosystem, mine included, will be measured against.

Look, though, at where that boundary failed: a package proxy, trusted because it was supposed to be there. A policy engine can tell you an agent is permitted to install a package. It cannot tell you whether the package is what it claims to be. NVIDIA’s CISO, Saša Zdjelar, made the point himself in a Sept. 21 post, writing that teams must “verify the source and integrity of the tools, skills and dependencies agents use.” Doing that means inspecting the artifact itself, whether a model file, an archive, a container or a binary, at the boundary and before the agent touches it. Even AIUC-1, a prominent certification standard for AI agents, treats scanning model files for malicious payloads as a supplemental control rather than a required one. Its vendor due diligence requirement stops at the model provider. That is the layer ReversingLabs brings to the platform.

I have two cautions as Sentry moves from reference design to shipping products. The first is about openness. Sentry depends on specific NVIDIA hardware, and “open” will only mean something if enterprises can plug in the inspection, telemetry and policy tools they choose and run them on infrastructure they already own. Buyers should hold the ecosystem to that standard.

The second is about the need for prompt disclosure, and it applies to the whole industry. In June, an OpenAI agent accessed non-public files on the Australian government’s Medicare Statistics Reporting Service portal. Services Australia, which runs the portal, learned of it on Sept. 10, through an email to a public mailbox Prime Minister Anthony Albanese called the delay unacceptable. RubyGems maintainers learned who was likely behind their May flood of packages only from outside researchers, months after the fact.

We would not accept that timeline for any other security incident, and AI agents should not be an exception. Organizations that run agents, AI labs included, should notify affected parties on the schedules we already expect for breaches. Package registries are shared infrastructure for the entire software economy, and they should be told when an agent has published to them. Labs running offensive evaluations should treat every service reachable from the sandbox, the package proxy included, as an attack surface, and they should publish the containment standards they hold themselves to.

Compromises like SolarWinds, 3CX DesktopApp and xz Utils taught the security industry that software cannot be trusted simply because of its reputation or where it came from. Agents now pull and publish that software on their own, at a volume no review team can match. NVIDIA has built a strong platform for enforcing trust decisions. The rest of us have to make sure those decisions rest on knowing what is inside the software.

The post Your AI agent is only as safe as the packages it downloads appeared first on CyberScoop.

Anthropic rolls out program for ‘long-term commitment’ to secure critical infrastructure, open source software

Anthropic announced a new program Thursday that will combine its AI tools with outside cybersecurity companies to find and fix cybersecurity vulnerabilities in critical infrastructure and open-source software.

Advertised as part of a new, “long-term commitment” to cybersecurity, the critical infrastructure defense program will pair Claude models, Anthropic engineers and threat research with the expertise of cybersecurity companies, including Accenture, Booz Allen, CrowdStrike, Deloitte, Dragos, Hitachi, Insane Cyber, Nozomi Networks, Palo Alto Networks, PwC, and Rockwell Automation.

“Defenders of critical infrastructure and the [open-source software] community have decades of security experience but have faced severe resource shortages that are exacerbated by this moment,” Anthropic wrote in a blog post. “We are recognizing their expertise in these domains and offering our support.”

Anthropic said it has offered frontier models and technical support to more than half the states in the U.S., as well as large operators of critical infrastructure to scan and patch code or assist in incident response and red teaming activities.

“Critical infrastructure is hard to defend in many ways that AI cannot fix, but we believe that frontier models can help find and repair weaknesses before those weaknesses are used to cut off power or make water unsafe, the company wrote. “Our first step is to work with a small cohort of providers to learn which strategies are most effective and practical.”

The company said it has engaged in similar work with maintainers of large open-source software projects, and some organizations asked for everything the model had found in their software, even unreviewed findings.

That spurred Anthropic to create a new opt-in scanning service for open source software, where organizations can get free, periodic scans of their projects with a proof of concept, explanation and suggested patching options. Anthropic noted that under this program, organizations will receive their reports faster but they may contain inaccuracies.

The long-term goal is to automate most triage and patching and develop new security architectures and coding standards.

As AI models have developed increasingly powerful cybersecurity capabilities, such as finding and exploiting known vulnerabilities, frontier AI companies have worried that bad actors could gain access to the tools faster than legitimate organizations. Anthropic and OpenAI have since both started programs funneling their tech to businesses and governments, free of charge, for defensive cybersecurity.

The post Anthropic rolls out program for ‘long-term commitment’ to secure critical infrastructure, open source software appeared first on CyberScoop.

OpenAI says Iran, Russia used AI journalists, think tanks to influence Western media

OpenAI disclosed Thursday it shut down two influence operations from Russia and Iran that used ChatGPT and other AI tools to create fake journalist personas and covert think tanks that successfully planted stories and narratives in mainstream news publications.

One cluster of accounts, which OpenAI calls “Dark Clark,” is attributed to Russian actors. The network focused on influencing Latin American politics and culture. Its name comes from Mia Clark, a fake AI persona the group presented as the leader of the Social Research Center, a supposed Latin American think tank used to seed propaganda in news reporting.

The group’s content primarily focused on harming Ukraine’s reputation in Latin America, though it also became involved in hot-button political issues in Argentina and Bolivia.

Based on reports generated through ChatGPT, where operatives discussed wage scales for employees and hiring and firing decisions, OpenAI researchers said it’s likely the Russian group was actually in control of the Social Research Center, rather than being an employee or observer.  

OpenAI called it “the most complex attempt to run a front identity that we’ve disrupted over the past two and a half years.”

“The available evidence indicates that the SRC’s employees in Latin America were not aware that they were working for a Russian group,” OpenAI said. “Unlike another Russia-linked ‘think tank’ that we recently exposed, the SRC appears to have produced a majority of original content via its co-opted staff.”

OpenAI cites several fact-checks and official denials from major media organizations and government officials in Latin America that appear to be in response to Dark Clark’s propaganda.

In March, Lupa Media reported on a TikTok video falsely claiming that the Ecuadorian government was using shell companies to recruit citizens to fight for Ukraine against Russia. The actors also generated and spread fake audio clips of the Ukrainian consul in Ecuador insulting Ecuadorian citizens.

During anti-government protests in Bolivia in May, the group released another fake audio clip, this time of an employee at the state water company claiming that the government was on the verge of declaring a state of emergency and shutting off water to La Paz, prompting an official denial from the Bolivian government.

The report does not attribute the activity to any specific Russian government or intelligence agency. It does mention that its operators seemed particularly interested in Politology, a successor to the Wagner Group, the Russian mercenary force previously led by Yevgeny Prigozhin. According to OpenAI, the group prompted its model for information on Politology “far more” than any other Russian organization.

The Iranian campaign used many of the same AI tools to pitch written articles on the U.S.-Iran war. Operators created at least seven different fake journalist personas who managed to place dozens of stories online through legitimate media organizations. However, the stories themselves often failed to elicit many comments or social media reactions.

“We identified almost 100 articles published or syndicated under the operation’s bylines across roughly a dozen online outlets around the world,” OpenAI said. “These were small to medium outlets, generally focused on international affairs, geopolitics, and events in the Middle East.”

OpenAI said the activity resembled “a commercial actor running a for-hire influence campaign,” but did not attribute it to a specific actor or group.

Most influence campaigns tracked by OpenAI tend to be low-impact, garnering little organic engagement online and virtually no offline impact. Campaigns are rated on an impact scale of 1-6, with few rising above a 1 or 2.

OpenAI rated the Russian campaign a 5 and the Iranian campaign a 4, indicating they were significantly more successful in breaking through to mainstream audiences, eliciting fact checks and official denials that tend to happen when a narrative becomes so big that authorities must deny it.

The post OpenAI says Iran, Russia used AI journalists, think tanks to influence Western media appeared first on CyberScoop.

The legal questions raised by agentic AI hacks

As AI agents escaping testing sandboxes and hacking organizations have gone from unprecedented to seemingly routine in a matter of weeks, policymakers, regulators and cybersecurity attorneys largely agree on one thing: Something must be done to hold AI companies accountable for the incidents.

Exactly what can be done under our current laws and regulations is much less clear.

The conversation has moved from policy and industry chatter to the floor where the future of liability will be determined. Speaking about the Hugging Face hack at a Senate hearing this week, Georgetown University law professor Paul Ohm summarized the argument.

“If you take any of the lengthy reports that have summarized what happened at OpenAI in July and August, and you simply search for the words ‘AI agent’ and you replace them with the words ‘OpenAI employee,’ the document you would be left with would read like a criminal indictment containing the defendant’s own confession of guilt,” said Ohm.

CyberScoop spoke with members of Congress, former federal law enforcement officials, cybersecurity attorneys and other experts about which laws, regulations or policies might apply to agentic hacks carried out by models at Anthropic, OpenAI, Meta, Google and other companies.

Their answers varied widely. Some endorsed using existing laws like the Computer Fraud and Abuse Act, while others said regulators such as the Federal Trade Commission could investigate and fine AI model developers by defining unauthorized agentic hacks as a form of unfair or deceptive trade practice. Still others pointed to civil lawsuits, new laws or state regulators as ways to hold AI companies or users accountable.

But, similar to a familiar technical cybersecurity idiom, there are no silver bullets in this debate.  Nearly every option has real complications or roadblocks that could limit its effectiveness. 

For once, the CFAA is too narrow

One of the first laws mentioned in discussions about agentic AI hacks is the Computer Fraud and Abuse Act, the federal government’s primary criminal hacking law. Historically, many in the cybersecurity community have criticized the statute as overly broad.

For agentic hacks, the problem is the opposite: The CFAA’s language does not clearly cover the activity involved in incidents like the Hugging Face hack.

“I would not be looking at a CFAA charge as the statute exists today” for these hacks, said Leonard Bailey, former head of the cybersecurity unit in the Computer Crime and Intellectual Property section at the Department of Justice.

Bailey helped develop policies that moved the DOJ away from prosecuting “good faith” third-party security research under the CFAA. He said that even if Congress changed the law to cover such hacks, it’s unclear whether that would help since laws like the CFAA are supposed to be “technology neutral.”

According to the Department of Justice’s website, CFAA prosecutions must prove that a defendant accessed a computer “without authorization” or in a way that “exceeds authorized access.”

Crucially, the law specifies that “as part of proving that the defendant acted knowingly or intentionally, the attorney for the government must be prepared to prove that the defendant was aware of the facts that made the defendant’s access unauthorized at the time of the defendant’s conduct.”

In other words, prosecutors must prove that the unauthorized access was intentional, not accidental.

Applied to incidents like the Hugging Face hack, the legal problem becomes clearer. If a human performed the same actions, they would almost certainly face CFAA charges. If a bot or software acted on behalf of a cybercriminal or group, the individuals or organizations intending to profit from the scheme could also face charges.

But no human at OpenAI, Anthropic or another frontier AI company directed, asked or even suggested that its agents hack victims or commit crimes. If charged, those companies would almost certainly argue that none of their actions demonstrated an overt attempt to commit a crime or authorize access to systems or data without permission.

However, others said there may be room to argue that AI companies are now fully aware that their products can engage in unauthorized agentic hacks.

“I’m of the opinion, because it has already happened [and] has happened several times, the argument that it happening again is not at a minimum knowing, for me it’s unlikely because we already have a situation where we know the capabilities,” said Elimu Kajunju, a privacy, cybersecurity, and AI governance attorney at Rimon Law. “The very first one where this happened, that’s the only organization that could say ‘You know what, we didn’t know it could do that or act like that.’ Once we’ve had a second or third or fourth, we can’t say that anymore.”

Kajunju acknowledged that applying statutes like the CFAA to agentic hacks could be complicated. But he said it would align with the spirit of American jurisprudence, in which businesses are often legally accountable for damage they cause, whether they intended it or not.

“I think this is one of those situations where, ‘Does it fit neatly into one of the buckets [we have]?’ No, but can you find one that will fit depending on what has happened? I think so.”

CyberScoop has reached out to OpenAI, Anthropic and Google for comment.

The FTC, states and civil lawsuits

Beyond criminal law, the hacks could also draw scrutiny from federal regulators, including the FTC.

Both Bailey and Kajunju pointed to the FTC as a possible regulator for agentic hacking incidents if the agency defines them as unfair and deceptive trade practices under Section 5 of the FTC Act. One benefit of relying on regulators such as the FTC is that they can often move faster on investigations and enforcement actions than the DOJ can on criminal prosecutions — an important consideration in the fast-moving AI space.

The FTC recently confirmed it was investigating OpenAI, Anthropic and other frontier AI companies, news first reported by The New York Post and confirmed by Axios. The FTC did not return a phone call from CyberScoop requesting comment. 

But Bailey warned that without a specific congressional mandate directing the FTC to regulate AI company hacks, any effort by the agency to redefine or expand its rules would almost certainly be challenged in court.

Civil lawsuits and state policymaking offer additional paths to investigating or regulating AI companies.

Currently, Florida is investigating OpenAI over the HuggingFace hack, while a nonprofit that sued OpenAI earlier this week has cited alleged violations of California law.

In his testimony, Ohm said that if Congress was serious about preventing agentic hacks, it should not pursue federal legislation preempting state AI laws. He called states “laboratories of democracy,” that can experiment with different forms of regulation and lawmaking.

Others agreed with that approach.

“Obviously this is a topic that the federal government doesn’t love, states getting involved in this space, but it just takes too long for action to come through Congress,” said Kajunju. “I think the quickest way to getting us to a better place will be a really good state law.”

New legislative remedies

On the Hill, members of Congress are working through the same questions as they consider legislative remedies.

At a Senate Homeland Security Committee hearing Wednesday, Sen. Josh Hawley, R-Mo., took a minute at the outset to describe the volume of agentic hacks affecting outside entities that frontier companies appeared to have missed for months. He named affected targets one by one, including major online code repositories like HuggingFace, Australian and U.S. government websites, obscure foreign-language wiki sites and other parts of the internet.

After weeks of investigations uncovered additional, previously unreported incidents in which models escaped testing environments and hacked victims, Hawley said it was “time to have a conversation about who bears responsibility” for the fallout. He added, “as soon as the AI executives say ‘we got a real problem here, our product is out of control,’ the very next words out of their mouths are, ‘but we’re not responsible for it.’”

Hawley said the committee invited OpenAI CEO Sam Altman to testify at the hearing, but he declined. Hawley then accused frontier AI companies of emphasizing their products’ danger while pushing for legal antitrust exemptions and only supporting government action if “they can write all the regulations.”

“I’d suggest that maybe we start with some federal legislation…and we can use existing statutes to do it, I propose using the Computer Fraud and Abuse Act,” said Hawley. “It’s already on the books, we can just update it to say that for developers – that’s the companies – if you develop these agents and train them in a reckless fashion and they go on to hack and destroy stuff, you’re liable.” 

Like other legal experts, Hawley said he believes a CFAA prosecution requires a human actor or organization that intended to commit a crime.

Another Senator, Ron Wyden, D-Ore., said he was also working on legislation related to the hacks. 

“The big AI companies should be held responsible if their agents hack other companies, government systems or foreign websites,” said Wyden in a statement to CyberScoop. “In my view there’s a question about whether the current CFAA would apply to the recent hacks. I’m working on a narrow update to the law to ensure Anthropic, OpenAI and other big AI companies can be punished when their agents run wild.”

Sens. Mark Warner, D-Va., Brian Schatz, D-Hawaii, and Andy Kim, D-N.J., introduced a bill that would create an AI Safety Board at the Department of Commerce. That board would evaluate emerging AI risks and establish safety and technical standards.

The Trump administration’s testing regime with AI companies is entirely voluntary, applies to only certain models, and requires testing no more than 30 days before release. Under the Democratic bill, frontier AI companies would be forced to submit models for testing 45 days before release. They would also be legally required to comply with government safeguards related to models discovering and exploiting software vulnerabilities without explicit human direction. Companies could face fines of up to $250,000 per violation, per day.

When asked whether the CFAA or other federal statutes could or should be used to prosecute companies when their AI systems hack, Warner said that companies’ claimed lack of intent to harm should not become a catchall legal excuse for avoiding responsibility. AI companies have said they never directly prompted or suggested that their models hack or commit crimes.

“AI models are tools and if I buy a power tool and deliberately misuse it, that’s my responsibility,” said Warner. “But if a defect causes that tool to behave in a dangerous way, we don’t absolve the manufacturer simply because someone else was using the tool when it malfunctioned. As AI systems become capable of acting autonomously, we need to ask what principles of responsibility should apply to the companies that design and deploy them.”

The post The legal questions raised by agentic AI hacks appeared first on CyberScoop.

National cyber director: Government-industry collaboration vital to managing AI risks, competition with nations

Collaboration with industry is key to balancing AI security risks and benefits, as well as staying ahead of China and other adversarial nations, National Cyber Director Sean Cairncross said Thursday.

The Trump administration is facing pressure from some quarters of Capitol Hill and even some artificial intelligence executives to establish regulations or embrace legislation to guard against the technology’s risks, something the president himself has rejected.

“We’ve never faced a world where our adversaries have the frontier in this space, and so our attempts to optimize that innovation and security is is something that is ongoing, but is increasingly efficient, and it depends on our relationship with industry and our ability to work collaboratively among the the interagency,” Cairncross said at the AI Edge event hosted by The Washington Post.

That collaboration is ever-increasing, he said, such as with the National Institute of Standards and Technology’s Center for Advancing Innovation and Standards for Super Intelligence (CAISSI).

“Industry coordination on this, across critical infrastructure sectors, is improving both on industry-to-government and within industry,” he said. “There is collaboration with CAISSI and others as well to do evaluation and testing on these models. That includes work on guardrailing, sandboxing, et cetera.”

But “we’ve seen in the past, once the government is introduced into this space directly, there is a tendency for the government to start to want to adjust the dials directly, and it is difficult to reverse that,” he said. “I think that would slow, at this point, the innovation cycle that is to our benefit.”

One of the things that has increased the calls for stronger government action is when OpenAI acknowledged that its AI agents went outside testing to hack Hugging Face in July.

“Since that incident,” Cairncross said, “the engineering work that’s gone into improving systems awareness of that has increased by an order of magnitude.”

But the AI companies need to secure themselves against China for the United States to stay in the lead, he said.

“Both on the hardware side and on the computer science side and engineering, we’re in the lead. I think our lead is significant,” Cairncross said. “The Chinese have designed a sort of fast follow that relies quite a bit on distillation efforts … And I think industry is increasingly aware of this: that their systems are secure, that the technology, as it’s being developed, is protected.”

Other administration officials have called out China for allegedly using distillation to train its models. In July, Michael Kratsios, who leads the White House Office of Science and Technology Policy, claimed that Moonshot AI, a Beijing, China-based AI company, had distilled Anthropic’s recently released Fable model to develop its own K3 model.

On Wednesday, OpenAI said clusters of activity tied to Moonshot AI were part of a “coordinated” distillation campaign.

Cairncross said earlier this week that the U.S. government is collaborating with industry to integrate AI into critical infrastructure for security purposes. 

Cairncross said the Trump administration wants to make sure national security systems do the same. One of his office’s pilot programs is with the Defense Department and the Cybersecurity and Infrastructure Security Agency “that touches on the defense infrastructure in particular,” in addition to a pilot on rural hospitals.

The post National cyber director: Government-industry collaboration vital to managing AI risks, competition with nations appeared first on CyberScoop.

OpenAI reveals ‘novel’ encryption bypass used in distillation attack 

OpenAI said it disrupted a “coordinated campaign” to distill and extract reasoning capabilities from its AI models, pointing the finger at a Chinese rival.

On Wednesday, OpenAI said it first spotted low-level activity on July 1 that gradually increased until July 24 and 25, when it observed 16,000 prompts from 4,000 users that fit a similar “relevant extraction pattern.” The number of suspicious users had climbed to 15,000 by July 28, when OpenAI said it “fully disrupted” the operation.

The company called the attackers’ method “novel.” They copied encrypted reasoning data from one conversation, then asked the model in a separate conversation to decrypt the content and transcribe it in plain text. Outside researchers reported a similar vulnerability to OpenAI in August.

“The operators did not break our encryption, compromise a database, or gain direct access to stored user conversations,” OpenAI wrote in an unsigned blog post. “Instead, they manipulated model interactions so that protected reasoning could be reproduced in forms visible to the requester in a coordinated, scaled manner that violated our terms of service.”

OpenAI said it’s unclear whether all the activity is related, but individuals working on behalf of Moonshot AI, a China-based rival AI company that has, in the past, been accused of distilling U.S. models, were behind a “core cluster” of the activity.

OpenAI’s blog post does not cite any technical evidence or reasoning for its attribution. Moonshot AI’s Kimi is one of several Chinese open-source AI models that are offering users and organizations good-enough performance for free or at a low cost.

American AI companies and the U.S. government have accused Chinese companies like Moonshot AI of conducting “systematic” distillation attacks on their latest models. Cybersecurity experts at Google and other cybersecurity firms say Chinese companies rely on black or gray markets to acquire thousands of individual accounts for models like Claude and ChatGPT. They then flood those models with millions of prompts and data requests that help them copy model capabilities and training data.

OpenAI told CyberScoop that it was not sharing any additional information “for security reasons.” CyberScoop has reached out to Moonshot AI for further comment.

According to OpenAI, the same vulnerability exists in other AI models, and it has shared information about the incident with groups like the Frontier Model Forum.

Beyond banning offending accounts, OpenAI said it improved signup and infrastructure controls and expanded network monitoring. It also fixed a bug that allowed users to take encrypted data from one conversation and decrypt it in another. 

The post OpenAI reveals ‘novel’ encryption bypass used in distillation attack  appeared first on CyberScoop.

As AI world debates security, NVIDIA releases open source tools for agents

Amid growing concerns from both the public and policymakers about cyberattacks involving advanced AI systems, NVIDIA has released a new open software security platform for AI agents.

The Open Agent Safety Platform, according to NVIDIA, will be “an open software platform and reference system design with full-stack governance and control across the software and hardware, compute and robotics systems that run agents.”

More than 100 organizations from the AI industry, including Anthropic, Arm, Microsoft, SpaceXAI, Palantir and JPMorgan Chase, have committed to using the platform to improve security in their products.

Stronger sandboxes and more advanced monitoring are pillars of NVIDIA’s strategy for tackling “rogue” AI agentic hacks, and the platform offers a pair of tools that are meant to help contain and restrict agent activity. 

According to a corresponding technical blog, OpenShell, built on Apache 2.0 open source software, is a tool for securing runtime execution for AI agents in sandbox testing environments. AI system operators can define files, networks, tools, processes and credentials that an agent has, and test whether those guardrails hold before introducing them to enterprise networks.

It also includes security updates for NVIDIA’s Bluefield 4 data processing unit (sometimes called a “data center on a chip”) that enables out-of-band monitoring of AI agent behaviors and security policy enforcement.

On X, NVIDIA CEO Jensen Huang called the platform “the beginning of an open ecosystem to build the trust layer for safe agent systems.”

To do this, security work must become “foundational” to AI and the industry’s “full promise can only be realized when people have confidence that AI is being built to be safe and deployed with wisdom and responsibility.”

“Trust and innovation are not in conflict,” Huang wrote. “Safety is how trust is earned. We must build not only the most capable AI, but the most trusted AI, so that this extraordinary technology can realize its enormous promise for the world.

NVIDIA manufactures advanced computer chips that power much of the U.S. commercial AI industry. After models from Anthropic, OpenAI, Meta and others escaped sandbox protections during testing and breached real organizations, some AI industry leaders – including Anthropic CEO Dario Amodei and OpenAI CEO Sam Altman –  suggested AI systems are too advanced to be contained.

Huang has criticized those views, arguing that frontier AI companies and their supply chain partners must improve their security posture. Huang said last week he opposes government regulations or mandates on the AI industry, unless they promote growth.

In an interview with CNBC on Monday, Huang said he believes sandboxing and larger AI security issues are “a technically solvable problem.”

“I think the answer is we hope it’s an engineering problem,” said Huang. “I believe it’s an engineering problem, I know it’s an engineering problem, and we all need to hope that it’s an engineering problem. [If not] it’s not solvable, so the fact that all of these companies still are advancing the state of the art is because they also believe it’s solvable.”

Aviv Nahum, CEO of Above Security, told CyberScoop that NVIDIA’s announcement reflects industry recognition that model training alone cannot ensure safety. 

NVIDIA is essentially arguing that for agents to perform safely in real-world environments, “some of the enforcement must live outside the model, in a layer the agent cannot simply reason around or modify.”

“What this announcement says to me is that the industry is finally converging on a basic cybersecurity principle, [that] model alignment is not a substitute for security engineering,” said Nahum. “Sandboxes, identity, least privilege, independent monitoring and containment are not new ideas. What is new is that we now have autonomous software capable enough that failing to apply those principles becomes much more consequential.”

The post As AI world debates security, NVIDIA releases open source tools for agents appeared first on CyberScoop.

New bill would create federal investigative body for AI-driven hacks 

A new Democratic bill in Congress would establish a federal Cybersecurity and AI Board of Investigations to provide independent government oversight of cyberattacks carried out by AI agents, following recent hacks by models run at companies like Anthropic, OpenAI, Meta and others.

The bill, introduced by Sen. Ed Markey, D-Mass., would attempt to establish a federal mechanism to investigate incidents where AI models escape sandbox environments and access live internet systems.

Currently, frontier AI companies like OpenAI and Anthropic largely control the investigation and public reporting of such incidents. Markey and other critics argue that these companies have too much control over investigations and reporting due to their financial and legal interests. 

“Despite the unprecedented depth and scale of recent AI-enabled cyberattacks, the public is learning critical details piecemeal,” Markey said in a statement. “Building stronger defenses requires a full accounting of what goes wrong, and we cannot depend on companies with little incentive to disclose their failures to give us one. We need the Cybersecurity and AI Board of Investigations to get to the bottom of major incidents and give companies and the government the critical information necessary to build resilience and better secure our economy and our country.”

Although frontier AI companies maintain external red-teaming programs and allow limited access to organizations like METR and Redwood Research, they control the scope, terms and time frames of those engagements.

The board, which would coordinate with the secretary of commerce, could subpoena witnesses and conduct “independent and impartial reviews and assessments” of AI agent-led hacks that impact federal information systems or critical infrastructure. 

It would be led by five members, appointed by the president and confirmed by the Senate for five-year terms, with no more than three members from one political party.

The board would also investigate systemic vulnerabilities in the AI supply chain, so-called “near misses” where unauthorized agent-led hacks were “narrowly averted,” and gaps in federal regulatory oversight. It would have technical staff including engineers, malware analysts, and digital forensic experts.

The board would “operate independently from regulatory review and enforcement actions without assigning legal fault or liability for any review and assessment” it conducts, according to the bill.

OpenAI confirmed Wednesday its AI agents breached a statistics portal used by the Australian government’s social services agency, Services Australia. Though the breach happened in June, OpenAI learned of the incident in August. Australian Prime Minister Anthony Albanese said the company did not notify him until Sept. 10, when it sent findings to a general government email inbox, according to the BBC.

The post New bill would create federal investigative body for AI-driven hacks  appeared first on CyberScoop.

OpenAI, Ukraine partner on ‘Daybreak’ program to protect power grids and water systems 

OpenAI and the Ukrainian government have agreed to a partnership that will provide AI tools and subsidized computing resources to better protect the nation’s critical infrastructure from cyberattacks.

The agreement, announced Wednesday at OpenAI’s New York office, will provide Ukrainian cybersecurity officials with access to advanced AI models designed for cybersecurity work through the company’s Daybreak program. OpenAI said it is also pledging over $1 billion in subsidized tokens to support the initiative.

During a panel discussion Dmytro Kushneruk, consul general of Ukraine in San Francisco, outlined how the tools would be used for cybersecurity automation, including functions such as incident response, threat triaging, login analysis, inventorying systems, code analysis and validating vulnerabilities.

In nearly all cases, Kushneruk said the primary benefit was carrying out those functions at machine speed. But this speed is meant to complement, not replace, Ukrainians’ human expertise.

In regard to incident response Kushneruk said humans must view “thousands and thousands of these logs and they have to find what’s really important, that’s why AI can give capable defenders really much greater advantage and leverage.” 

“This is why the object is not to replace the cyber defender with AI, but to make sure the cyber defender acts faster,” he added.

Kushneruk said that for Ukraine, the partnership “is really not about protecting computers, it is about actually keeping our country running.”

Ukraine faces approximately 6,000 cyberattacks per year, or about 15 per day, according to Kushneruk. Over the past twelve years, the country’s critical infrastructure, including electricity and water systems, has endured sustained attacks from Russia in the form of cyberattacks and physical strikes.

Since Russia’s 2022 invasion, Ukraine’s critical infrastructure has been under constant threat. While missiles remain the primary concern, Kushneruk said Ukraine has been preparing to protect vital services since Russian GRU hackers shut down the country’s power grid in 2015. 

He added that while the country was “maybe not so much prepared” to deal with the fallout in 2015, it improved over time, including the resilience displayed in 2025 when trains kept running after Russian hackers attacked Ukraine’s railway system.

Some national security experts and congressional committees have explicitly cited the resilience of Ukrainian critical infrastructure as a model for U.S. industry.

Naz Durakoğlu, minority staff director of the U.S. Senate Foreign Relations Committee, said there is “pretty much across the board” agreement between the parties in favor of similar adoption of defensive AI tools by U.S. critical infrastructure operators, though issues like regulation remain sticking points.

“This is something that’s already happening, and frankly, it’s just kind of a basic duty of government to make sure that when you turn the tap on, water comes out, the electricity doesn’t go out, and hospitals keep running and treating patients,” said Durakoğlu. “So there is a broad understanding that this is a major issue, and I will say seeing what Ukraine has to go through day-to-day is also a huge wake-up call to our members on a bipartisan basis.”

OpenAI has publicly pushed for its product, and AI at-large, to be used to solve these types of problems. Company president and co-founder Greg Brockman signed an open letter released earlier this year calling for “collective action” and widespread use of AI models to find and fix vulnerabilities before the rest of the world,  including foreign governments and cybercriminals, got access to the same capabilities.

According to Politico, OpenAI CEO Sam Altman met with U.S. power companies in July to discuss using AI to protect the nation’s electrical grids.

On Wednesday, OpenAI’s national security policy head, Sasha Baker, said the company felt “urgency” to try to strike similar agreements with other governments and industries.

“There’s this period of time where we’re really rushing to get [these tools] in the hands of critical infrastructure operators, of governments around the world, of people who want to patch systems, defend their networks, remediate vulnerabilities because we know as these tools proliferate out there in the ecosystems, there are going to be bad guys out there that also try to use them,” said Baker. “So, we have this window of time to take action and we’re really motivated by the idea that we need to act with some urgency.”

The post OpenAI, Ukraine partner on ‘Daybreak’ program to protect power grids and water systems  appeared first on CyberScoop.

Citing China, President Trump doubles down on hands-off approach to AI regulation

President Donald Trump continued to defend his administration’s hands-off approach to AI regulation in the wake of hacks carried out by U.S. commercial frontier models that have rattled policymakers and industry veterans and spurred calls for more regulatory oversight.

In a Truth Social post Monday, Trump dismissed worries from critics that “AI is going to kill us,” comparing them to complaints from environmentalists about climate change, which he also alleged was a false narrative. He also posited that nothing may matter more than future U.S. dominance of the technology over geopolitical rivals like China.

“Whoever wins AI, WINS!” Trump posted. “We are leading now over China, and everyone else, and I’m going to keep it that way! I’m not going to stifle Growth, of something that will be bigger than the Industrial Revolution, or the internet, itself.”

Trump has previously suggested that good leadership is the only regulation the U.S. needs for artificial intelligence. He later claimed the Department of Justice was ready to “rein things in” if companies overstepped, but offered no specifics on enforcement, legal authority, or where he would draw that line.

“We will be careful, and that’s why we have the Department of Justice, and other Law Enforcement bodies, that will rein things in if we have to, but I will only encourage AI or, SI (SUPER INTELLIGENCE)!” Trump concluded.

Secretary of the Treasury Scott Bessent recently told Congress that private lawsuits could force AI companies to institute better security, saying it’s clear what the government “shouldn’t do on safety is to give these labs a liability exemption, which is what they are asking for.”

“The best way to guarantee safety is that the creators are liable for what they build and generate,” Bessent said.

Beyond existential fears, critics also argue that inadequate regulation or cybersecurity controls in current AI systems make them impossible to fully control or monitor.

Recently, former President Barack Obama criticized the argument from Trump administration officials that the free market will naturally push industry toward self-regulation and that “these companies will solve the safety issues because they have every incentive to do so.”

“If it turns out to be dangerous, people will just sue them and they’ll be worried about financial liability,” Obama said last week in remarks at Colgate University in New York. “That’s not how we treat airlines or drug companies or food companies.”

The Trump administration issued an executive order earlier this year that set up a voluntary testing regime for some commercial frontier models, largely at private industry’s discretion. That order was significantly delayed and altered by AI industry boosters to ensure that governmental review did not cause companies to postpone their release timelines for new models.

That agreement did not last long before fast-moving events caused the administration to strike another, non-public agreement with frontier AI companies like OpenAI, Anthropic and others governing pre-release testing for models.

But the Trump administration has consistently argued that regulation will harm, not help, U.S. innovation and global competitiveness, and the threat of China frequently looms large in those discussions.

Experts believe China’s AI models are behind U.S. models at the top of the market, where OpenAI and Anthropic have consistently pushed the frontier limits of model capabilities. But Chinese lower and “middle class” models are often cheaper, more efficient and can even outperform more powerful models because users can dedicate exponentially more tokens for their tasks.

The U.S. government has accused Chinese AI companies of conducting widespread, “systematic” distillation of U.S. frontier models, with the implicit encouragement of Beijing.

In defending the administration’s approach, David Sacks, co-chair of the President’s Council of Advisors on Science & Technology and a top adviser on AI issues, specifically cited the threat from China and other countries that he claimed would not be subject to similar restrictions.

“We’re not the only country that has advanced AI labs, and as the president declared…we have to win this AI race,” Sacks told Politico in May, later adding “I think that’s the first thing to recognize is that if somehow we slow down or stop AI development, it doesn’t mean that AI progress is going to stop. It just means it’s going to happen in other countries and specifically China.”

Some observers have alleged that despite their larger differences, top leaders in the U.S. and China may view AI similarly at the strategic level, specfically that increased adoption – and risks – of AI are inevitable.

Ronan Murphy, director of the tech policy program at the Center for European Policy Analysis, posited that while there may not be a formal agreement between the two countries, “they share views both in Beijing and in Washington, particularly in the White House, of: you have to allow this to happen.”

“Clearly there’s a call for regulation from many quarters of AI in the U.S. and elsewhere, but in the White House – and we heard David Sacks talking about it [recently] – It’s ‘let them cook,’ and the Chinese approach seems to be the same,” said Murphy in a press briefing. “So there might be consensus at that level, if nothing else.”

The post Citing China, President Trump doubles down on hands-off approach to AI regulation appeared first on CyberScoop.

Microsoft and partners disrupt EvilTokens, a comprehensive cybercrime service for financial fraud

Microsoft, along with a group of industry partners, disrupted EvilTokens, a short-lived but highly consequential cybercrime platform that investigators linked to more than 12,000 compromised Microsoft customer email inboxes across more than 10,000 organizations globally, the company said Tuesday.

Acting on federal court order Sept. 15, Microsoft and partners seized 50 websites the phishing-as-a-service used for operations and disabled more than 175 domains linked to EvilTokens’ supporting infrastructure. 

EvilTokens, launched in February 2026, was “a powerful cybercrime platform that used AI at every step of the attack chain — from compromising email accounts to designing intricate roadmaps for financial fraud and scams,” Steven Masada, associate general counsel and general manager of Microsoft’s Digital Crimes Unit, wrote in a blog post.

About 1,000 cybercriminals used EvilTokens over the course of its operation, a Microsoft spokesperson told CyberScoop.

The service was centered on an AI-style chatbot that cybercriminals used to analyze victims’ inboxes, identify trusted relationships, payment authorizations and other sensitive details that could facilitate fraud.

“AI was not simply helping attackers write more convincing messages. It helped them decide who to target, who to impersonate, and how to most effectively exploit the relationship to extract as much money as possible,” Masada wrote. 

EvilTokens was one of the most widely used phishing-as-a-service platforms prior to its takedown. It facilitated business-email compromise campaigns by stealing session tokens that allowed cybercriminals to sift through a victim’s inbox and maintain persistent access.

“We cannot estimate the total fraud attributable to all EvilTokens activity. However, we were able to correlate at least 13 complaints filed with the FBI’s Internet Crime Complaint Center to EvilTokens-linked activity, representing approximately $1.7 million in reported losses,” a Microsoft spokesperson said. “Because many incidents go unreported and not all victims can be definitively linked to specific campaigns, we believe this is a conservative estimate.”

Victims of EvilTokens were largely concentrated in the United States, Canada, the United Kingdom, Australia, India and France, according to Microsoft. SpyCloud, which supported the takedown, identified compromised email domains spanning 79 countries.

Microsoft said it also identified two men behind EvilTokens — Felix Utomi and Waidi Segun Adams — and attributes the development and support of the platform to Storm-2992, a threat actor unaffiliated with any other known cybercrime groups.

The United Kingdom’s Metropolitan Police acted on that information Sept. 18 when it served warrants in the greater London area, arrested the men accused of making articles for use in fraud and money laundering and seized their digital devices.

The Metropolitan Police said it received information from Microsoft about EvilTokens’ administrators in August. Utomi and Adams were released on bail as the investigation continues. 

“The two primary operators identified in our investigation were residing in the U.K.,” a spokesperson for Microsoft told CyberScoop. “While our investigation focused on those individuals, we believe others may have supported the operation in various capacities.”

Microsoft’s legal filing in the U.S. District Court for the Eastern District of Virginia refers to five additional unidentified people allegedly acting as support personnel and users.

Microsoft and others involved in the EvilTokens takedown, including Health-ISAC, Cloudflare, OpenAI, Shadowserver and TRM Labs, didn’t fully quantify how much fraud the service enabled, but it gained popularity quickly among cybercriminals and was lucrative for its operators.

Coinbase, which also aided the investigation into EvilTokens, said it traced about $1.1 million in revenue for EvilTokens from its paying customers. The virtual currency company’s threat researchers found more than 1,000 deposits to EvilTokens from more than 700 distinct addresses through June 2026. 

Operators sold access to the service through Telegram for a $1,500 initiation fee and a recurring $500 subscription. EvilTokens significantly lowered the barrier to entry for cybercriminals by including specialized tools for identity attacks, cloud systems, social engineering and financial fraud in a single interface.

The service allowed cybercriminals to map organizational structure and permissions in Microsoft Graph, which enabled lateral movement, researchers said. With active tokens gained through a collection of highly-targeted phishing lures, cybercriminals consistently bypassed multi-factor authentication, email gateways and endpoint security tools.

Microsoft said the platform’s creators developed portions of the platform with AI and it uncovered capabilities from multiple AI models. 

“It packaged much of the criminal process into a commercially run service, complete with subscription pricing, customer support, management dashboards and tools designed to move customers from account access toward financial exploitation,” Masada added.

The companies and organizations involved in the globally-coordinated takedown identified and notified potential victims, shared indicators of compromise and shared intelligence with law enforcement about EvilToken’s operators and some of its customers.

Experts advised organizations and employees to treat unsolicited device codes as a red flag, assume compromised accounts are fully cataloged in minutes, and independently verify requests to change payment information or redirect funds.

“The infrastructure supporting EvilTokens has been disrupted, but the model it demonstrated will not disappear with it,” Masada warned.

The post Microsoft and partners disrupt EvilTokens, a comprehensive cybercrime service for financial fraud appeared first on CyberScoop.

Researchers use AI to find widespread software decoder flaw 

Researchers said they used Anthropic’s Claude and OpenAI’s Codex to identify a damaging flaw embedded in a popular software decoding tool that could leave major internet platforms, enterprise services, and web frameworks vulnerable to data theft and remote access.

The vulnerability, nicknamed HEIF Heist, refers to the malware’s ability to trigger memory corruption errors in affected software, allowing the attacker to pilfer sensitive data from its victims. In a report published Thursday, the researchers laid out the potential damage an attacker could cause, including gaining access to internal OpenAI repositories, leaking user files, access tokens, and other sensitive data for online services like Amazon Web Services, and gaining remote code execution privileges across a range of online services, including Meta’s core product suite, GitHub Enterprise servers and open-source internet forum Discourse.

“Even when Remote Code Execution isn’t immediately achievable, the attack primitives may still allow arbitrary heap disclosure, letting an attacker ‘heist’ in-memory data such as other users’ data and environment variables,” wrote Hacktron researchers Harsh Jaiswal, Mohan SRK, Rahul Maini and Sudhanshu Rajbhar.

The researchers relied heavily on AI systems, including frontier models from OpenAI and Anthropic, to conduct their research. Attribution for the research is described as being “led” by the Hacktron human researchers “assisted by Hacktron Harness, GPT-5.6 Sol, and Opus 5.”

According to the research, the attack exploited the way that code parsing tools in many popular software decoders — specifically libheif and libde265, used to parse C and C++ software — process certain image files.

By uploading HEIF, HEIC and AVIF image files corrupted with malicious code, the attacker could bypass most of the victim’s application layer defenses, in many cases achieving remote code execution privileges for accounts or products tied to major AI and tech brands.   

While the latest version of libheif has been patched, the researchers said “any deployment lacking the latest upstream security patches is potentially vulnerable.”

In one incident detailed in a Sept. 13 blog, Jaiswal, Maini, and Hacktron researcher Mohan Pedhapati described how chaining two vulnerabilities, including an image parser flaw, could compromise OpenAI employee accounts.

With access to the compromised accounts, researchers could reach OpenAI’s internal repositories. As a proof of concept, they opened a pull request in the company’s “monorepo,” a centralized library where code is shared across projects, using the employee’s Codex credentials. 

According to a timeline provided by the researchers, the flaw was discovered on July 25 and patched within days. They said the entire attack, from discovering the initial vulnerability to gaining access to the repositories, took less than 72 hours. OpenAI paid them a bug bounty of $6,500 for their work.

Given that AI models are increasingly integrated into enterprise and personal networks, an attacker exploiting HEIF Heist could have accessed far more than just OpenAI’s systems and data.

“Until two months ago, a user or OpenAI employee logging into OpenAI’s own help forum could have had their ChatGPT and Codex accounts taken over,” the researchers wrote. “Since people can connect various services to Codex and ChatGPT, the scope of what we could theoretically access was huge, including GitHub, Slack and emails.”

CyberScoop has reached out to OpenAI for comment on the research and additional information.

At the same time, the researchers said the attack paths they found were not particularly easy or efficient to exploit.

“Exploitation requires fingerprinting the target version and tailoring the payload images,” the blog stated. “Some of our RCE attempts landed only after thousands of image uploads. That said, an AI agentic approach with a frontier model like GPT-5.6 Sol cut exploit development time down to roughly 1 to 3 days from initial probe to remote RCE. A motivated attacker can convert a vulnerable upload endpoint into RCE or an info leak.”

The post Researchers use AI to find widespread software decoder flaw  appeared first on CyberScoop.

The AI hacking apocalypse is not inevitable

The past few weeks have “felt very strange” for Juan Andres Guerrero-Saade.

Like many, he is trying to sort through the spate of frontier-model AI agents from OpenAI, Anthropic, Meta and others hacking their way onto the open internet over the past few months, particularly amid the already-heated national debate around the emerging technology and its impact on society.

Guerrero-Saade, a fellow for AI and security research at SentinelOne and an adjunct professor at Johns Hopkins University, said the hacks are worth taking seriously, but at a time when businesses and open-source maintainers should be focused on further hardening their systems and policymakers should be discussing new solutions,  “what we see is cybersecurity being used essentially as an excuse for these AI doomer arguments.”

The incidents have spawned those “doomer arguments” amid an intense public debate about the technology, the pace of industry development, and whether government and the private sector are doing enough to protect against “doomsday”-type scenarios, where AI systems take over or attack large parts of the internet or society.

Guerrero-Saade is among a growing chorus of cybersecurity professionals who say that while AI systems pose real, unique threats to our systems, the apocalypse is far from inevitable. Most of the public concerns around the incidents, let alone worries about killer AIs attacking critical infrastructure, assuming control of the internet and wiping out humanity, are either technically impossible or can largely be controlled through established cybersecurity principles.

There is this “narrative or magical thinking of ‘Well, AI is going to be able to hack everything, and therefore it can control everything, and therefore it’s going to kill us all,’” he told CyberScoop. “And you [think] these just don’t add up. They’re not very well-reasoned arguments.”

This fatalistic narrative tied to AI’s eventual dominance doesn’t hold up under scrutiny, according to experts CyberScoop spoke with. In recent conversations, cybersecurity and national security professionals raised questions about both the technical solutions OpenAI and Anthropic use to contain their models, as well as the glaring absence of federal oversight from federal regulators or truly independent third-party review.

For example, Jacob Coxon, an Anthropic employee who resigned over AI safety concerns, told CBS News that frontier models could not be “unplugged” by humans once deployed because the model would copy itself to thousands of other computers connected to the internet.

By contrast, Matt Tait, a former information security specialist at UK signals intelligence agency Government Communications Headquarters (GCHQ), pointed out that the models run by Anthropic and other frontier companies require extremely expensive, “ultraspecialist” machines that “are functionally supercomputers.”

“There is a zero chance that Anthropic’s most capable models will be able to extract their own model and run in the wild, because those supercomputers essentially only exist in datacenters,” Tait said.

“Not a credible warning”

Other former cybersecurity government leaders say the agentic hacks represent a failure by regulators and industry to deploy known technical and policy options that make it harder for these types of incidents to occur.

Matt Hartman, former deputy executive assistant director for cybersecurity at the Cybersecurity and Infrastructure Security Agency, said “we should not accept harmful AI behavior as inevitable or unmanageable.”

“There are meaningful steps companies can take to monitor agent activity, constrain permissions, detect anomalous behavior, and build stronger safeguards into how these systems operate,” said Hartman, now a chief strategy officer at Merlin Group. “Those controls will inevitably involve trade-offs in capability and speed, but that’s a familiar cybersecurity challenge. Our goal should be to manage the risk without unnecessarily limiting the enormous benefits AI can provide.”

Ciaran Martin, former head of the UK’s National Cyber Security Centre, took issue with the way the CEOs of frontier AI companies have framed the threat of “rogue” AI behavior as inevitable, while issuing dire warnings about future threats and capabilities with little transparency.

Martin’s comments came after an essay published by Anthropic CEO Dario Amodei that cited the threat of a HuggingFace-style swarm of agents that could create a botnet capable of “taking over the entire internet” within 6-12 months.

This, Martin said, “is not a credible warning,” because it doesn’t explain how the exploitation would function, how such a botnet would persist on the internet, or how it would escape law enforcement. 

 “It assumes no monitoring of systems, no anti-virus, no DDoS protection, no network segmentation, no incident management, no nothing of any kind of the cybersecurity on the global Internet of the type that has developed over the last 30 years,” wrote Martin. “For a claim of this magnitude, there is neither evidence for the contention nor a credible account of a path to this outcome.”

Meanwhile, some federal government cybersecurity leaders have touted the technology’s disruptive potential and called for more widespread adoption of AI tools by defenders.

Joseph Alm, assistant secretary of cyber, infrastructure and risk resilience at the Department of Homeland Security, said classified systems may retain stronger protections. But for most other data, AI models are “just going to know things and be able to infer things about the world, and we’re going to have to adapt to that as almost inevitable.”

Asked by CyberScoop whether the government or frontier AI companies could be doing more to prevent or deter their models from carrying out unauthorized hacks via agents, Alm cited recent efforts by the Trump administration this year to establish pre-release testing of commercial models as a step in the right direction. But he called unauthorized AI agent hacks “a new threat class” that is different from previous threats and can be easily distributed to users through open-source software today.

“I think what we can do is…encourage the building of good sandboxes, so that the best models aren’t used for this and the stuff you see out in the wild is the kind of detritus that you can actually respond to effectively and control your networks,” said Alm.

Other experts have shared similar concerns. Earlier this month, CrowdStrike CEO George Kurtz recently warned of a new threat class emerging alongside nation-states, cybercriminals, and hacktivists: “the agent state.” By pairing AI systems with small human teams, these operators can now match the speed, scale, and sophistication of government-backed hackers.

“It took a nation to fund the talent, the tooling, the infrastructure, the patience,” said Kurtz. “That scarcity is over.” 

To be sure, frontier AI companies tout their commitment to both approaches. OpenAI and Anthropic have rolled out an array of cybersecurity partnerships, external red-teaming programs, vulnerability disclosure programs and cybersecurity technical advisory bodies filled with cybersecurity experts.

Mohammed Husain, strategic delivery lead for government at OpenAI, told CyberScoop that the company deploys both internal safety guardrails for their models and relies on outside cybersecurity vendors for additional expertise.

Internally, OpenAI focuses on vulnerabilities at the training level: filtering data poisoning attacks, blocking harmful datasets, and using network controls to prevent prompt injections. For other security layers like sandboxing, identity management, networking controls, they outsource to external vendors. 

“I don’t think OpenAI has all the answers here but what we do as a research lab is we’re going to focus on levels of protection we have expertise in and we partner to self-complement,” said Husain.

AI safety vs. AI cybersecurity

In response to the HuggingFace hack, OpenAI and Anthropic have allowed third-party organizations, such as nonprofit AI research firms METR and Redwood Research, to investigate. But multiple cybersecurity professionals told CyberScoop that both firms lack incident response experience and focus primarily on AI alignment and safety. Their reporting on the hack also lacked critical details: network monitoring logs, telemetry, and other data standard in cybersecurity threat intelligence reports.  

METR president Chris Painter addressed those general concerns in a post on X, saying since 2022 the organization has worked with Google, Anthropic, OpenAI, Meta, Amazon and others on investigations and third-party evaluations. Painter said none of the AI companies fund METR and that his employees are not uniformly “doomer” or “accelerationist” around AI.

Painter also said METR’s work ensures that if AI systems become autonomous or “rogue” within a company, there are ways to share that information with governments and people “outside the company’s walls.”

“We don’t accept money from frontier AI companies,” wrote Painter. “They haven’t paid us for our work, and we don’t accept donations from them or their employees. As we’ve shared previously, multiple frontier AI companies currently provide us with free access to their models in order to perform our evaluations, research, and engineering.”

AI safety and AI cybersecurity advocates take different approaches to securing “rogue” AI behavior. Safety advocates focus on aligning models around ethical training and behavior. Cybersecurity advocates argue that technical and regulatory controls must go further—actively preventing models from accessing what they need to carry out malicious behavior.

Guerrero-Saade said sandboxes in particular can easily be programmed with aggressive cybersecurity monitoring in order to spot when something odd may be happening and react in real time.

“I can’t think of an easier situation in which to set up trip wires, set up configurations like DNS servers, just different parts where you can say ‘Hey, anomalous behavior is happening,’” he said. “We should have been able to tell this immediately, not weeks and months later. So watching [the AI hacking incidents] go down is a little ‘crazy-making’ because we’re seeing things that, frankly, look like neglect, negligence, people just mishandling things, and then being told that these are categorically new incidents that mean that AI systems need to be treated completely different from anything that’s come before.”

While cybersecurity experts say AI systems are, at their core, still software, they do operate differently from more traditional code in ways that can make them harder to predict and control.

John Hultquist, chief analyst at Google’s Threat Intelligence Group, said most software has been deterministic. It may have bugs or vulnerabilities, but an expert could generally understand how it would react to certain stimuli, making it easier to design straightforward controls.

AI models are non-deterministic, with far more variability than traditional software. That can break security controls that rely too much on predicting behavior in advance. Using AI to enforce security controls on other AI models faces the same problem: the systems being deployed to control AI are just as unpredictable. 

But people are also non-deterministic, and people have developed systems in other industries and practices to account for that.

Hultquist drew on his Army experience, noting that “they give incredibly dangerous, expensive things to 18-year-olds” and expect responsible use. The military manages this through two types of controls: deterministic ones like strict weapons and ammunition protocols, and non-deterministic ones like human officers who monitor and correct violations.

Similarly, established cybersecurity controls have been used by incident responders to detect and prevent or mitigate ongoing cybersecurity breaches.

“I don’t think we should throw out all the other tools that we have learned to use as well. I think that would be utterly foolish,” he said, later adding “I will say that if we use only non-deterministic tools to figure out when things are happening, we shouldn’t be surprised when we get the wrong answer.”

The post The AI hacking apocalypse is not inevitable appeared first on CyberScoop.

Researchers say OpenAI agents were behind May hacking campaign targeting RubyGems

Researchers say they have discovered thousands of malicious software packages uploaded to an online public software repository that were left by a “swarm” of OpenAI agents.

According to an incident timeline published Friday by researchers Spencer Kitts, Thomas Larsen and Sydney Von Arx, the campaign began May 5 when they observed a handful of suspicious packages being uploaded to RubyGems, a public library for the Ruby programming language. By May 11 and 12, the site saw more than 2,000 malicious uploads from the same actors before RubyGems maintainers halted new user sign-ups for four days to stop the flow.

In one instance, the agents attempted to exploit a very recent vulnerability that had only been discovered this past July that would have given them access to RubyGem user API keys. According to Colby Swandale, the technical lead at RubyGems, the flaw involved an improper cache configuration. While initial access logs showed no evidence of malicious key use, Swandale acknowledged the review was limited in scope and inconclusive. 

According to the report published Friday, the agents also used “disposable” email addresses and exploited another bug in RubyGems platform (since patched) that allowed them to register new accounts and gain API keys without verifying their email address.

The researchers said their understanding, based on discussions with “people in the RubyGems community,” is that OpenAI had yet to disclose the involvement of their agents in the May campaign.

An OpenAI spokesperson told CyberScoop that the company is aware of the incident and said they were in contact with both the researchers and RubyGems to conduct a broader review. The company characterized the episode as “benign,” describing it as routine training runs where agents attempt to access publicly available data.

“Based on our review, our agents used the RubyGems platform to access the internet to carry out benign tasks and retrieve public information,” the spokesperson said. “We’ll continue to investigate as part of our broader review of agent activity during training and evaluation.”

In many ways, the agents were not subtle about their identities or goals.

Days into the campaign, researchers noticed that some of the packages had “oai” in their filenames, while fifteen of them had “oai” set as their author and another listed the email “openaixyz65947@gmail.com” as their point of contact.

They also “clearly regarded what they were doing as hacking,” naming some of their files “hack.rb,” “evil.rb,” “inject.rb” and “exploit.rb.” Other packages were given names like “pwnp999,” “exfiltestwand3,” and “hacksvn,” and comments referring to things like a “malicious probe” or “#hack” are present through the files.

They also said the actors’ behavior was extremely similar to another incident revealed earlier this month where OpenAI agents flooded a German wiki  with thousands of hacking-related posts. OpenAI has confirmed their agents were involved in that incident.

The RubyGems campaign used some of the same retrieval methods as the German Wiki agents, while thousands of malicious packages uploaded included a similar snippet, r.jini.ai, that was contained in the German posts.

Cybersecurity company Socket first flagged the campaign in a threat intelligence report posted May 13, but it does not mention or attribute any of the activity to OpenAI or AI agents.

However, the researchers said they had only limited visibility over the model’s actions and how successful some of them were, noting only OpenAI had the full details.

“This analysis is entirely based on the publicly available RubyGems packages uploaded by these agents,” the researchers wrote. “However, we do not have access to the rest of the AI behavior, in particular the chain-of-thought produced by the model during the incident, which is internal to OpenAI. Therefore, we do not know why the AI agents chose this strategy or whether it was successful.”

OpenAI’s spokesperson told CyberScoop that to date, they have not been able to verify the specific claims about malicious packages or exploitation detailed in the report and are continuing to investigate.

The post Researchers say OpenAI agents were behind May hacking campaign targeting RubyGems appeared first on CyberScoop.

Hawley probes OpenAI over Hugging Face breach

OpenAI is facing mounting pressure from Capitol Hill due to the attack its agents carried out on Hugging Face, while lawmakers voice widening concerns about AI’s potentially existential risks.

Sen. Josh Hawley, R-Mo., criticized OpenAI leadership for what he described as “reckless” activities leading up to the Hugging Face breach, and accused the company of withholding important details from a technical report it released in late August.

The Chair of the Subcommittee on Disaster Management kicked off an investigation into the incident “in light of new, disturbing evidence,” he wrote in a letter Tuesday to OpenAI CEO Sam Altman.

“My investigation will probe this AI hacking incident, along with growing allegations of the existential risk of new AI products,” Hawley added. 

“The Hugging Face incident was an important moment for AI safety and a warning about the risks that can come with increasingly capable AI across the industry,” a spokesperson for OpenAI told CyberScoop. “We conducted an extensive investigation and published a detailed report on what happened, what we learned, and how we’re strengthening our security and alignment practices.”

The lawmaker is seeking detailed internal communications, exhaustive technical information and reasoning behind OpenAI leaders’ decisionmaking and activities surrounding the hack by Oct. 1.

“The American people deserve to know the details of what went on in the Hugging Face incident and other incidents of AI models going rogue,” Hawley wrote. 

He accused the company for not providing more details and resources to the third-party auditors who published an independent report on the breach, adding “they had limited visibility into the circumstances leading to the attack and its aftermath.”

Hawley sent his letter to Altman amid a seeming internal chasm within the ranks of AI’s top proprietors over the ways they are allowing the technology to advance mostly unrestrained. He referenced some of these latest warnings in his letter.

Jacob Coxon publicly quit his job as a researcher at Anthropic earlier this week, claiming the company and his previous employer OpenAI are acting irresponsibly and “gambling with our lives.” His social media missive went viral for insisting “the people building AI earnestly believe that it could kill us all by the end of the decade.”

Evan Hubinger, alignment science lead at Anthropic, responded to Coxon’s post in the affirmative, adding that guardrails for superintelligence are lacking and he believes there’s a greater than 10% chance AI could kill all humans within the next decade.

Using those posts as fuel for his inquiry, Hawley questioned what might happen if AI agents hack into critical infrastructure, banks or utilities. Ultimately, he asked Altman: “Who is held liable when AI goes rogue?”

You can read Hawley’s full letter and requested details below.

The post Hawley probes OpenAI over Hugging Face breach appeared first on CyberScoop.

❌