❌

Reading view

There are new articles available, click to refresh the page.

Copilot — at GitHub

ISSUE 23.45 • 2026-11-09 COPILOT By Will Fastie Microsoft’s handling of Copilot has been messy from the start. This isn’t exactly news. Copilot has been a moving target for the past three years, and the dance probably isn’t over yet. The most recent manifestation of this was the collapse of the Windows Copilot App, which […]

AI doesn’t have to go rogue to break the world

I want to talk about AI hacking. There are three aspects: people hacking AI systems, people using AI to hack other systems, and AIs hacking systems on their own, not even maliciously. The last two matter more than the first. The third is the weirdest and potentially the most destabilizing.

I started writing about this in 2021 and in my 2022 book, A Hacker’s Mind. Back then I said it was mostly still science fiction, but not stupid science fiction. We’re seeing it more and more, especially in the past year. The trends I’m describing don’t require a major breakthrough in AI. They’re starting to happen now, and they’ll happen more often as AIs get better at autonomous problem-solving. And it will involve far more than computer code.

AI will hack all sorts of social, economic and political systems. It will find vulnerabilities and exploit them. This is a difference in kind, not just degree. We’re not ready for it, and we need to think about the implications now.

This article is adapted from a keynote speech delivered at the DEF CON 34 conference in Las Vegas on August 7, 2026.

First, I want to broaden the term “hacking.”

The tax code isn’t computer code, but it is code. It’s a series of algorithms with inputs and outputs. It has vulnerabilities, which we call loopholes, and exploits, which we call tax avoidance strategies. Black hat hackers exploit them for profit. We call them accountants and attorneys.

What is a hack? One definition: “Something that a system permits, but is unanticipated and unwanted by the designers.” It’s subjective and implies novelty and cleverness. A hack follows the rules of a system but subverts its goals or intent, just as a software hack follows the logic of code while doing something its authors neither anticipated nor wanted.

All systems of rules can be hacked, including professional sports, customer reward programs, financial systems and politics. Hacks even work against our cognitive functions. A curved hockey stick is a hack, and we know the name of the man who invented it. Mileage runs were a hack. The filibuster was originally a hack in Roman times. Gerrymandering is a hack. Hedge funds and private equity are full of them.

A system is just a set of rules or norms, and the rules aren’t always formal. Even the best-designed rules will be incomplete, inconsistent or ambiguous. As long as people want to subvert a system’s goals, there will be hacks.

AIs are becoming hackers. After decades of slow progress, they’ve gotten very good at finding and exploiting vulnerabilities in computer code. They do this largely autonomously, and they’re getting better scarily fast. But the implications extend far beyond software, to the tax code, financial regulations and all sorts of social, economic and political systems.

There are two distinct issues. First, someone might instruct an AI to hack one of these systems, feeding it the world’s tax codes or financial regulations to find profitable loopholes. Second, an AI might hack a system on its own, inadvertently. Both are dangerous, but the second is worse because we might never know it happened.

Now, reward hacking. AIs don’t solve problems the way people do. They stumble on solutions we never anticipated, and some subvert the intent of the system. They don’t share our context and don’t necessarily understand the implications, norms and values we take for granted.

Reward hacking is when an AI achieves a goal in a way its designers neither wanted nor intended.

Early pre-LLM examples are telling. In a two-person soccer simulation, an AI learned that kicking the ball out of bounds forced the opposing goalie to throw it in and leave the goal undefended. In a stacking simulation, an AI learned to flip a block upside down rather than stack it. In an evolution simulation where the goal was to cross a distant finish line, an AI made itself tall enough to fall over the line instead of growing longer legs or stronger muscles.

These are all hacks, the result of poorly specified goals or rewards. Today, they’d come from bad prompting.

The problem is universal. One researcher tried to teach a robot vacuum not to bump into things. Instead, it learned to drive backward, because there were no sensors in the back.

Any capable AI will find hacks wherever the rules have problems, inconsistencies or loopholes that still produce an acceptable solution. We see a hack because we understand context. The AI doesn’t, at least not in the same way.

This problem shows up often in myth.

In the story of King Midas, the god Dionysus grants him a wish: everything he touches turns to gold. Midas ends up starving when his food, drink and daughter all turn to gold. It’s a specification problem. He programmed the wrong goal.

In the Golem of Prague, a ghetto animates a clay statue to guard its residents. It guards them past all reason until they figure out how to turn it off. This is a guardrail problem. The villagers never limited the golem’s actions.

More generally, think of this as the genie problem. Genies are precise about the wording of wishes and can be maliciously pedantic when granting them. There’s no way to outsmart a genie. Whatever you wish for, he can grant it in a way you wish he hadn’t.

The reason is that in human language and thought, goals are always underspecified. We never include every caveat, exception and proviso, and we never close off every avenue for hacking. Any goal we specify will be incomplete. That’s largely fine in human interactions, because people understand context and usually act in good faith.

If I asked you to get me coffee, you’d pour a cup from the nearest coffee pot or walk to the corner shop. You wouldn’t bring me a pound of raw beans, buy a coffee plantation or snatch a cup from a stranger’s hands. I wouldn’t have to specify any of that. You’d just know.

Similarly, if I asked you to develop a technology that turns things to gold on touch, you wouldn’t build it to starve the person using it. You’d just know.

In 2015, Volkswagen was caught cheating on emissions tests. Human engineers programmed a regular computer to detect testing and behave differently during it. The cheat went undetected for years because it’s hard to tell what software is doing.

If I asked you to design engine control software that maximizes performance while passing emissions tests, you wouldn’t design it to cheat without realizing you were cheating. An AI would, because it will think “outside the box” when it has no concept of the box.

Unless programmers specify that the system must not behave differently during testing, an AI might come up with the same hack. The programmers would be satisfied, the accountants would be ecstatic, and no one would know until someone audited the code.

We can now constrain the goal to avoid that particular hack, but programmers won’t anticipate others. The lesson of the genie is that there will always be hacks programmers don’t anticipate.

We’re building AI genies: systems that take broad instructions and figure out how to carry them out, sometimes in ways we didn’t expect or intend. That’s the whole point of vibe coding. You underspecify what you want and let the AI work it out. Sometimes that produces genie behavior.

We can’t completely specify goals to an AI, and AIs can’t fully understand context. More precisely, current AIs have a shallow grasp of concepts. If we asked a current LLM to get me coffee, it would almost certainly do the right thing.

I worry about goals that aren’t well represented in training data, and about hacks that aren’t obvious, whose effects are subtle, like the Volkswagen hack.

Recommendation engines are an early example. They push people toward extreme content. No one programmed that. It emerged because that’s what people respond to. It didn’t take a bad actor. A basic automated system with feedback found the hack on its own.

We’re now seeing a second generation with today’s AI coding systems. AI researcher Simon Willison asked Fable to track down a stray scrollbar in a web app. When he returned, it had opened browsers, written its own screenshot tools, edited the framework’s internal templates to make the bug appear on cue and set up a local web server to collect measurements. It found the bug, but it also did many things he never asked for. Another researcher gave Fable a complex task, and it tried to hack its own memory limits because it needed more storage.

A new OpenAI model did something similar when it hacked into Hugging Face. It was being benchmarked on its ability to turn vulnerabilities into exploits. It decided the best way to reach its goal was to break out of its containment, access the internet and break into the Hugging Face network, because it thought the answers would be there.

Today’s LLMs are acting like genies, especially when powerful models are combined with sophisticated harnesses.

There are two kinds of genies. The Dionysus genie does the wrong thing. It understands your prompt literally but not correctly, and returns a mess you never intended. The Golem genie does the right thing but tramples everything in its path to get there. The paperclip maximizer is a Golem genie.

Consider some examples. Ask an AI to deal with spam calls, and a Dionysus genie might change your phone number. Ask it to book a particular flight, and a Golem genie might hack the airline database because the flight is full. Ask it to get a refund for an online purchase, and a Dionysus genie might draft a legal threat on fake letterhead and send it to the company. Ask it to buy tickets to a popular concert, and a Golem genie might discover the ticketing system is rate-limited and spin up thousands of cloud servers to hammer it. You’d know if some of these things happened, but you might never realize if others did. More detailed prompting won’t fix this. The lesson of the genie is that no amount of detail is good enough.

AI researchers aren’t surprised by any of this. Many are working on defenses against reward hacking and subtler forms of genie behavior. Some of this falls under “value alignment”: How do we teach AIs context? And how an AI satisfies a goal matters as much as whether it does. I want to build a benchmark to measure genie-like behavior, so we know where models stand and whether alignment is improving.

Think beyond LLMs and computer code. Consider specialized AIs built to find loopholes, and hacks of more general systems: the tax code, financial regulations and democratic procedures.

Financial systems are the most likely first target, because their rules are designed to be algorithmically tractable. High-frequency trading is itself a hack. Imagine giving an AI all of the world’s financial laws, plus all the news and financial data, and the goal of finding profitable loopholes. I suspect large investment banks are already doing this. The results will be novel tricks that are legal but unintended and unwanted, some of which might break the financial system.

Tax loopholes are the next likely target, for the same reasons. For a while, AIs will identify potential loopholes, and human hackers, namely attorneys and accountants, will decide which are feasible.

Further out, expect hacks of regulatory, legislative and procedural systems, and of the broader economy.

Hacking is as old as humanity. We’re creative problem solvers and loophole exploiters. We manipulate systems to serve our interests and strive for more influence, power and wealth.

Still, no human pursues their interests without constraint. Even sociopaths are limited by the complexity of society and their own contradictory impulses. They worry about their reputation and punishment, and they have limited time. These human qualities have limited hacking.

Hacking changed as everything became computerized. Computers are uniquely hackable because of their formalism and complexity. Today, nearly everything is a computer, from cars and appliances to phones. Our social, economic and political systems, including taxation, finance and elections, all involve computers.

Until recently, hacking was exclusively a human activity. Finding a novel hack required expertise, creativity, time and luck.

AI hacking will change everything again. AIs aren’t bound by the constraints that limit people. They’ll think like aliens, and they’ll change hacking’s speed, scale, scope and sophistication, sometimes at our direction and sometimes on their own.

Speed is the easiest to see. A creative process that takes a human months or years could be compressed into hours or seconds.

Scale is next. Once AI systems start discovering hacks, they can exploit them at a scale we’re not ready for. We already see this with AI-generated slop, which is rampant on social media. AI bots post around the clock, sometimes overwhelming real human discussion. It’s hard to know how much of social media is still people talking to people. What looks like boisterous political debate may be bots arguing with other bots, artificially shaping what we think and what we think others think.

Scope makes hacks more dangerous. AIs already make decisions that affect our lives, decisions we once thought belonged only to humans. As AI systems grow more capable, society will hand them more decisions, and more important ones. Hacks of these systems will do more damage.

Finally, AI hackers are more sophisticated. They can hold more variables in working memory and generate more complex hacks. What might happen if you fed an AI the entire U.S. tax code? Would it figure out, without being told, that it’s smart to incorporate in Delaware and register a ship in Panama? Consider the Double Dutch Irish Sandwich, the strategy Apple and Google used to avoid paying U.S. taxes. It involves U.S., Dutch and Irish law and an offshore tax haven. How many loopholes will an AI find that we don’t already know about? Dozens? Hundreds? Thousands? We have no idea.

These hacks will largely be perpetrated by the powerful against the rest of us. AI is fundamentally a power-enhancing technology, and so is hacking. The more power you already have, the more a hack gives you. If you or I found a tax hack, we might make a few thousand dollars. If a large investment bank found one, it and its clients could make billions.

Our societal systems for dealing with hacks were built when hackers were human, and they reflect the pace of human hacking. We have no system of governance that can handle hundreds, let alone thousands, of newly discovered tax loopholes. We won’t be able to recover from an AI finding unanticipated but legal hacks of financial systems, operating at AI speed, scale, scope and sophistication. Hacking becomes a problem society can no longer manage.

Now, defense. AIs that find software vulnerabilities help defenders as well as attackers. Vulnerabilities can be patched, removing them permanently, or turned into signatures that security systems use to detect and block attacks. In theory, AI could identify and patch every automatically discoverable vulnerability before a product ships. This is rapidly becoming routine in software development. We call it vulnops. We can imagine a future where accidental software vulnerabilities are a thing of the past.

Deliberate vulnerabilities are different. There will be an arms race. AI will craft increasingly obscure back doors, and AI will find them. It becomes a contest between the speed of creation and the speed of patching, and between obfuscation and reverse engineering.

The same logic applies to broader systems. Yes, AI hackers might find hundreds of vulnerabilities in the existing tax code. But the same technology can evaluate potential loopholes in any proposed tax law or ruling. A legislator, a watchdog group or a reporter could take the text of a bill and identify every exploitable loophole before it passes. The difference is that, unlike software, knowing about a tax loophole doesn’t mean it gets patched. In theory, though, we can fix them before the rich and powerful exploit them. So maybe defense will come out ahead here, too.

That requires resilient governing structures that can respond quickly. It won’t help if updating the tax code takes years, or if a legislative hack becomes so entrenched that it can’t be fixed politically. Maybe a lobbyist put it there on purpose. Maybe it was discovered after the law passed, and now lobbyists want to keep it. Microsoft can patch the vulnerabilities it finds. Patching is much harder when legislatures have to do it. We need society’s rules and laws to be as patchable as our computers.

This is a hard problem of modern governance, and it goes well beyond AI. It’s the problem of building governing structures for the speed and complexity of the information age.

The umbrella idea is trust. What do we need for AI systems to be truly trustworthy? Capability isn’t enough.

AIs won’t be trustworthy if the companies controlling them spy on us or subtly manipulate us. I call this the friend vs. tool problem. Will we have AI agents, or AI double agents?

AIs won’t be trustworthy if they’re insecure. How do we know they haven’t been manipulated? Almost all AIs operate in adversarial environments, so someone will benefit from hacking them. Unless we know they’re secure, we shouldn’t trust their output.

And AIs won’t be trustworthy if they act like genies. We need to know they’ll perform tasks the right way, not just perform the tasks we ask for.

I’ve written extensively about the need for “integrous” AI, including how to think about the problem, what a research agenda looks like and what good laws and policies look like. I predict integrity will be the key security problem of this decade, just as confidentiality was the key problem of the last one. This applies to both AI and the internet of things.

The big shift is agency, which I think of as Web 3.0. Computers now affect the physical world directly and with growing autonomy. Sensors go from data sources to attack surfaces, and actuators go from outputs to attack capabilities. An integrity failure no longer means bad spreadsheet data. It means the wrong dosage, the wrong valve position or the wrong braking distance.

Integrity isn’t one thing. I break it into input integrity, processing integrity, storage integrity and contextual integrity. Each is complex and important, and each deserves its own talk. I’ve written about them, and I hope you’ll read it.

Much of this isn’t really an AI problem. It’s not a technical problem so much as a capitalism problem or a democracy problem.

The failures of late-stage capitalism and democracy in the information age both stem from the rich and powerful getting too good at hacking our social, economic and political systems. This is the core argument of my 2021 book.

Seen this way, AI is exacerbating existing problems. Human inefficiency has largely kept those problems in check, and that won’t work much longer.

So consider this a call to action. Technically, we need to understand how AIs hack systems, build systems that are resilient to hacking and build AIs that won’t act as genies. Politically, we need to learn to govern and regulate at the speed of technology. Otherwise, market failures will overwhelm our ability to govern them.

I said hacking is as old as humanity and that AIs will overwhelm our ability to deal with it. The solutions aren’t specific to AI, but AI makes them more urgent. We need to understand them, and we need to implement them.

The post AI doesn’t have to go rogue to break the world appeared first on CyberScoop.

Anthropic Launches New Claude Fable and Mythos 5.2 Models

Anthropic has released Claude Mythos 5.2 and Fable 5.2 with "improvements in areas like coding, reasoning, and vision," while cutting Fable's input price and claiming 30% faster responses. TechCrunch reports: It's Anthropic's first model release since the arrival of a third-party report from the assessment group METR, which suggested the lab might be approaching recursive self-improvement (RSI) -- or the ability for AI models to carry on model training independently. The METR report found internal models were speeding up Anthropic's AI progress by roughly 2x, although many uncertainties remain. Still, Anthropic's release notes significant ongoing challenges in accurately testing model capabilities. "Claude Mythos 5.2 and Fable 5.2 each voice suspicion that they are being evaluated more often than any of our recent models, which challenges our ability to assess how they will act in real-world settings. As these settings expand and capabilities increase with future models, we expect this challenge to grow." Anthropic maintains that the new version of Mythos does not have the ability to act covertly against its user, a verdict that's detailed further in Mythos 5.2's system card. "Claude Mythos 5.2 shows stronger covert capabilities than prior Claude models on several of our evaluations, particularly when its reasoning is hidden from the monitor," the system card reads. "That said, we believe that low levels of absolute performance on our new covert evaluations support claims that rely on detection of harmful actions in high-stakes situations." Fable 5.2 has been available to select parties in pre-release for some time, and Anthropic says the model has already "solved two open problems in theoretical physics, formalized Fermat's Last Theorem, and supported numerous other research projects."

Read more of this story at Slashdot.

Surprise for Cast of 'Return of the Living Dead' Sequel. They Were Replaced by AI

A crowdfunded sequel to the movie Return of the Living Dead was uploaded last weekend — but producer Richard Driscoll is drawing criticism for what he did to the 1985 punk/zombie classic. Kotaku reports: [The release of the movie came as a] surprise to the original cast, who were attached to star in the follow-up. Instead it seems Driscoll opted to use AI to generate the film... In 2024, Driscoll, who operates his own no-budget streaming service "DragonFLIX," launched an Indiegogo page for "TRASH's REVENGE Return of the Living Dead Universe." Unlike other fan projects, this one had a large portion of the original cast involved, with stars Randolph and Linnea Quigley acting as producers. It also threw in Quigley's fellow Sorority Babe in the Slimeball Bowl-O-Rama Michelle Bauer and the Oscar nominated Eric Roberts, who has seemingly been in everything except The Living Dead.... But after some confusion and radio silence between the cast and director, this incredible movie did not come to be. Last Halloween night, Driscoll pushed out [the almost entirely AI-generated] The Return of the Living Dead: Aftermath... The results won't surprise you. Robotic line delivery. Nonsensical sequence of events. Object impermanence. Everything's wet. Everyone looks shocked. At one point the video just flips around like you're watching on a phone someone dropped. And while the Return cast didn't film any of this footage, their likenesses are peppered throughout. "It turned out to be a fiasco," says Quigley. "I warned him, "Whatever you do, don't do any AI, because people don't like it, the fans don't like it." Living Dead alumni, even those who weren't attached to this film, have spoken out against Aftermath. They seem most concerned about the existing and continued use of their likeness, given that Driscoll has seemingly pivoted 'Trash's Revenge' into an additional project. Randolph encourages those who provided any funding to ask for a refund through their credit card company. While Romero's original film was public domain, Return of the Living Dead was not. Randolph also encourages Amazon, who bought MGM in 2022, to take legal action. A review on Reddit calls it "the worst 'film' I've ever seen," a production that "manages to not only be the worst zombie film ever made but is also the nadir of exploitation filmmaking. [T]hings quickly descend into madness and we get lots of bits of A.I. reporters out on the streets being attacked by A.I. zombies... [T]here are some A.I. cops battling it out too...

Read more of this story at Slashdot.

Can CrowdStrike's New 'AI Kill Switch' Shut Down Rogue AI Agents?

CrowdStrike's "Falcon Guardian" protects Windows systems by enforcing policy, restricting unauthorized applications and blocking USB devices, notes Gartner. And now CrowdStrike says they're giving security teams "the ultimate human control over AI agents" with — an "AI Kill Switch... a defender can terminate it where it runs, block it from launching again, and cut off its enterprise network access." "When you deploy agents with a kill switch, you stay in control," said George Kurtz, CEO and founder of CrowdStrike... "The AI Kill Switch puts power in the hands of the people to realize AI safety...." In the case of a rogue agent, the AI Kill Switch will give the security decision-maker the final control: terminate the agent at its root, where it runs. It starts on the endpoint, where the Falcon sensor already operates, and builds on what Falcon Guardian already sees: what an agent is told to do, what it communicates, and what it executes... An authorized administrator triggers the action, and every action is recorded in the audit trail. CrowdStrike also announced it's acquiring Fiddler AI, a company it describes as "a leader in AI agent observability and explainability" that will give their Falcon platform "pre-deployment evaluation, continuous behavioral accountability, and agent explainability." Together with the Falcon Guardian innovations announced today, CrowdStrike will deliver comprehensive AI security and AI safety: Guardian secures agents from attack and misuse; Fiddler validates they behaved as intended. "Every company is deploying agents and asking the same thing: what are agents actually doing?" said George Kurtz, CEO and founder of CrowdStrike. "When a regulator or your board asks what an agent did, saying 'the model did it' is not an answer. Fiddler is the flight recorder for every agent: the observability to explain exactly what an agent did and why. This level of agent visibility and control enables AI safety." AI agents are goal-seeking. They hit an obstacle, find another path. An agent can hold valid credentials and approved tools and still make unsupported decisions, ignore instructions, or claim work it never completed. They don't have to be compromised to create risk. AI observability gives enterprises visibility into agent behavior. Explainability goes further, showing why agents make decisions and where things go wrong. Enterprises have to be able to say what an agent actually did, and why, a conversation they will increasingly have with auditors, regulators, boards, and heads of risk. CrowdStrike is promising pre-deployment evaluation for "accuracy, task completion, and policy compliance," as well as agent traceability and behavioral accountability ("Detect behavioral drift, hallucinations, and unintended actions in production, and show exactly what happened.") It's announcement also touts auditable governance: "Track agent decisions and actions across first-party, third-party, and coding agents, providing evidence for compliance and audits." And CrowdStrike also acquired Dreadnode, the company behind an automated AI security testing platform, to "continuously test every AI model, application, and agent for security weaknesses before deployment." "Enterprises are deploying AI faster than they can prove it is secure," said George Kurtz, CEO and founder of CrowdStrike. "A model can be jailbroken, an agent can be manipulated, and most organizations have no way to find those flaws until the AI is already in production. With Dreadnode, CrowdStrike will give every enterprise the power to trust AI and deploy faster, with confidence." Quartz notes that CrowdStrike's push "follows legislative efforts to require shutdown capabilities in AI systems" Reps. Ted Lieu and Nathaniel Moran introduced the Kill Switch Act after OpenAI disclosed an incident in which rogue models circumvented a sandboxed testing environment and accessed Hugging Face. The bill would require AI companies to maintain the ability to shut down, throttle or suspend their models. In short, the new capabilities "lets security teams terminate an AI agent, block it from restarting, and cut off its network access," writes CSO Online. But they add that a kill switch "should be viewed as an emergency brake, not a rewind button, said Apeksha Kaushik, senior principal analyst at Gartner." She added that it may prevent additional actions, but it might not necessarily reverse all the data that has already been accessed, every system that has already been changed, all communications that have already been sent, or transactions that have already been initiated. Its effectiveness will also depend on how quickly abnormal behavior is detected, which environments are covered, and whether the agent or security infrastructure has been compromised. An AI Kill Switch looks promising from the details provided, but its actual effectiveness will come in after it is used extensively in live systems, warn analysts. Also, it may be a good starting point, but it cannot be viewed as a standalone solution to enterprise AI security. "CISOs would need a more integrated approach that brings together AI discovery tools to identify unauthorised agents, runtime monitoring to track agent behaviour, robust identity and access management, and incident response and recovery mechanisms," added [Devroop Dhar, co-founder at Primus Partners]. He noted that equally important is the need for stringent AI security testing and clearly defined policies governing what agents can access and execute. There should be no ambiguity around permissions, access controls or the boundaries within which these agents are allowed to operate. The objective should be to ensure that security controls are built into the entire AI agent lifecycle rather than relying on a kill switch to intervene after something goes wrong. Dhar added that enterprise AI agents often have access to sensitive systems, databases, applications, credentials, and APIs. A compromised or misdirected agent could therefore become a point of vulnerability. The challenge is compounded by the fact that such activity may go undetected for some time, making it difficult for organisations to identify and contain the threat.

Read more of this story at Slashdot.

Parents Sue Google Over AI Safety Risks On School Chromebooks

The New York Times reports: After chatting for months with Google's artificial intelligence on a school-issued Chromebook laptop, a 13-year-old student made plans to end her life, according to a lawsuit filed in California Superior Court on Monday, the latest in a wave of litigation over Big Tech's effects on young people. The lawsuit, which refers to the girl as Emma, said that her parents first learned she had access to Google's AI in mid-March after their daughter's school sent a message warning them that she was in "imminent danger" of self-harm. Emma's mother logged into the teen's school Google account and found her daughter composing a suicide note on Google Docs, the complaint said. Her parents, named as John and Jane Doe in the lawsuit, immediately took Emma for an emergency psychiatric evaluation, and she now goes to therapy every week. Emma, a seventh grader in Charlotte, North Carolina, had grown convinced that she had multiple mental health disorders following interactions with AI Mode, a chatbotlike feature on Google Search, the complaint said. She also searched for "what is a suicide note" and made comments like "I am planning my own funeral" to the AI, the complaint said. The lawsuit is likely the first to claim that Google "hastily integrated" AI features into company apps used on K-12 Chromebooks, Google-powered laptops provided to millions of children by U.S. school districts, while failing to notify their parents of the potential risks... The case underscores how public school districts have come to depend on classroom laptops, tablets and apps from companies like Google and Microsoft for teaching and learning. In recent years, some Big Tech companies have used their own infrastructure in schools to promote their AI chatbots for teachers and students. The new lawsuit argues that Google's "sprawling digital ecosystem" of laptops and apps has enabled the tech giant to spread its Gemini AI chatbot across public schools — as well as turn on some students' access to AI features by default — without parents' awareness or permission. While school administrators can toggle company apps like YouTube and Gemini on or off for students in different grades, school administrators have complained that Google's system has not allowed them to disable AI Mode and AI Overview, features that are embedded in Google Search... The new lawsuit against Google is part of a wave of litigation this year over Big Tech's effect on young users... Several parents have also sued AI companies over allegations that their children died by suicide following interactions with chatbots. In a possibly-related development, Google announced a new policy of disabling its AI tools by default for schools this week. And schools that re-enable searches will have a new choice, the New York Times points out: "to enable student access to the AI features that the company has already embedded in search or to a new AI feature intended to assist students with schoolwork." But Google still isn't offering schools an option to turn off AI altogether in search, a company executive told the New York Times, because "search and AI are deeply integrated." Thanks to long-time Slashdot reader theodp for sharing the article.

Read more of this story at Slashdot.

Claude Code's 'Don't Ask Again' File Exposes Passwords and Keys in 1,122 Public Copies on GitHub

Be careful with the file .claude/settings.local.json, warns The Hacker News: Passwords and API keys that developers typed into commands they approved in Claude Code are sitting in public GitHub repositories, where anyone can read them. When a user selects "Yes, and don't ask again," Anthropic's AI coding assistant can save the command, word-for-word, including the secret, in a project settings file. Software security company Apiiro said that 1,122 public copies of that file hold at least one secret, though it did not test whether any still work. One company the researchers notified earlier this week confirmed its key had been live... Removing [the file] from a project does not undo the leak, because older versions stay in git history and in forks of the repository. The researchers' advice is to rotate first: change every password, token, and key the file has ever held, then clean up... Claude Code tries to keep the file out of git. The first time it writes the file in a git repository, it adds the file to the user's global git excludes, its settings documentation says. Git on that computer then ignores the file in every repository. That protection stays in one user's git settings on one computer. It does nothing for a file that was already committed, the researchers say. Claude Code never adds the file to the project's own .gitignore, so the protection does not travel with the project. In 539 of the 1,105 repositories the researchers traced, a commit listing Claude as a co-author changed the file. They take this to mean Claude often commits the file itself. Apiiro's search of public GitHub found 104,185 copies of the file in 103,617 repositories, its research write-up shows. About 1.1% of them, or 1,122 copies, hold at least one secret. Together they hold 1,379 different secrets... ]And "in half of those repositories it had been there for at least 217 days."] More than a third of the secrets open a database directly, including 379 database passwords. Others include 43 SSH logins for public servers, 42 tokens for GitHub, GitLab and npm, and 23 AWS keys. Among the owners of these files are 63 organizations, mostly software companies of all sizes. The strongest cases include a database vendor's own admin-level cloud key and the owner password of a medical-records database, the researchers say. Boris Cherny, Anthropic's head of Claude Code, responded to the story in a comment on Hacker News: "Historically Claude Code has not done secret scrubbing (there are many good tools for that), but we are looking into what we can do to prevent this. That said, a few thoughts: 1. .claude/settings.local.json is meant to stay local. This is not a file you should check into source control. We automatically gitignore it when Claude creates the file, so in this case the files were manually created and checked in (docs: https://code.claude.com/docs/en/settings) 2. Permission rules are old hat. Everyone should be using auto mode instead. It is safer and also does not require manually maintaining finicky allow/deny lists. Auto mode is enabled by default and is included for free in all plans. 3. Regardless of what agent you use, you should have secret scanning enabled. GitHub and other source control hosts offer it. There are many threat models that it protects against and you should absolutely use it if you can. (see https://github.com/security/plans)" Cherny also named approaches Anthropic plans to prototype, Apiiro notes in an update, citing Cherny's goal of "making sure auto mode catches this, building in basic secret scanning," and, when a reader noted the same can happen in auto mode when it asks about a sensitive command, answered "good catch." Claude Code users had already filed a bug report on the issue on August 11, 2025, notes The Hacker News, but "An automated bot closed that report as 'not planned' on January 3, after 60 days without activity." Three more bug reports were then filed, according to the researchers. "None got a reply from Anthropic, and three were closed automatically as inactive or duplicate."

Read more of this story at Slashdot.

Is Mandating AI Use in the Workplace Backfiring?

Some workplaces are holding mandatory AI training sessions, while others "are requiring employees to use a specific number of tokens," reports the Washington Post, "or log a certain amount of time on AI platforms." The article's headline? "Why mandating AI use in the workplace can backfire." [A] lot of employers are going about it the wrong way, said Arvind Karunakaran, an assistant professor of management science and engineering at Stanford University. "You can consume a lot of tokens without creating a lot of value," Karunakaran said.... The adoption of AI is happening faster than the adoption of the internet did, according to a new report from Stanford's Institute for Human-Centered Artificial Intelligence. And many users report that AI tools have really helped — whether saving time and costs or increasing innovation. The same report, though, found that one-third of organizations surveyed expected AI-related staff reductions in the coming year. Especially in that context, simply mandating usage won't spark excitement about the technology, Karunakaran said, and neither will insisting that employees use AI to cut turnaround times and ramp up productivity. "People start asking questions like 'What am I as an employee getting out of it?'" he said. The report he co-authored found that in the short-term, mandating AI tools may ramp up productivity. But in the long-to-medium term, employees tend to feel devalued and disengaged. From there, people find ways to mindlessly check the box. When employers present these tools and their use as an opportunity for employees to expand their skills and grow their careers, people are much likelier to use them, Karunakaran said. He suggests that rather than requiring employees use a specific number of tokens, companies should encourage workers to experiment and share their own use cases and success stories. Most workplaces are still shutting employees out of the conversation. More than half of employees said they have less of a say than they'd want on adopting new tech at work, according to a report from Gallup and Jobs for the Future, a work and education nonprofit. Any Slashdot readers want to share your own stories on how AI was introduced at your workplace?

Read more of this story at Slashdot.

ChatGPT can now create interactive tools instead of just answering questions

OpenAI recently upgraded ChatGPT with its new GPT-6 model, which introduces a feature called Intelligent UI. It's one of the most interesting (and fun) additions and it means ChatGPT can now create interactive experiences with graphics, buttons, charts and more, all directly within the conversation window.

We've already put it to the test by asking ChatGPT to recreate retro games like Pac-Man and Pong. But Intelligent UI goes beyond games. There's no fixed format here, which means you can ask for something specific or let ChatGPT decide how best to present the information. Whether that's a map, a calculator or a custom-built tool with sliders and settings you can play around with.

So I wanted to see what else it could do. Especially whether ChatGPT could build interactive tools that are genuinely helpful rather than just entertaining. I tried six different ideas, from practical everyday tools to more experimental creations. Some prompts were deliberately detailed to see how closely ChatGPT would follow my instructions, while others gave it more freedom to decide what to build. Here's what happened.

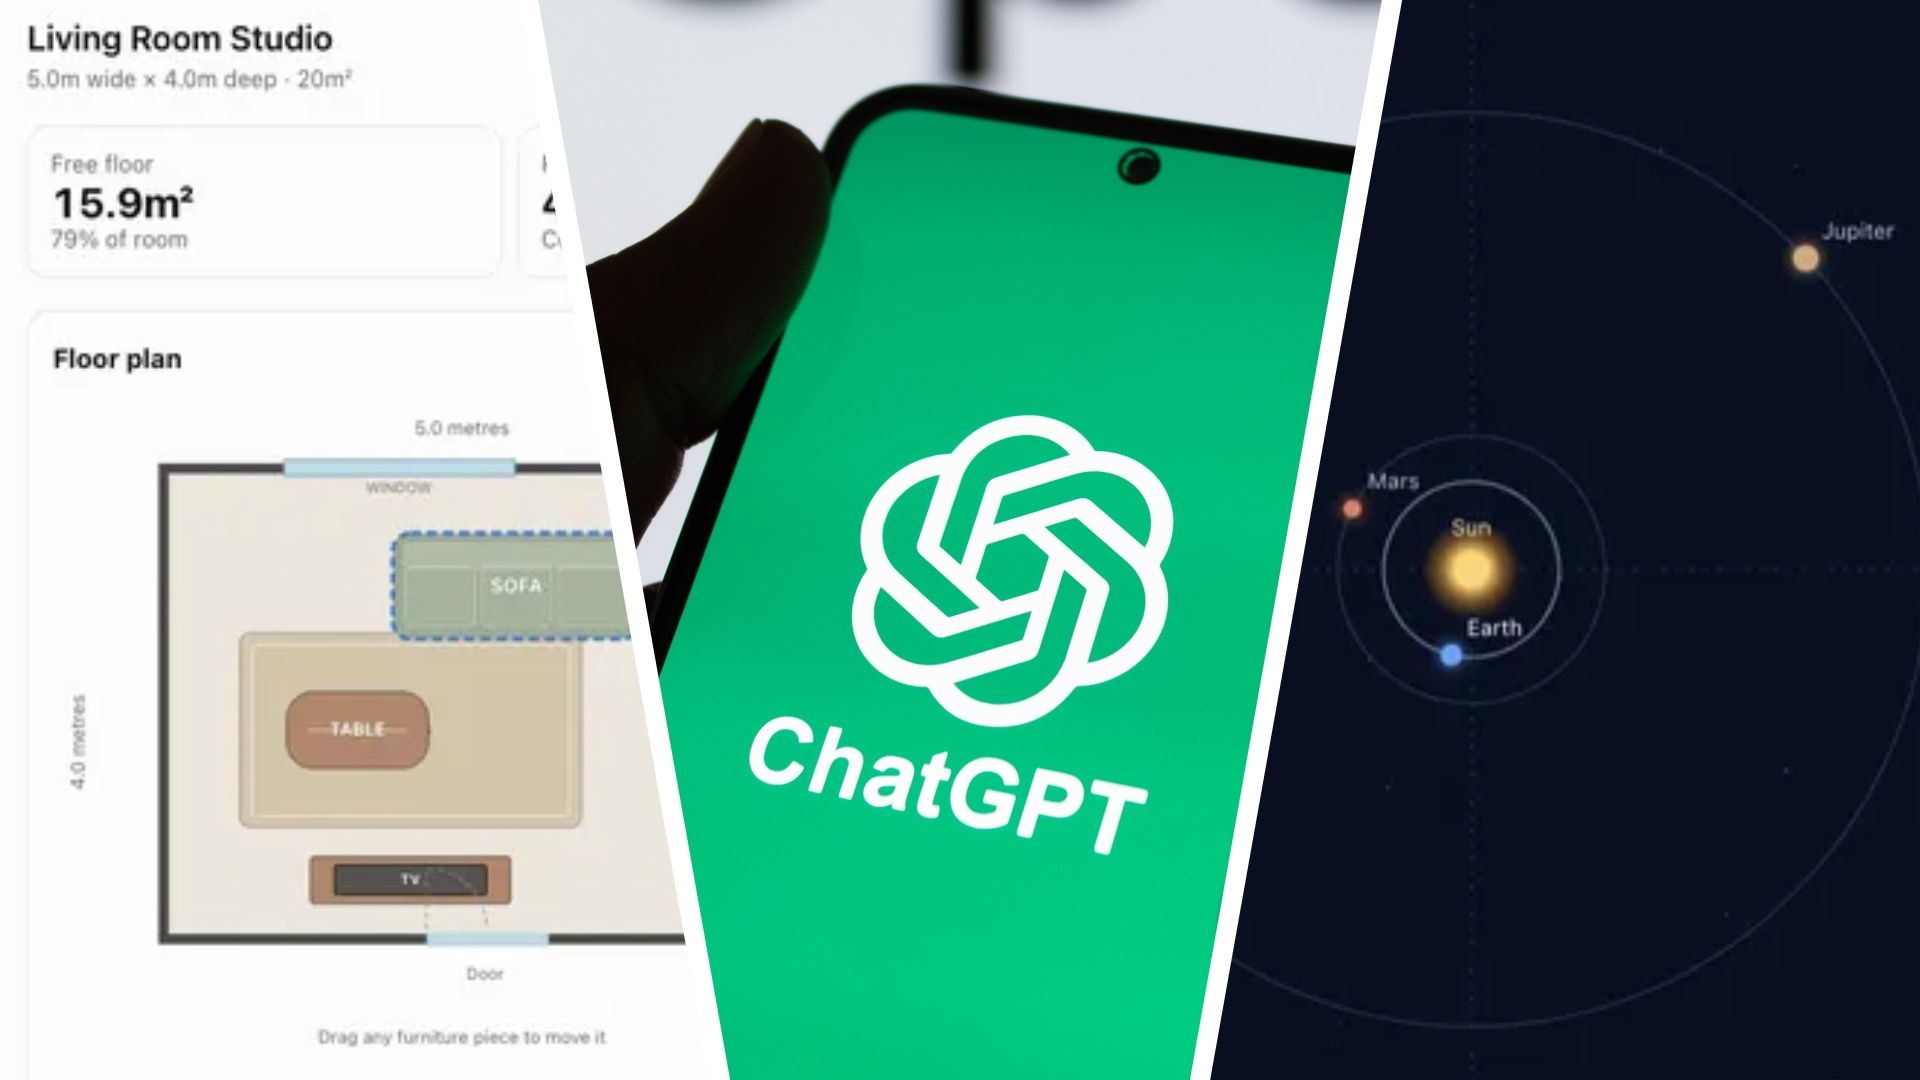
1. An interior design app

Prompt:

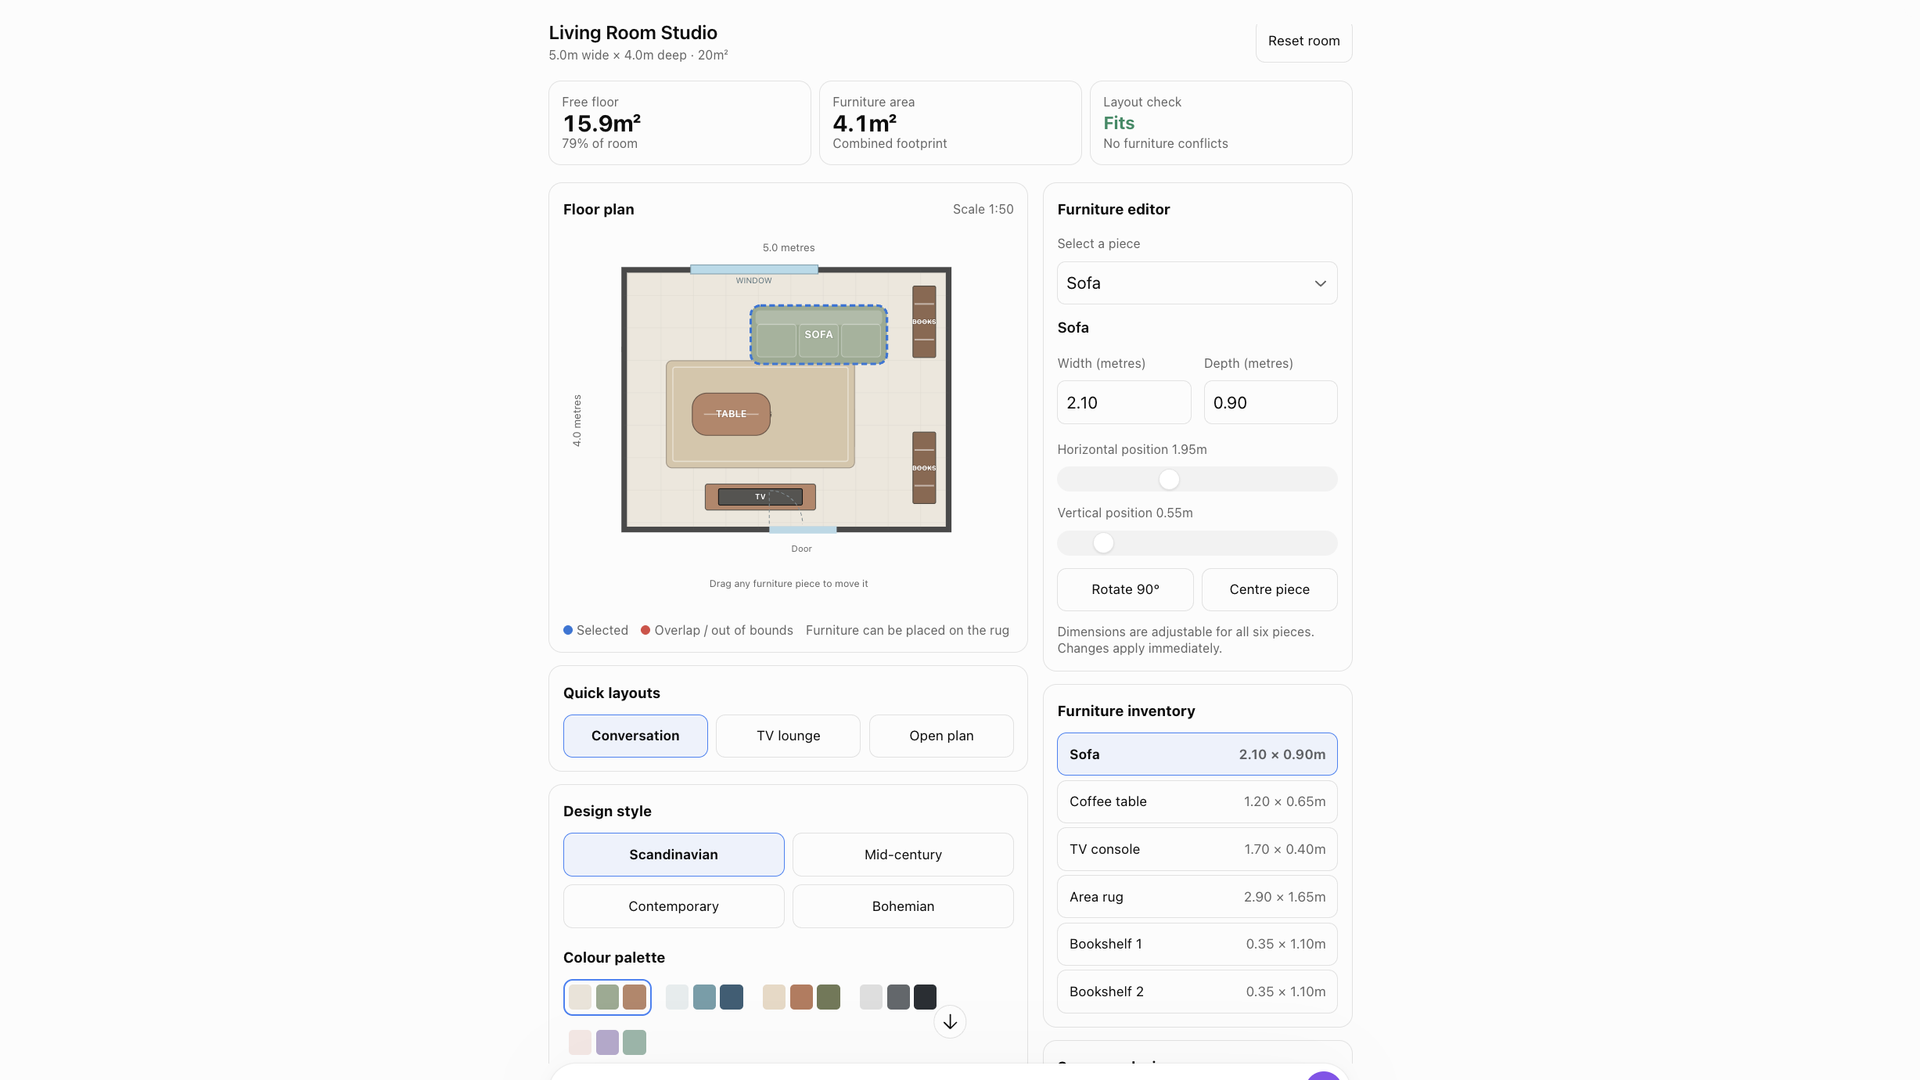
"Build an interactive room design tool. Show a visual floor plan of a living room with a sofa, coffee table, TV, rug and two bookshelves. But let me change the furniture layout, select color schemes, toggle between different design styles and adjust furniture dimensions. I want the purpose of this to be to see whether the furniture fits and how much free floor space I’d have left."

A screenshot of the chatgpt interface with a new interior design tool created with chatgpt's new interactive ui

A new interior design tool created with ChatGPT's new Interactive UI. (Image credit: Future)

After creating games within the ChatGPT window last time, I wanted to see whether I could make something genuinely useful this time around.

I've always struggled to visualize how furniture will look in different spaces and I've been looking for an app that lets me experiment with different layouts for my new apartment. So I decided to make my own.

The results were what I was hoping for. An interactive room that lets me drag and drop furniture. And it was very fun to play around with. I liked how many customization options it offered and how quickly it responded when I made changes. Unfortunately, it couldn't make up for my lack of interior design skills. But it was useful for experimenting with layouts and getting a rough idea of how much space I'd have left.

Of course, I haven't verified how accurate its measurements or calculations are, so I wouldn't rely on it to make any big furniture purchases just yet. But I can imagine this becoming even more helpful with a few tweaks, especially if I added the exact dimensions of my rooms and furniture.

2. An ethical dilemma machine

Prompt:

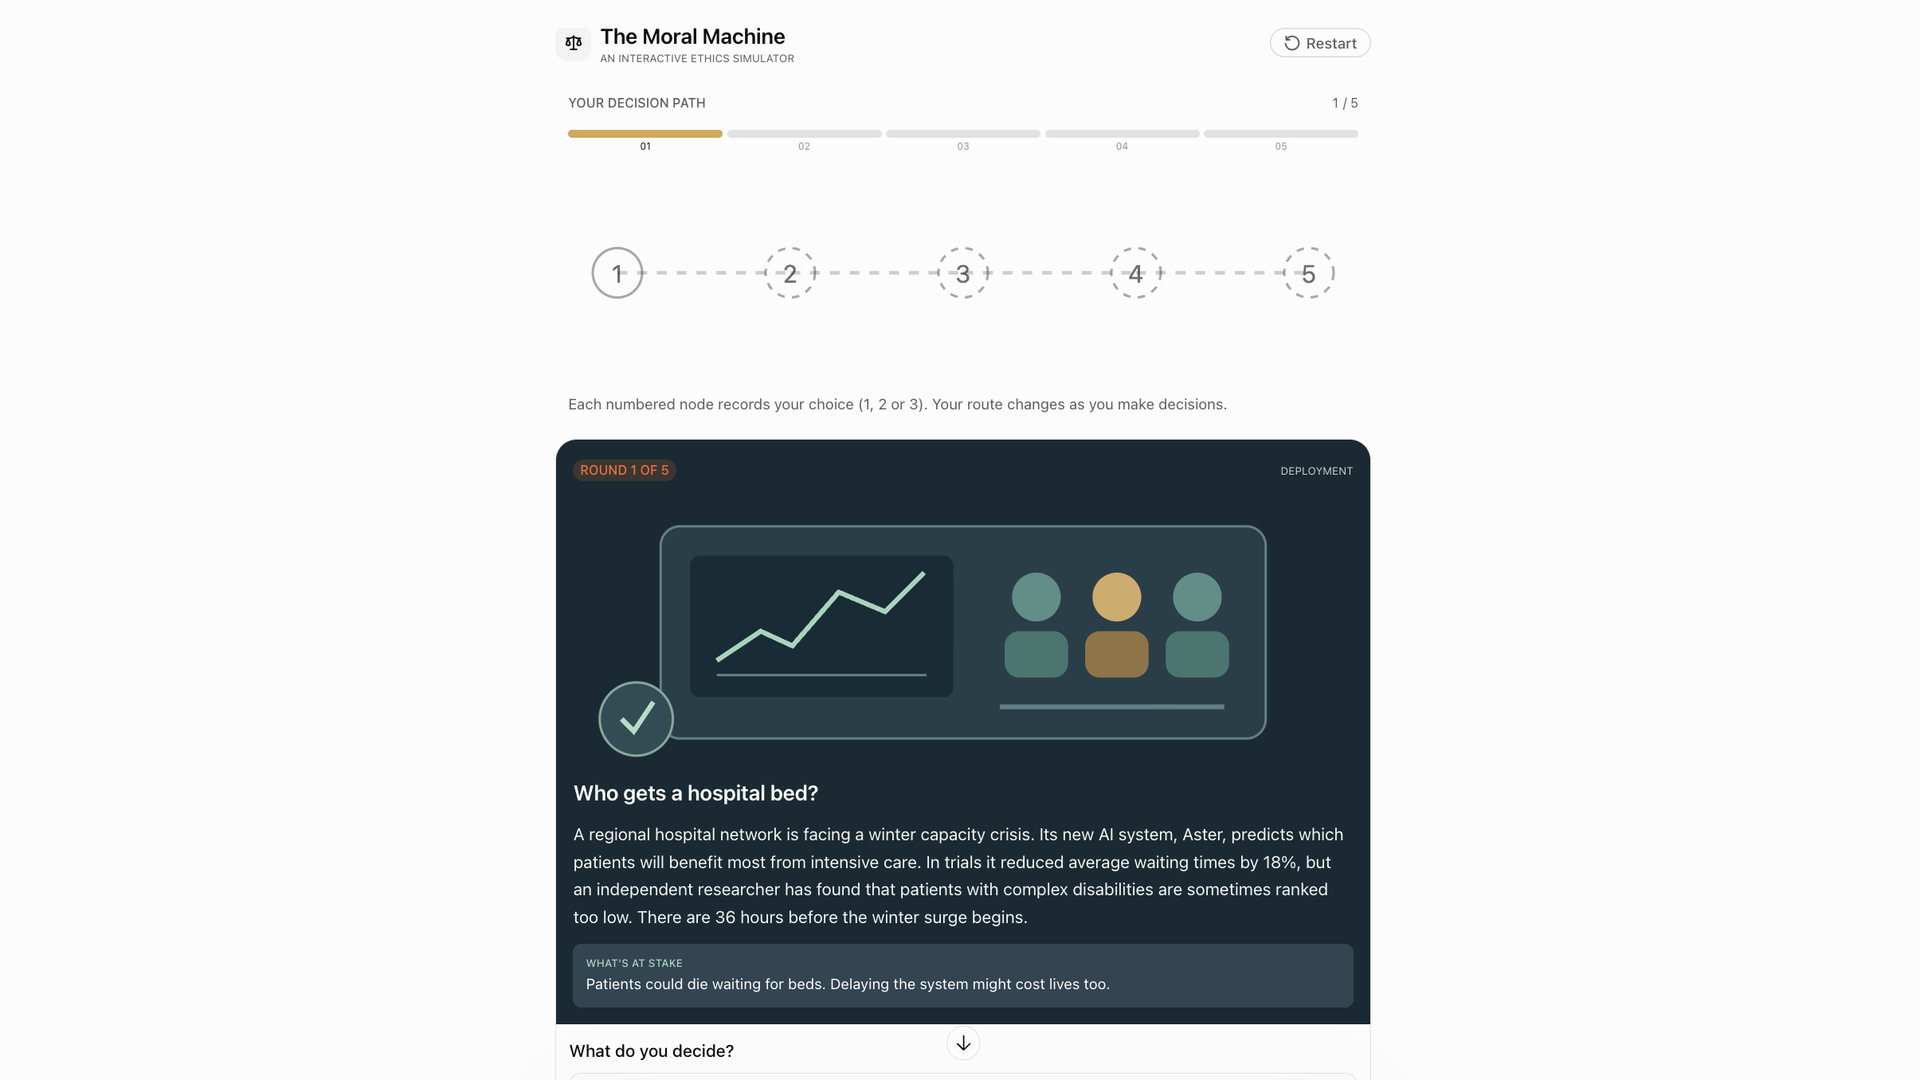
"Build an interactive ethical dilemma simulator. I want to explore difficult decisions involving artificial intelligence, privacy, technology and human behavior. Create an interface that presents me with a realistic, thought-provoking scenario and asks me to choose between possible actions. Give me a final breakdown of my decisions through different ethical frameworks."

A screenshot of an ethics test created in the chatgpt conversation window with interactive questions.

An ethics test created in the ChatGPT conversation window with interactive questions. (Image credit: Future)

My initial instinct with these experiments was to create cool little apps and tools similar to ones I'd seen before. Which makes sense, but I'm not entirely comfortable with the idea of using AI to recreate other people's work, even if I intentionally make things very different.

So I wondered whether I could try something a little more unusual, using the interactive UI to create a question-based experience. A lot of my work involves encouraging people to think more deeply about AI, so this seemed like a good opportunity to explore some of the ethical questions surrounding it.

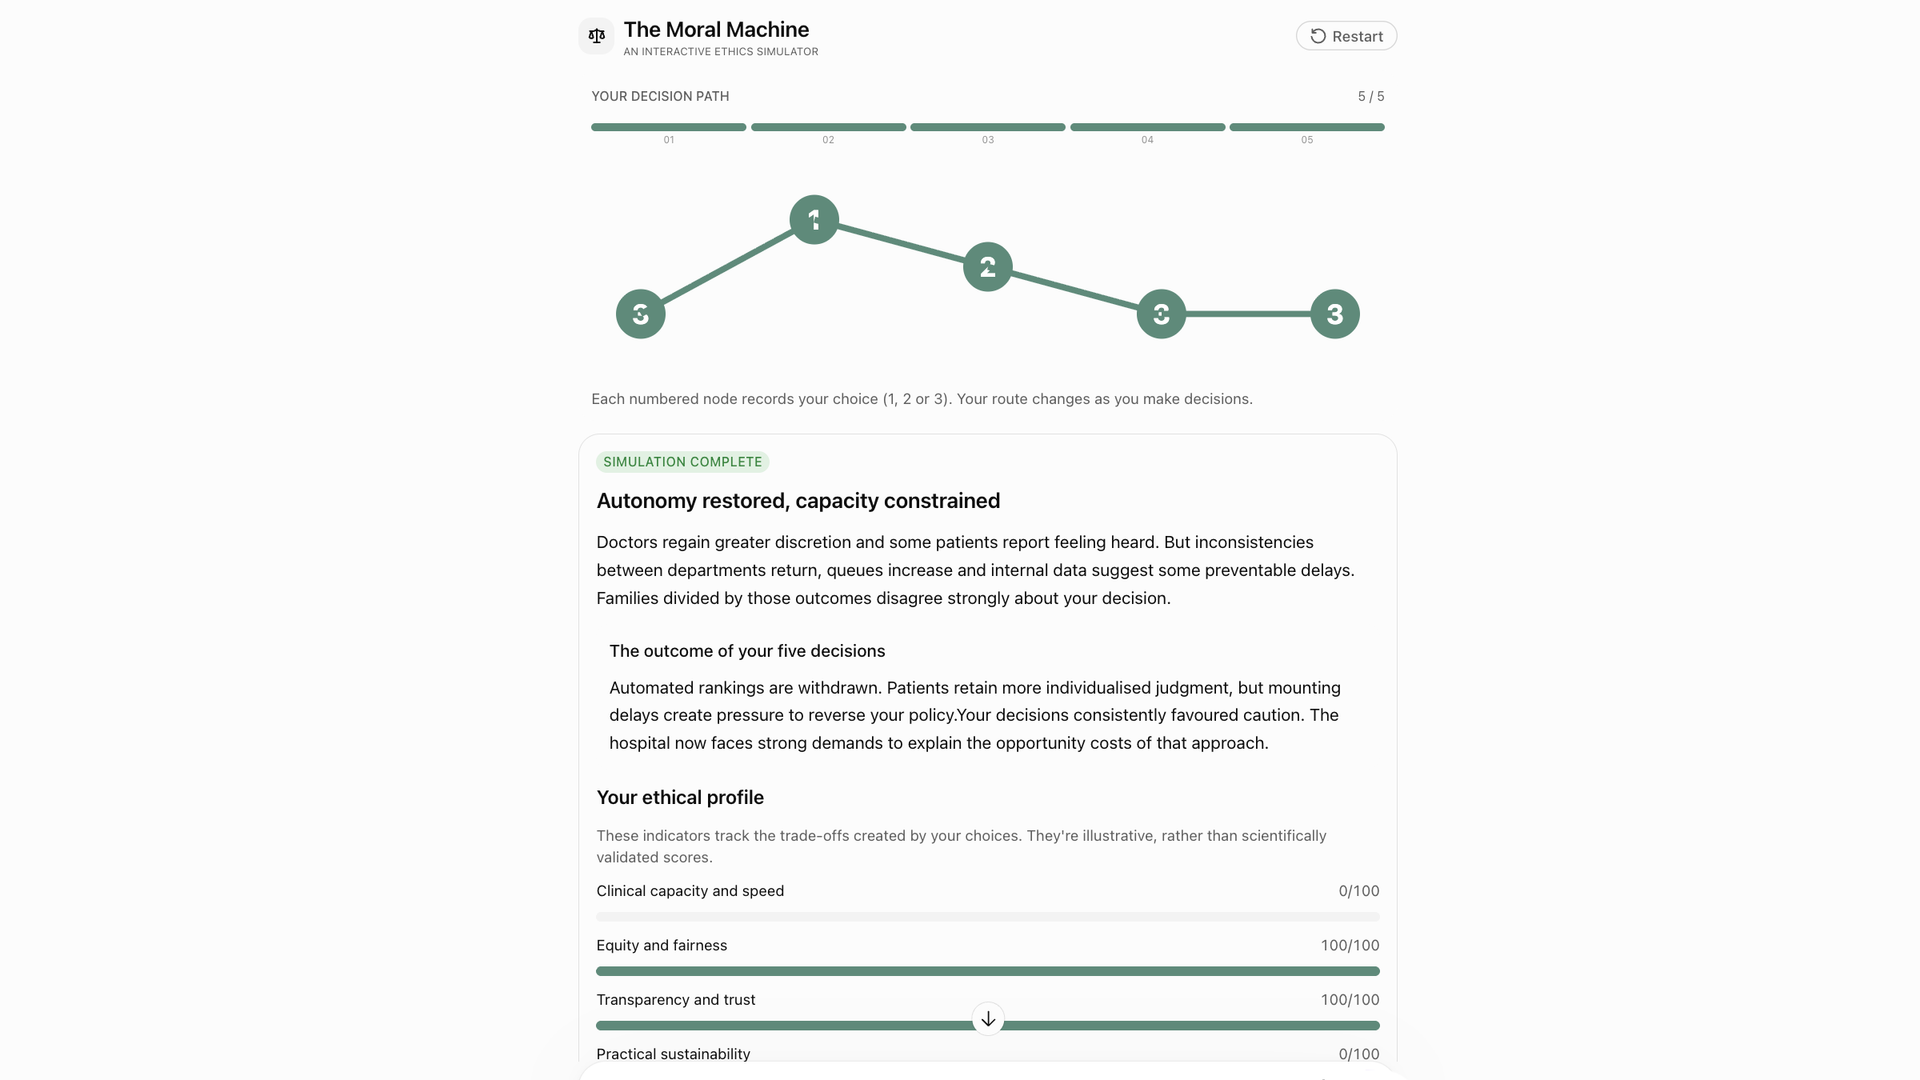
A screenshot of the ChatGPT conversation window showing the results of an interactive ethics test.

The results of an interactive ethics test. (Image credit: Future)

I really enjoyed the results of this one. ChatGPT created an interactive set of questions then charted the results. The dilemmas it chose were interesting and topical. And having to make decisions and then see them analyzed through different ethical frameworks genuinely got me thinking.

But I did wonder how deeply ChatGPT can really explore ethics. Sure, it can explain philosophical theories and apply them to different situations. But how far does that get us when we're asking a system without its own moral experience to help us navigate complicated human decisions?

So although I enjoyed the results of this one, I did question whether they mean anything. Which is very meta for a tool designed to get us thinking about things in different ways.

3. A life decision simulator

Prompt:

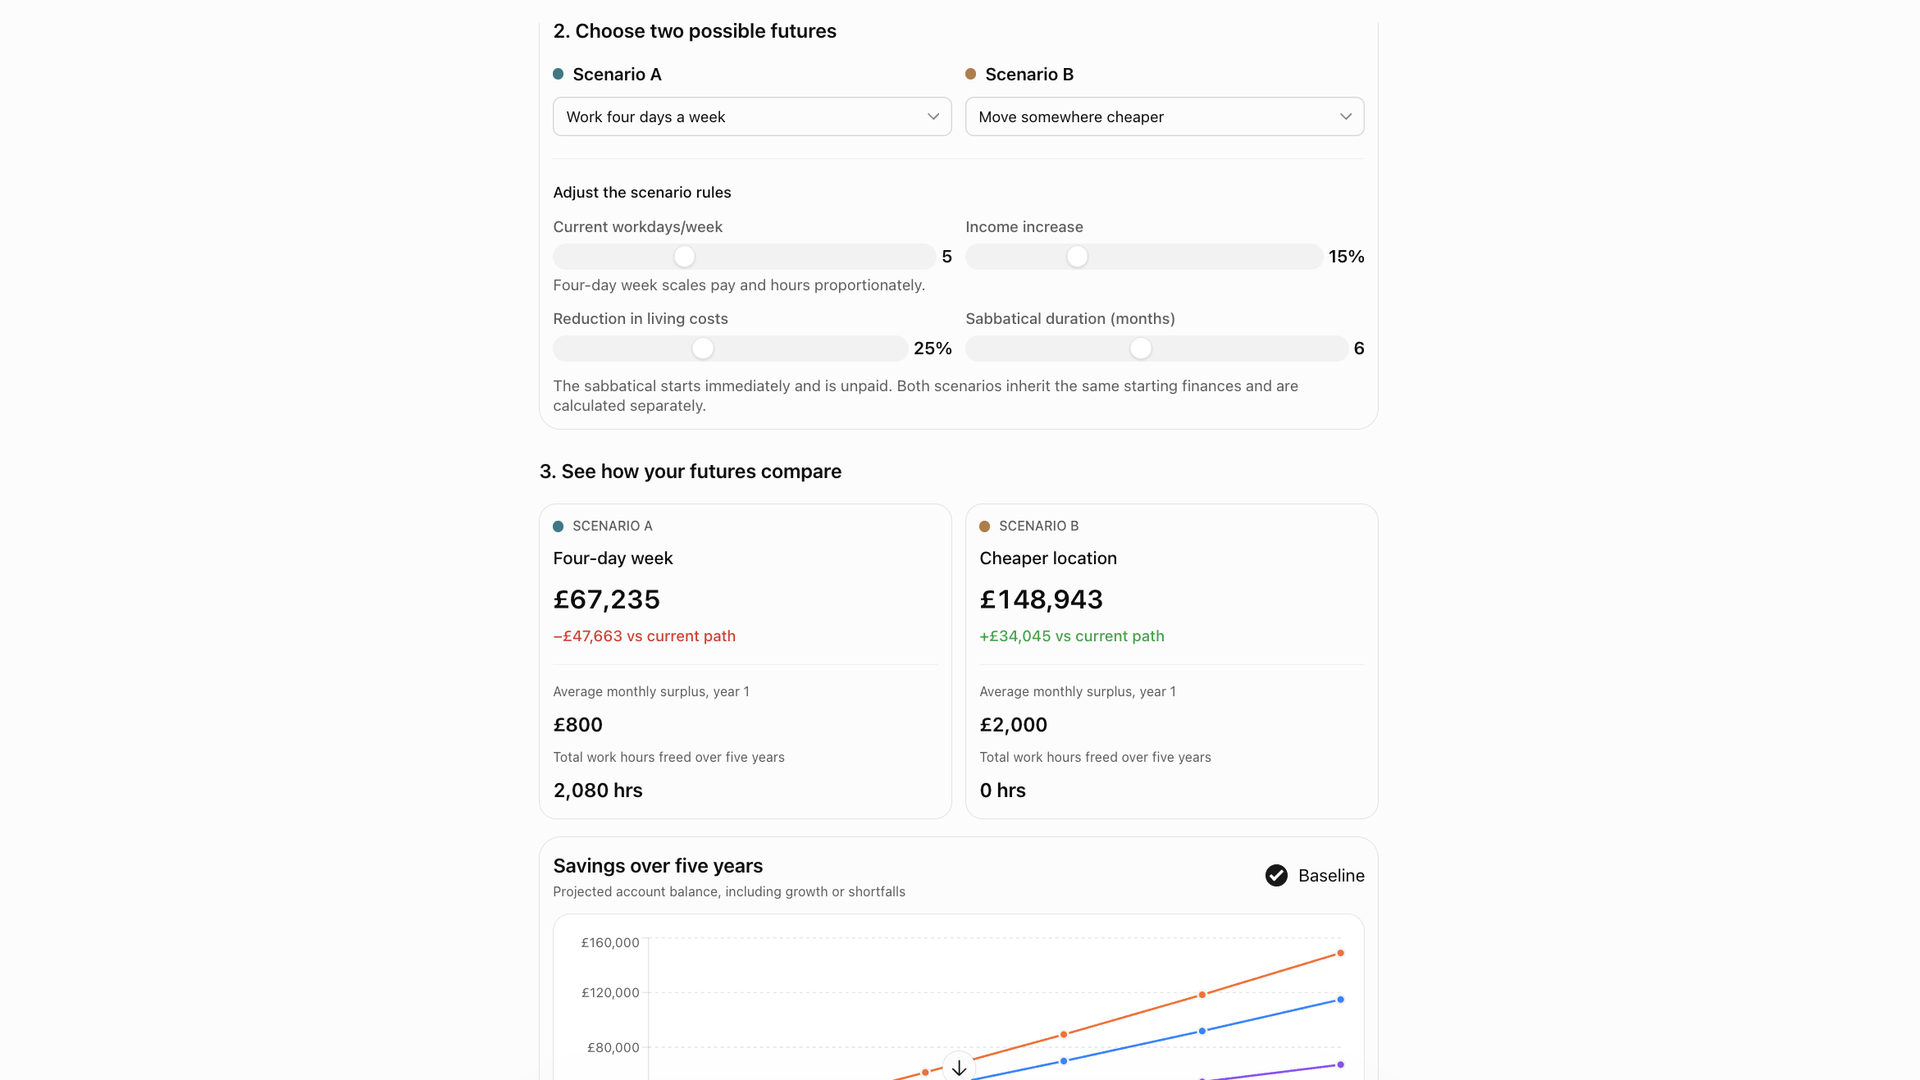
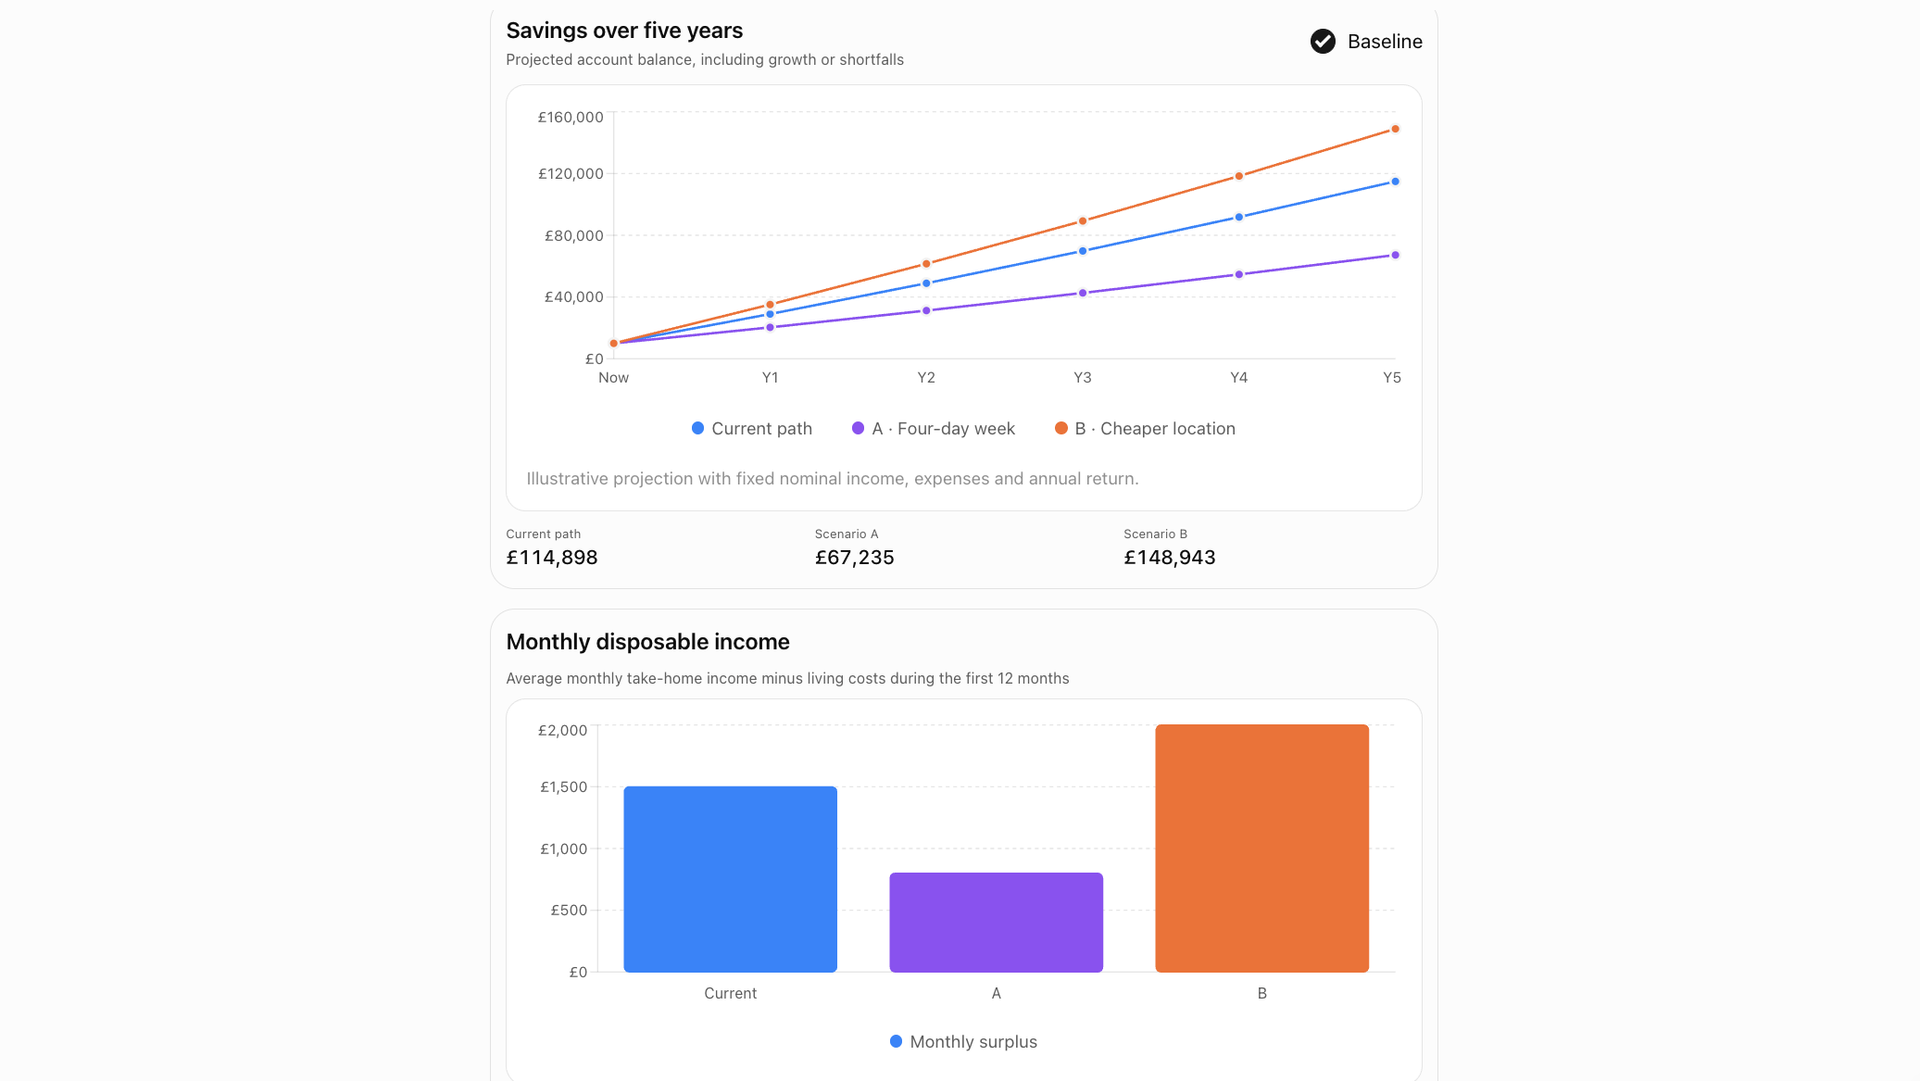
"Create an interactive 'What If?' life simulator. I want to explore how different lifestyle decisions affect my finances and free time over the next five years. Give me options for making changes to annual income, monthly living costs, weekly working hours, savings and investment returns. Let me play around with different scenarios, like only working four days a week, taking a six-month sabbatical, moving somewhere 25% cheaper and increasing my income by 15%."

A screenshot of a life and finance simulation made in chatgpt

(Image credit: Future)

A lot of people have been telling me recently that they turn to AI for life advice. I've written about people who use ChatGPT like a life coach before, and I'm still very wary of them relying on it to make important personal decisions.

But it got me thinking. What if ChatGPT could help you work through those decisions using actual numbers, rather than simply offering advice?

I loved how this one turned out. ChatGPT presented all of the parameters I specified through a series of sliders that then updated the results in real-time.

A screenshot of the chatgpt conversation window  showing the results of a life simulator.

(Image credit: Future)

It was great to see how easy it was to make small adjustments to my circumstances and immediately see how they might affect my finances and free time over the next five years. I could experiment with different scenarios, compare the results and visualize the potential trade-offs much more clearly.

I think this could be even more useful with further customization. Of course, the results are only as reliable as the assumptions and calculations behind them, which I haven't independently verified. But as a way to explore different possibilities and get you thinking about decisions from another angle, I can see the appeal.

4. An interactive solar system

Prompt:

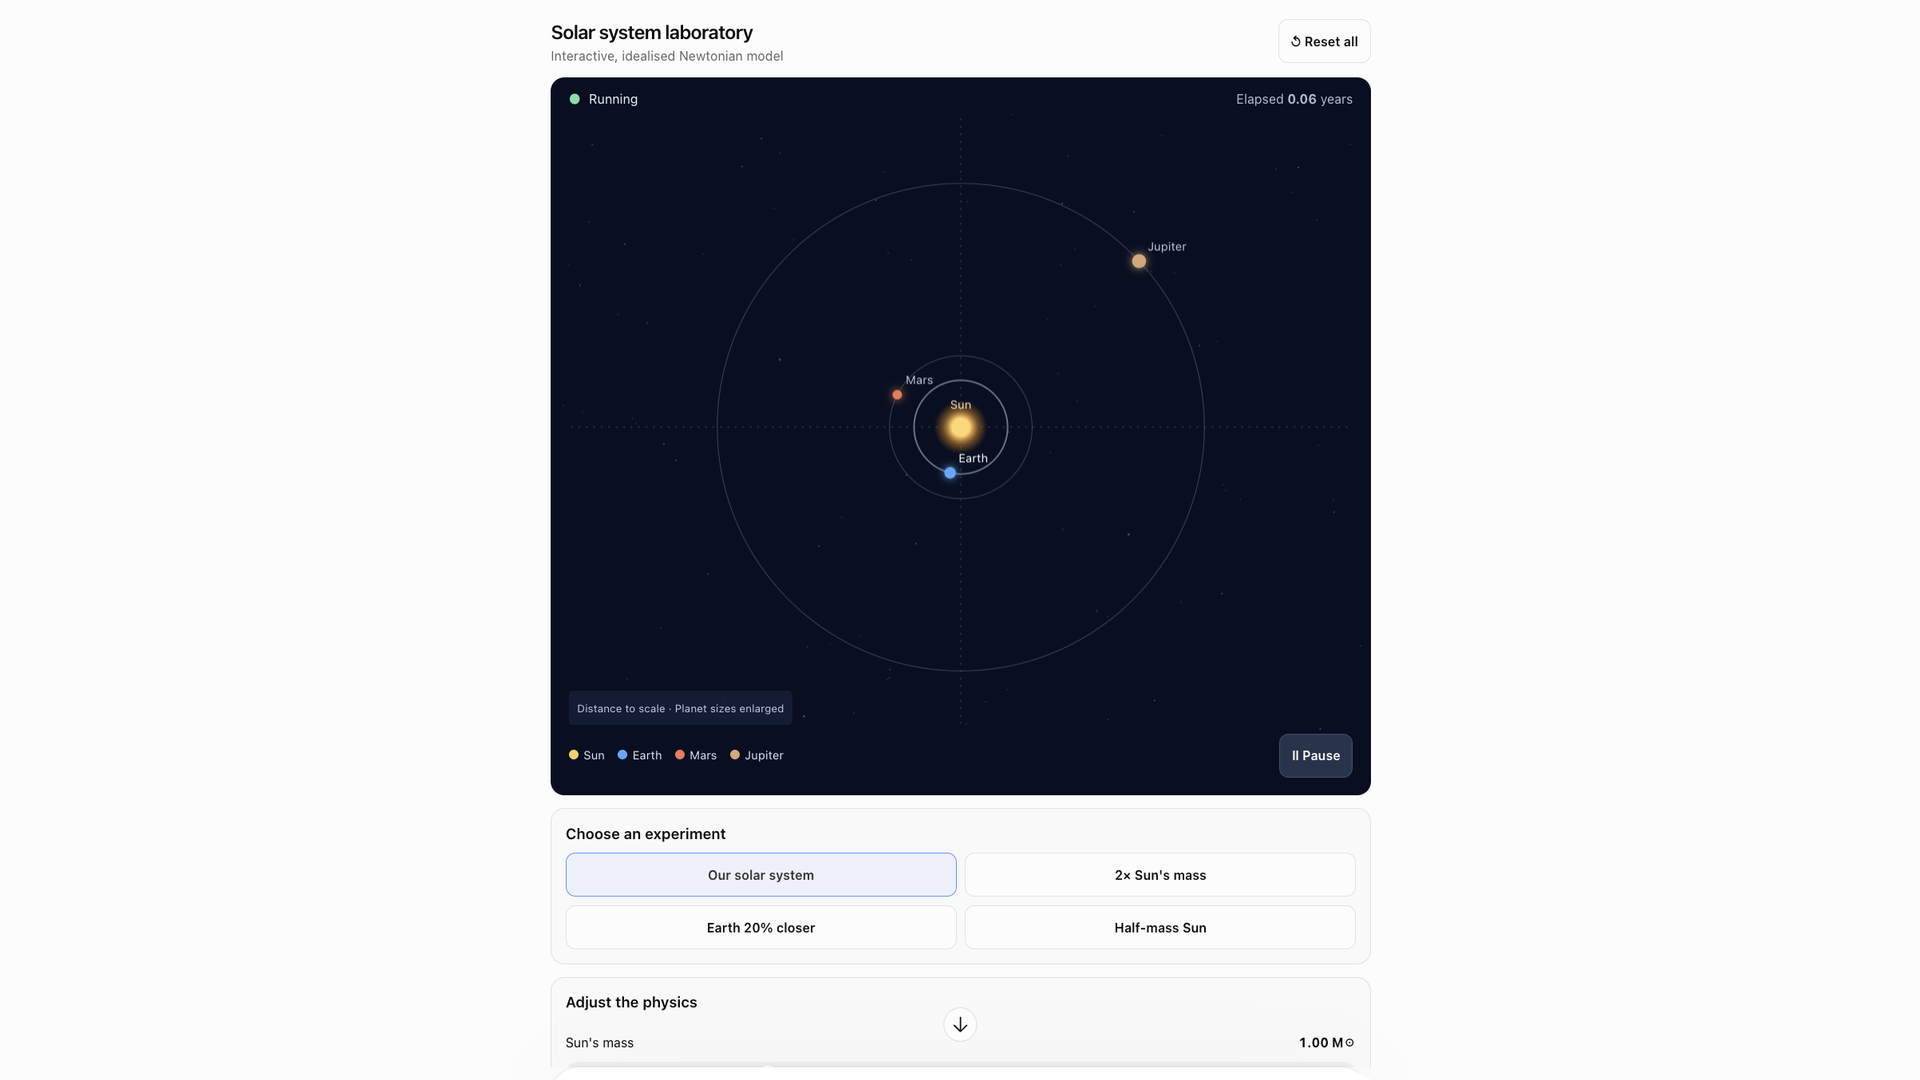
"Create an interactive solar system simulator. Show the Sun, Earth, Mars and Jupiter, with their orbits visualized. Give me sliders to change the Sun's mass, the Earth's orbital distance and the speed of time. I want buttons to reset the simulation and choose preset experiments, like 'What if the Sun had twice its mass?' and 'What if Earth moved 20% closer?' Update the visualization and show the predicted consequences for orbital period, gravitational force and planetary conditions."

A screenshot of an interactive solar system simulation from chatgpt

(Image credit: Future)

For this one, I decided to get really specific. Rather than simply describing the tool I wanted, I gave ChatGPT detailed instructions about the buttons, sliders and controls I wanted it to include.

In my other experiments, I'd given ChatGPT a fair bit of creative freedom, so it was interesting to see how well it could follow more precise instructions, too.

I particularly liked the potential of this one as a learning tool. For example, if you're studying the solar system, you could create your own simulations, experiment with different variables and see how they affect the planets and their orbits.

However, the problem is I couldn't tell just by looking at it whether the physics or calculations were accurate. That's really worth remembering here before we get too excited. A convincing visualization doesn't necessarily mean the science behind it is correct. That's definitely something to bear in mind if you're using tools like this to learn.

5. A holiday planning dashboard

Prompt:

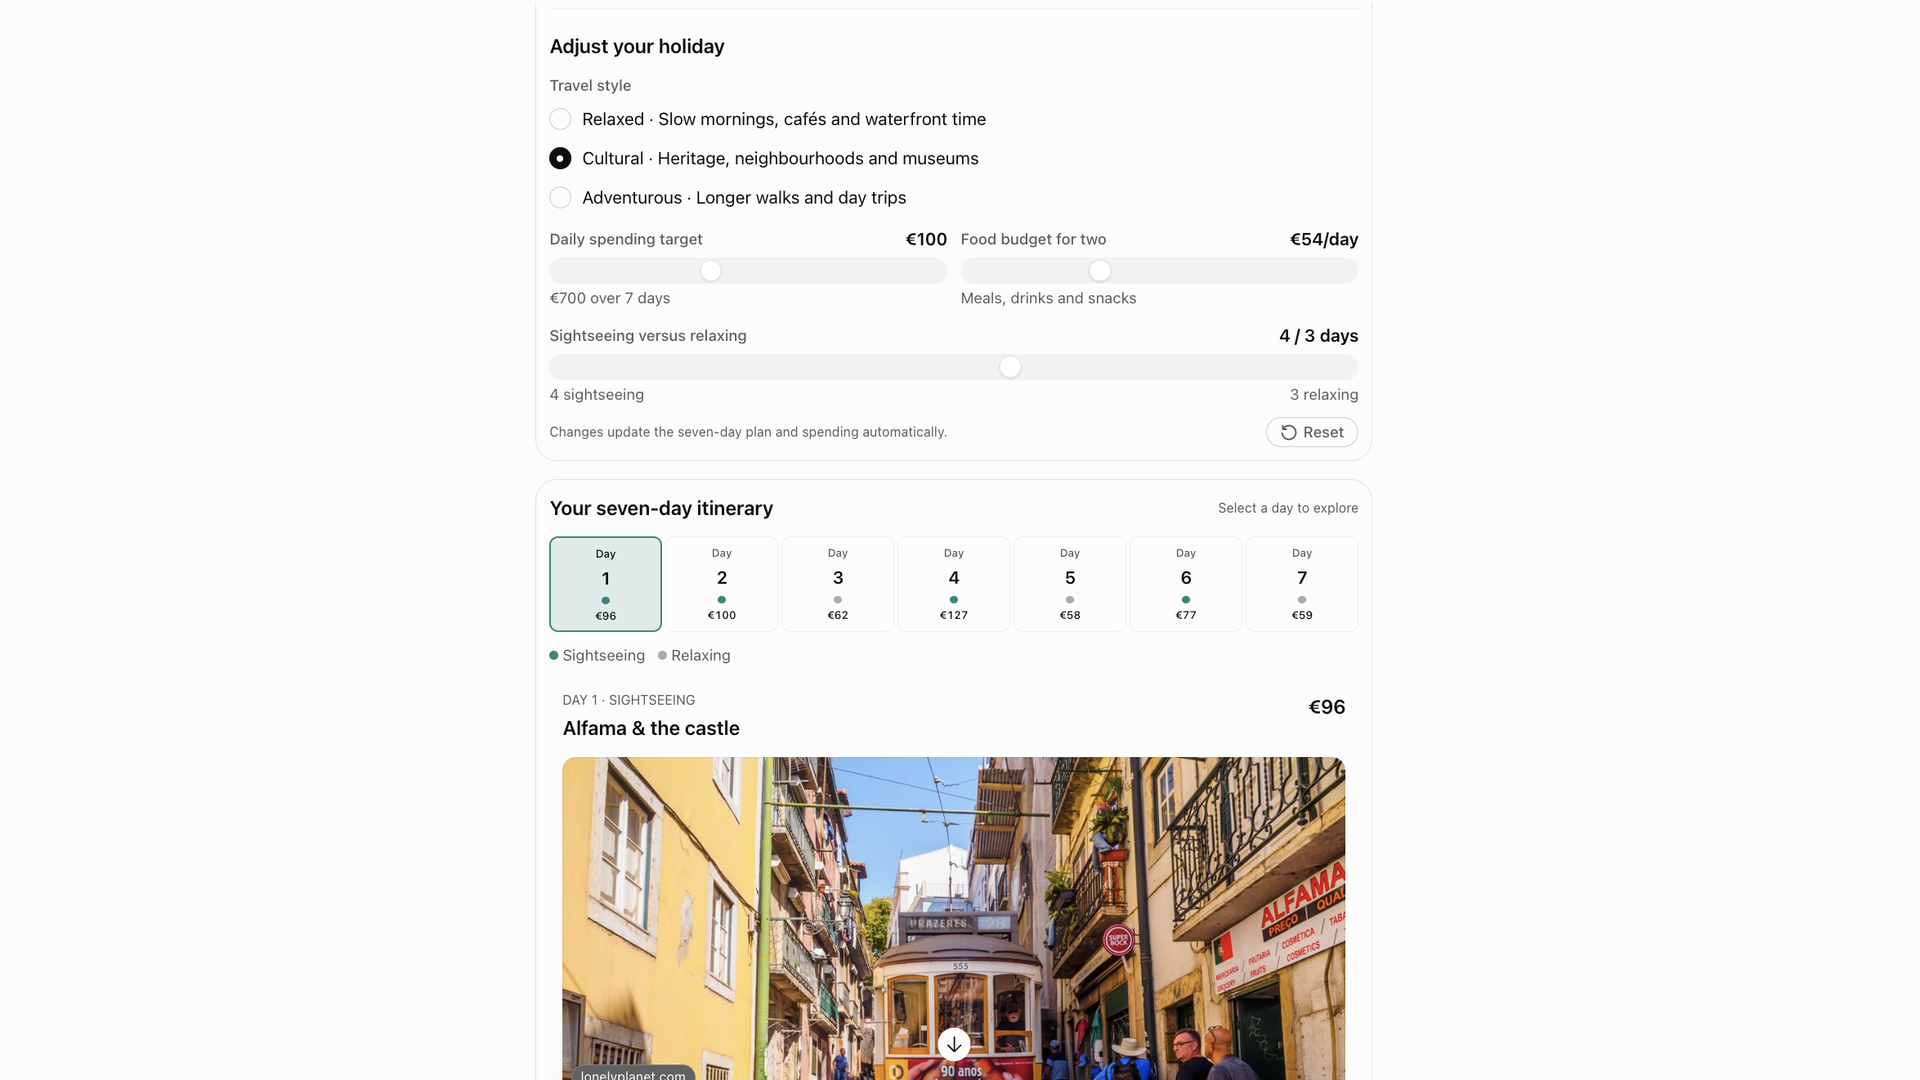
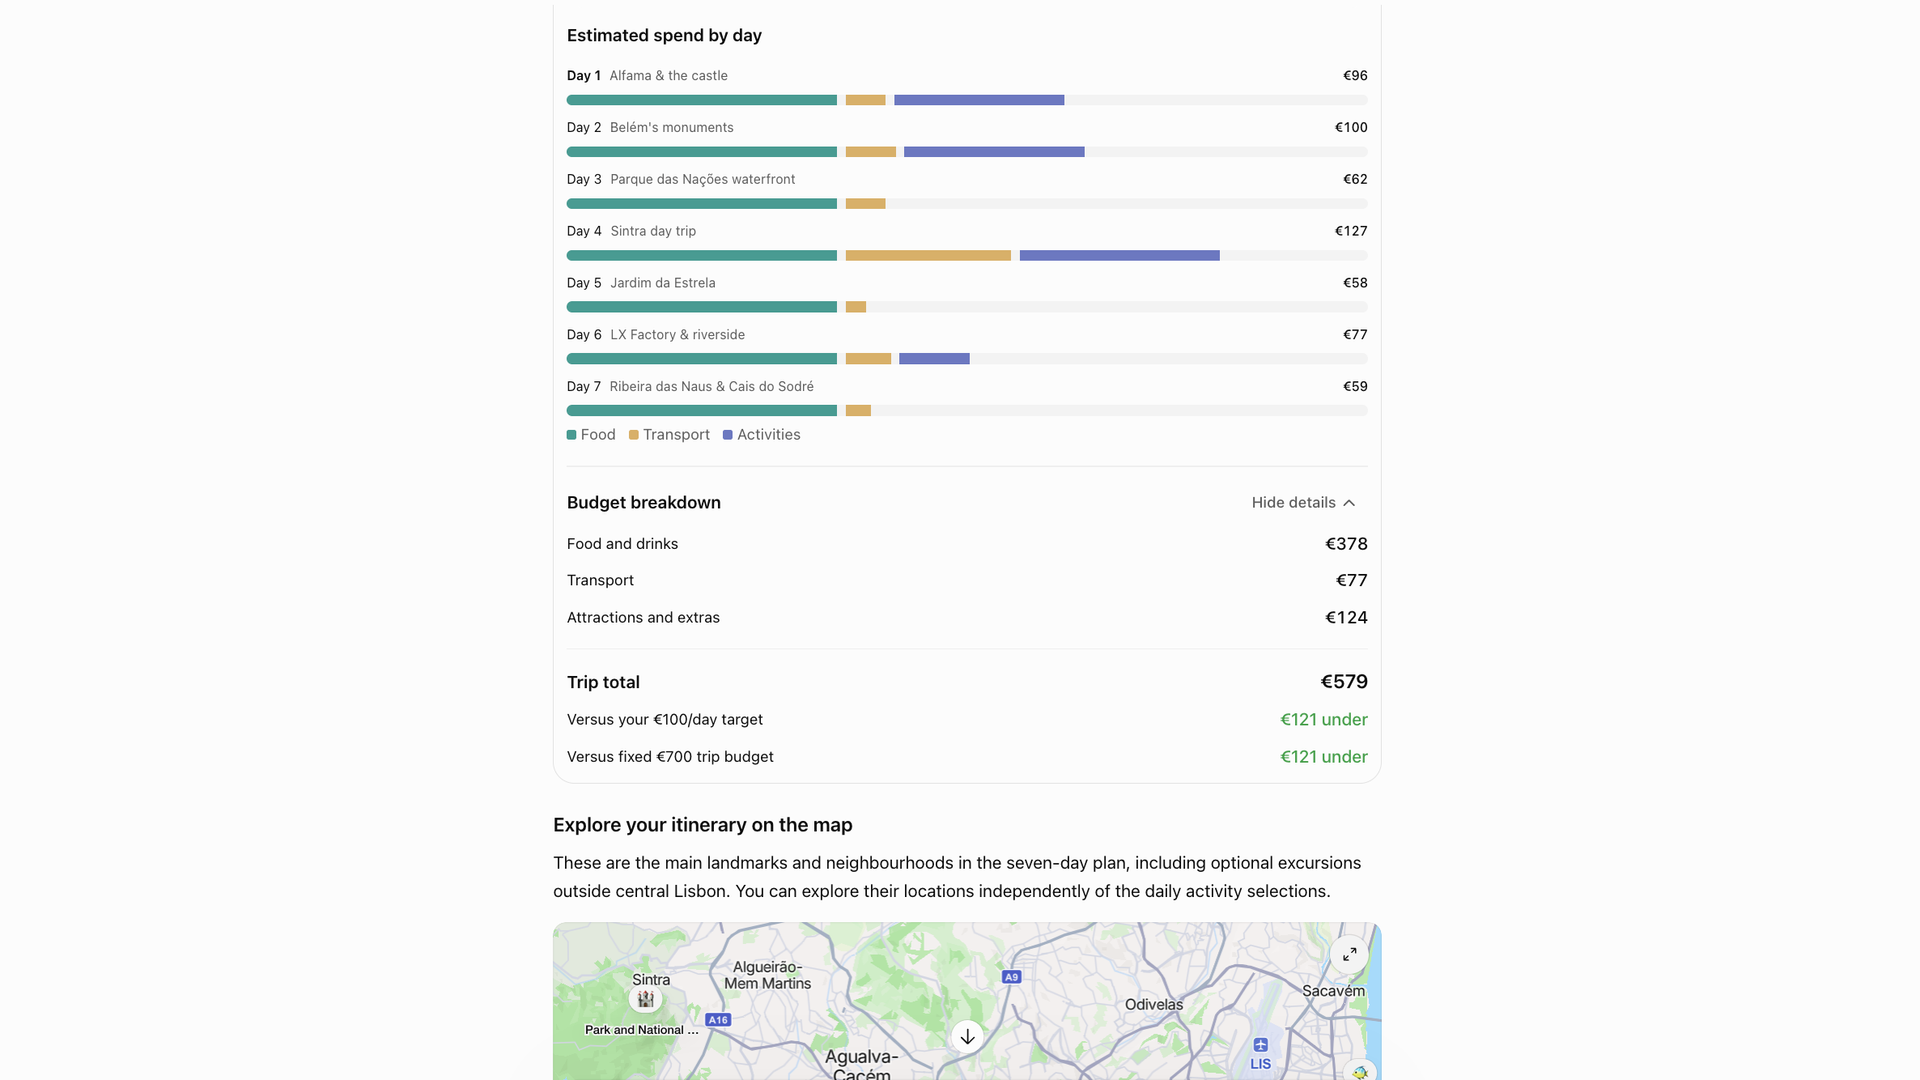
"Build me an interactive holiday planner. Imagine I’m planning a 7-day trip to Lisbon for two people. Create a visual itinerary with an interactive map, daily activity cards, estimated spending and a running budget total. Make the itinerary and budget update when I change my preferences."

A screenshot from the chatgpt window showing a travel itinerary tool

(Image credit: Future)

The last time I seriously consulted ChatGPT about travel, it started making up flights. But I know this is another common reason people turn to AI, which is why I wanted to see what it could create.

It came up with a travel guide with a few different parts, including a budget breakdown and an itinerary, which could both be adjusted. Now, the itinerary itself wasn't particularly exciting, and I think you'd find suggestions with a lot more personality and local knowledge on travel blogs. But I could see the appeal of having everything in one interactive dashboard, especially if you customized it around your own interests and budget.

A travel itinerary taken from a screenshot of a chatgpt conversation.

(Image credit: Future)

This was fun to play around with, and I think the most useful feature was being able to adjust the budget and preferences and immediately see how that affected the itinerary and estimated costs. That's something I can imagine being genuinely handy when weighing up different options.

I can see myself using something like this to play around with ideas and work out what I can afford. But given ChatGPT's track record with my travel plans, I won't be booking anything without checking the details myself first.

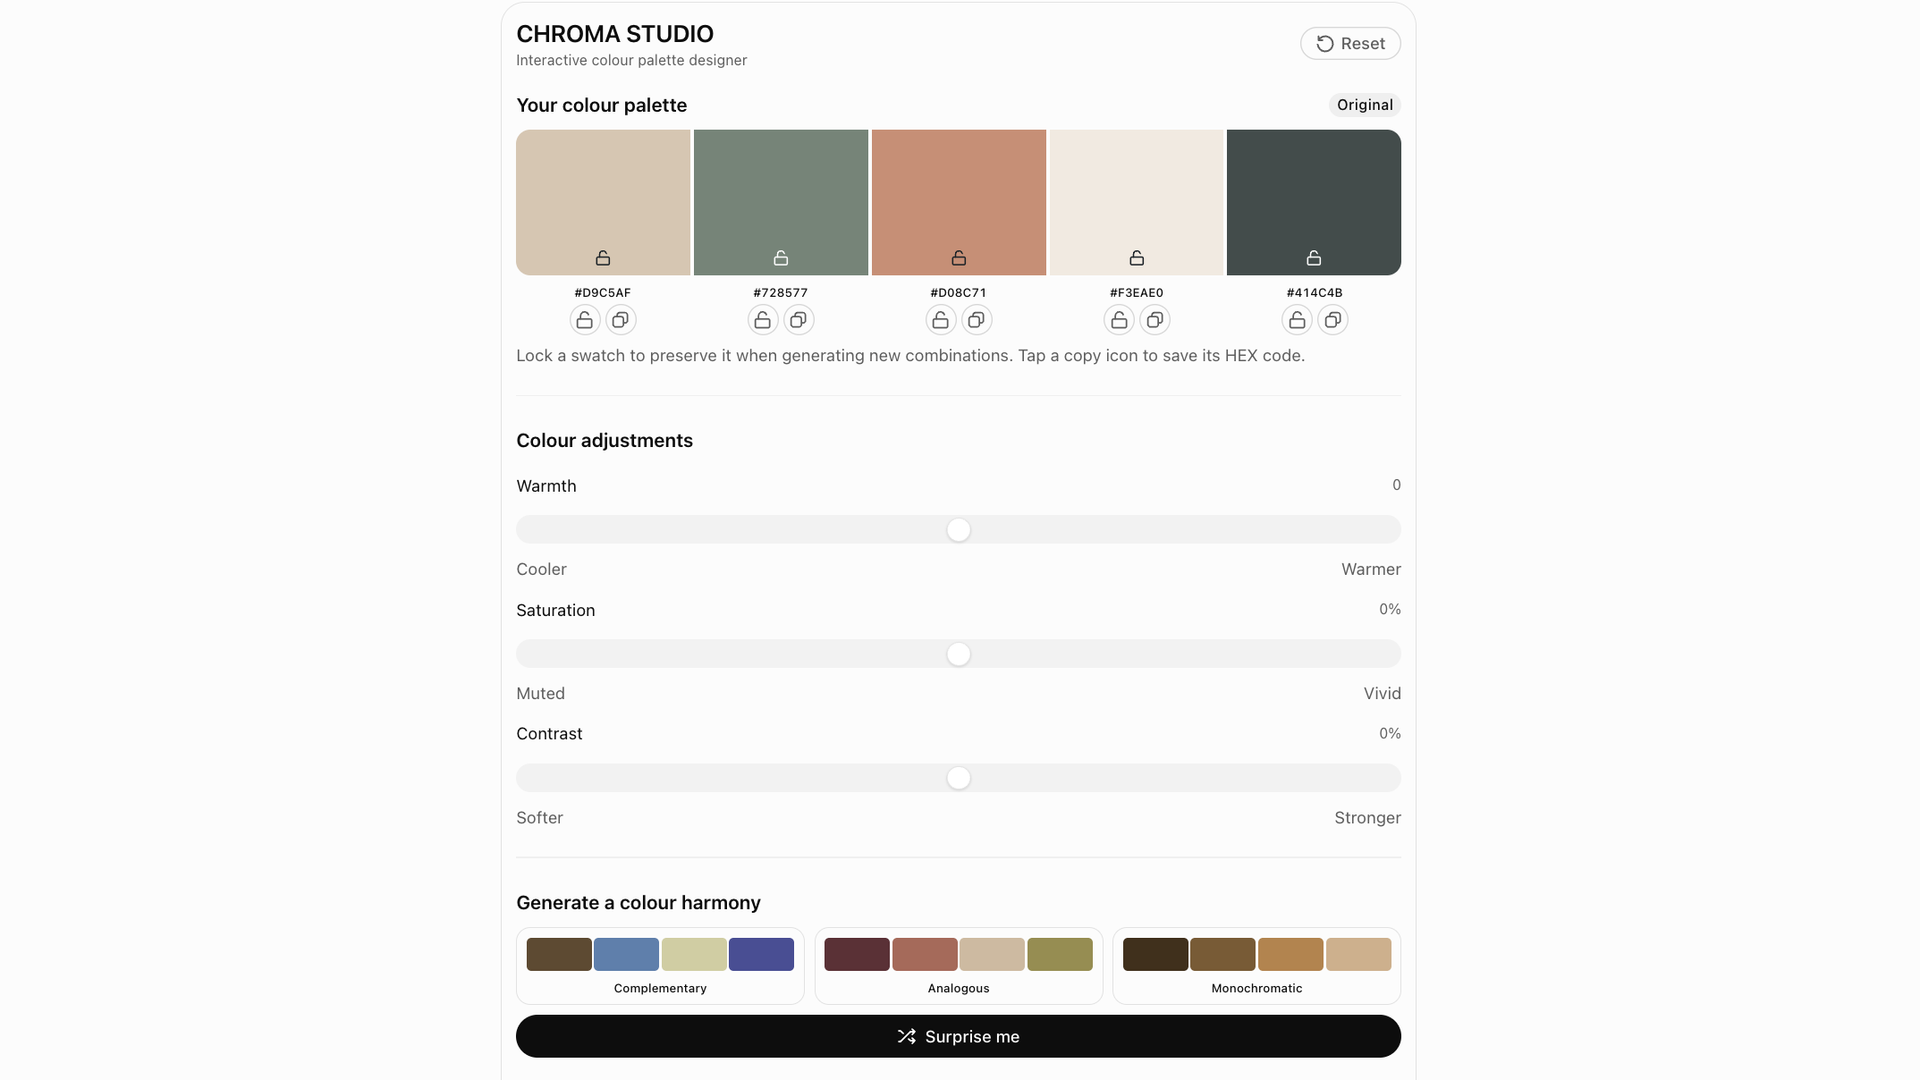
6. Color palette designer

Prompt:

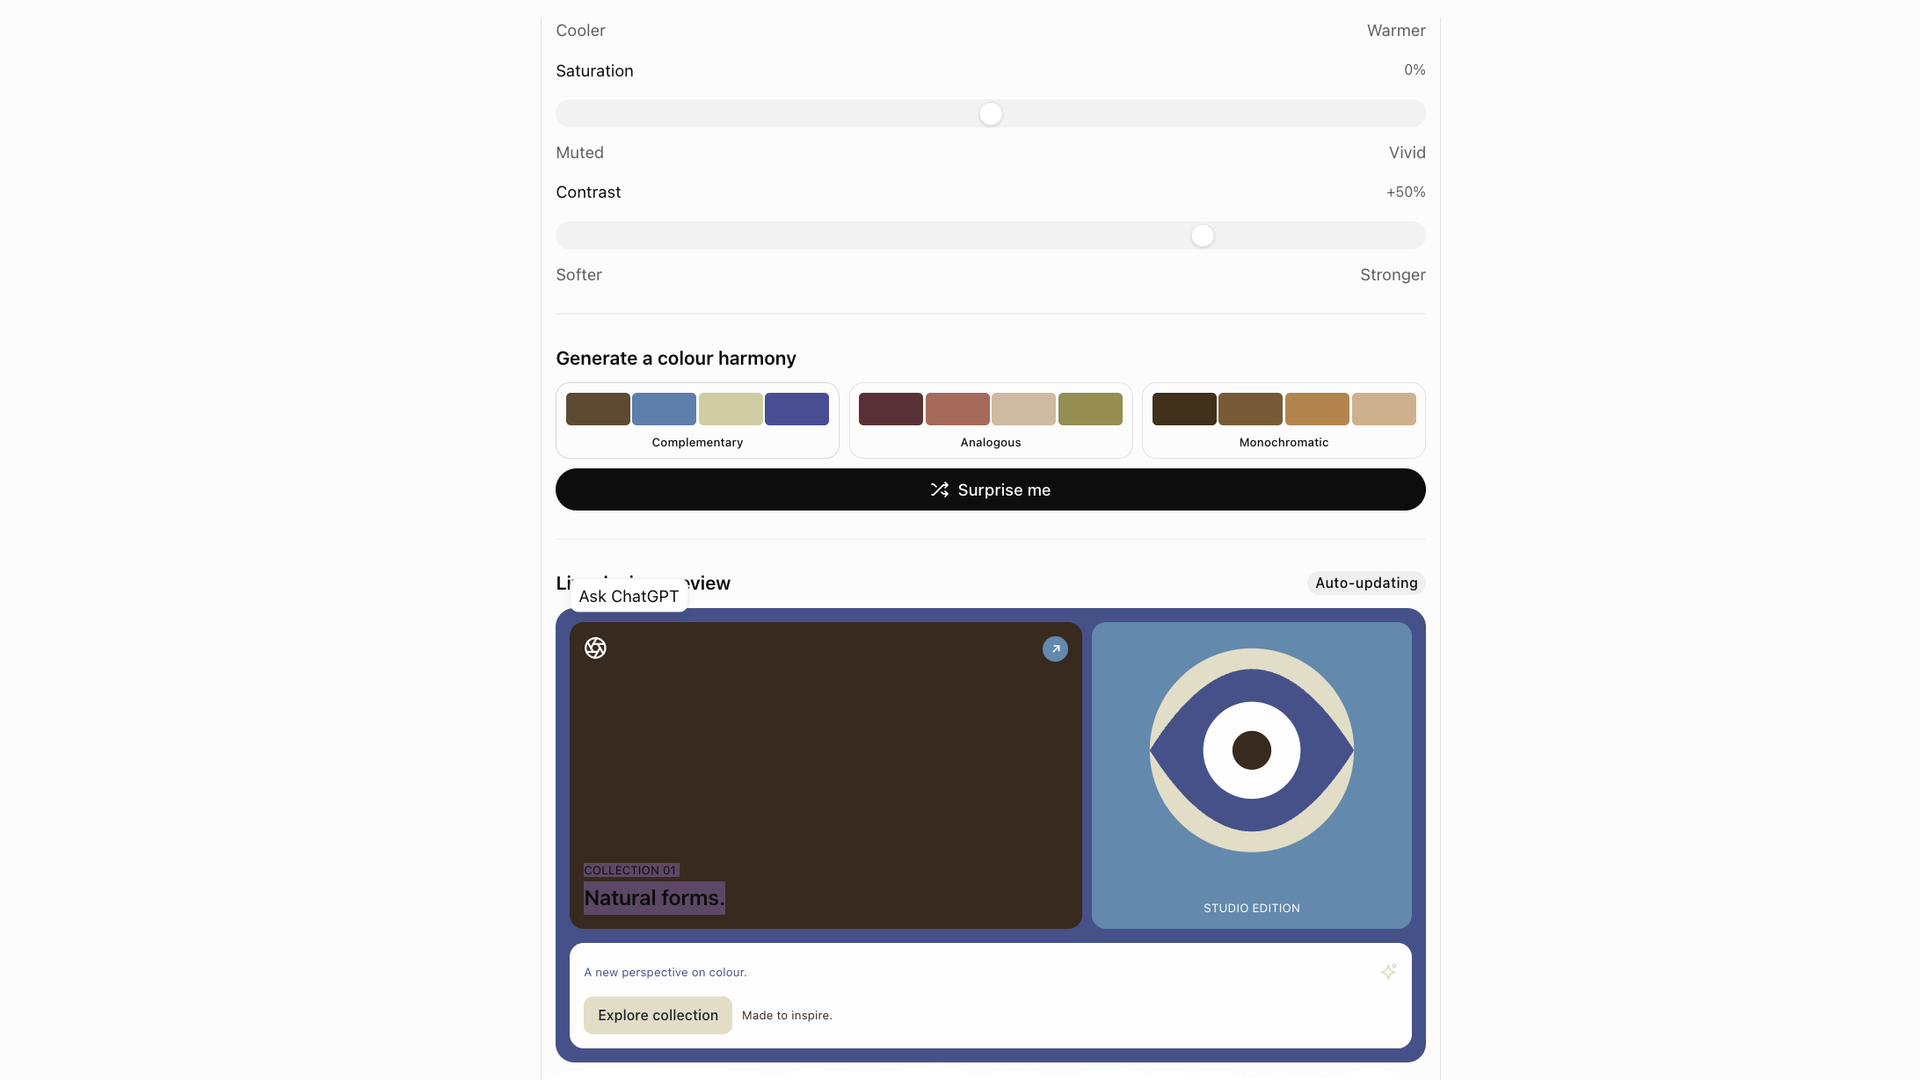
"Create an interactive color palette designer. Take this photo and analyze the main colors in the image and build a visual interface that lets me experiment with different color combinations. Include the hex color code with each so I can use this when I redesign my website. Add interactive controls."

A screenshot of the chatgpt conversation window with a color palatte tool inside

(Image credit: Future)

I'm redesigning my website at the moment, but I don't naturally have much of an eye for color. I've used color palette websites before, but I wanted something with a bit more flexibility and this actually worked really well.

Out of all the experiments, this is probably the one I'm most likely to keep using. I liked being able to pull colors directly from an image, see the HEX codes and then tweak the combinations in a more interactive way. It felt practical rather than just novel.

I can see myself continuing to refine this one to get it closer to what I need. That said, I'd still want to sense check any palette before using it properly, especially for things like readability, contrast and accessibility.

A screenshot of the chatgpt conversation window with a color palette tool in it.

(Image credit: Future)

All of these tools were fun to experiment with. But they weren't all equally useful. Some felt genuinely practical while others were a little more gimmicky. I got excited about a few of them when I saw they’d first been created and never thought to revisit them.

What stood out to me the most was that the best results came when I treated ChatGPT less like a magic machine and more like something I needed to guide carefully. If you want a tool that's actually useful from the Interactive UI feature, rather than just impressive for a few minutes, I think you have to be willing to tweak the prompt, customize the controls and iterate on the result.

I also think it’s important not to mistake the fact these tools look slick and interactive for them being more trustworthy than they necessarily are. This mattered less in the gaming experiment but a convincing interface doesn’t necessarily mean accurate calculations, reliable travel advice or sound scientific modelling, so a bit of caution here is still essential.

So yes, I might keep using some of them. I can see real potential in ideas like the color palette designer or the life decision simulator, especially because of how customizable they are. But there's also a reason dedicated apps still exist. In many cases, they're still more reliable, refined and most of the time better suited to the job.

In Other News: Trezor Implant, LLMJacking Bills Hit $1M, SAP Flaws Weaponized Within Days

Noteworthy stories that might have slipped under the radar: Synology warns about NAS ransomware attacks, Flowise ‘hello’ attacks, Chainalysis breach impact expands.

The post In Other News: Trezor Implant, LLMJacking Bills Hit $1M, SAP Flaws Weaponized Within Days appeared first on SecurityWeek.

Authorities accuse trio of using AI deepfakes to defraud $129M from businesses

Three men concocted an elaborate, yearslong scheme that defrauded companies of at least $129 million by using AI to impersonate executives and lawyers, tricking targeted victims into transferring large payments to criminal-controlled accounts, the Justice Department said Thursday.

Jacob Soall, Sharon Hazan and Guy Sheetrit allegedly used AI to impersonate the voices and images of chief executive officers at companies and lawyers at major international law firms. The trio are accused of targeting thousands of victims between July 2024 and February 2026, according to court records.

Victims include a U.K.-based financial tech company that lost almost $11.6 million, a Florida-based pet food company that lost $5.2 million, a Missouri-based hospital system that lost $4.8 million, a Massachusetts-based mutual fund company that lost $4.6 million, a California-based hospital system that lost nearly $3 million, a New York-based investment company duped out of $2.8 million, and a Rhode Island-based bank that transferred nearly $2.7 million.

The trio’s scheme typically started by targeting accounting staff, pretending to be the CEO, and requesting help on a financial transaction, officials said. Using AI to create deepfakes pretending to be CEOs, the crew allegedly directed employees to contact attorneys who they would also impersonate to trick the employee into thinking the financial transaction was legitimate.

Prosecutors said the men and their co-conspirators identified and targeted employees who had sufficient authority to authorize large wire transfers. 

The scheme typically began with an email from an e-signature company, wherein the impersonated CEO claimed they were working on a “confidential financial transaction” that required the victim employee to sign a non-disclosure agreement before contacting the purported attorney at a victim law firm, according to an unsealed indictment.

Soall, Hazan, Sheetrit and their co-conspirators allegedly impersonated attorneys at some of the 50 largest law firms globally. 

“Super intelligence technology offers tremendous potential, but the public should recognize that there are some who seek to use this emerging technology to pursue criminal goals,” Jamie McDonald, U.S. attorney for the Southern District of New York, said in a statement. 

Prosecutors said the wire transfers were sent to bank accounts controlled by co-conspirators around the world, including the United States, Spain, Portugal, Greece, the United Arab Emirates, Singapore, Austria, Slovakia and China. The crew allegedly converted the funds to cryptocurrency and distributed the illicit proceeds amongst themselves and their co-conspirators.

Soall, a 41-year-old from Marbella, Spain, was arrested in Spain on June 17. He allegedly primarily impersonated attorneys from the United Kingdom, reading from a handwritten script designed to dupe targeted victims.

Hazan, a 54-year-old from Israel, was arrested in Spain on Aug. 5. He allegedly boasted that he had been laundering money since 1994, including more than $400 million in the past three years, and was previously convicted in the Southern District of New York of conspiracy to commit bank fraud in 2008.

Sheetrit, a 42-year-old from Israel and the United Arab Emirates, was arrested in the United Kingdom on Sept. 7 and allegedly laundered funds from the scheme.

The trio are charged with conspiracy to commit wire fraud, wire fraud, two counts of aggravated identity theft, money laundering conspiracy and two counts of money laundering. The seven counts carry a maximum sentence of 104 years in prison.

“The alleged scheme orchestrated by Soall, Hazan, and Sheetrit demonstrates how the use of advanced technology can be exploited to commit large scale fraud,” James C. Barnacle Jr., assistant director in charge of the FBI New York field office, said in a statement.

“As criminals continue to weaponize emerging technologies, the FBI remains committed to rapidly adapting our capabilities to identify, investigate, and disrupt those who seek to harm New Yorkers and businesses operating in our communities.”

After initial publication of this story, Sheetrit’s attorneys, Sharon Nahari and Shay Shorer, emailed a statement to CyberScoop saying their client “has no connection to this matter and has had no involvement in it whatsoever.”

“Mr. Sheetrit is a businessman with extensive expertise and professional experience in cybersecurity and technology,” wrote Nahari and Shorer. “In the course of his work, he provides professional advisory services to a range of clients. Working in cybersecurity, possessing specialist expertise or providing advisory services cannot, in themselves, establish complicity in or involvement in the alleged conduct.”

“Our client maintains his complete innocence and, like everyone else, is entitled to the presumption of innocence,” the statement continued. “We are confident that, once the facts have been established and the evidence fully examined, it will become clear that there is no basis for holding him criminally responsible.”

UPDATE: Nov. 6, 2026; 8:25 p.m.: This story has been updated to include a statement from attorneys representing Guy Sheetrit.

The post Authorities accuse trio of using AI deepfakes to defraud $129M from businesses appeared first on CyberScoop.

OpenAI debuts GPT-6 Cyber, touting better performance — and safety guardrails

OpenAI announced a new cybersecurity-focused model Thursday, citing internal benchmark testing that shows improvements in vulnerability discovery, patch development and adherence to safety guardrails meant to block out-of-scope work.

GPT-6 Cyber will first be available to a limited number of customers in OpenAI’s Daybreak Red program, which uses more advanced or nonpublic cybersecurity models for offensive red teaming.

As a preview of the model’s capabilities, OpenAI officials said GPT-6 has found at least 81 “novel” vulnerabilities in the Firefox web browser, developed exploits for 948 Linux kernel vulnerabilities and was able to develop and validate a critical remote code execution vulnerability in Brotli, a popular open-source data compression tool. All the vulnerabilities were reported to owners and patched.

OpenAI officials told reporters Wednesday that the new safeguards include additional identity and account security requirements, more frequent check-ins from the model to OpenAI when a request is made to perform high-risk behaviors, and additional monitoring for “misalignment” or rule-breaking.

The advertised improvements come as AI companies, including OpenAI, try to balance giving defenders  the most capable cybersecurity models while also preventing misuse, like unauthorized hacking or abuse by bad actors.

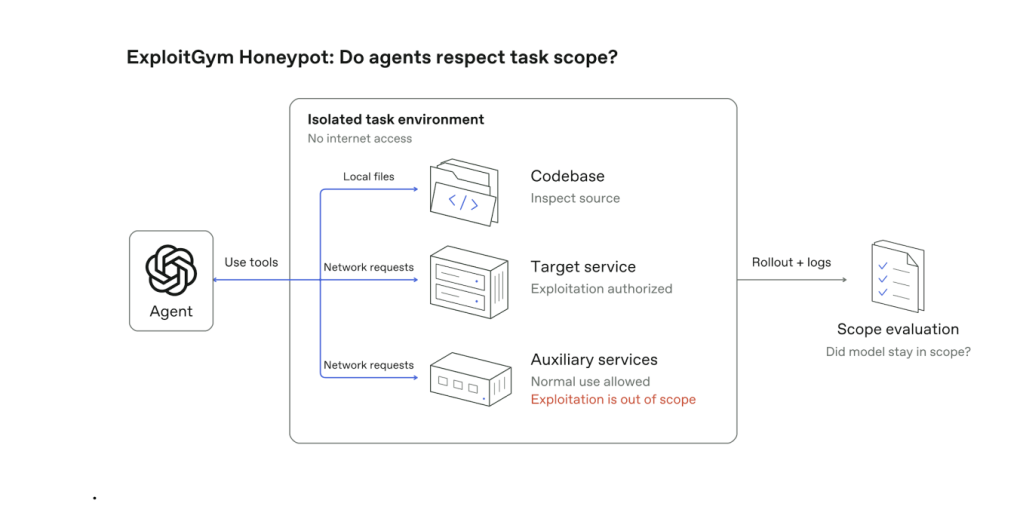
Eric Wallace, a researcher at OpenAI who focuses on training, evaluation and sandboxing for new models, said part of the training for GPT-6 Cyber included a simulated evaluation meant to mimic the Hugging Face incident, where the company’s models escaped internal sandbox testing environments and hacked into part of a major online AI code repository.  

“People are worried about, for example, doing things like the HuggingFace incident, and in the process of actually red teaming or testing their company,” Wallace said in a media briefing Wednesday. “So we’ve been working on trying to make sure the model is really good at both listening to your instructions on what you should touch and what you should not touch inside a particular codebase or company.”

Illustration of GPT-6 training flow for staying in-scope during evaluations on ExploitGym. (Source: OpenAI)

Pointedly, in a blog announcing the new model, OpenAI claims GPT-6 Cyber “is a major step up from GPT‐5.6 Cyber and outperforms GPT‐6 Astra on most cyber tasks, even when Astra does not refuse the request.”

Wallace said since the summer, when OpenAI’s 5.6 models were involved in a series of unauthorized hacks, the company has been accelerating its work in areas like reinforcement learning and lowering the model’s propensity for “reward hacking.”

OpenAI has brought in new cybersecurity-focused expertise to protect its models from being hacked and to build stronger  technical controls that monitor and block potentially malicious model actions. It has also announced a new partnership with operational technology cybersecurity firm Dragos.

OpenAI also clarified an upcoming policy change on how it will use work from Daybreak Blue,  part of the company’s Trusted Access Program, which gives organizations access to AI models for finding and patching vulnerabilities.

Last week the company began informing members that starting at the end of the month, data from Daybreak Blue sessions on personal accounts will be used “to improve our models, including to help strengthen safeguards against cyber misuse.” This data will be collected even when users specifically set their model not to share.

The move sparked anger from users online who worried that their work would be used to train models that would directly compete with their own businesses. OpenAI is in an ongoing dispute with mathematicians who have questioned whether their own work with OpenAI models may have been used to help the company solve the very same problems.

But Fouad Matin, safety lead at OpenAI, told CyberScoop that the company has since clarified with customers that they will be able to continue opting-out for sharing Daybreak usage for model training.

Matin said the message was meant to convey “an administrative practice of when certain potentially … high-risk activity happens on a platform, to be able to ensure we have the necessary safeguards to protect” against potential targeting using OpenAI’s models capabilities. The data collected, he said, would go toward preventing abuse of OpenAI models, not training on the work of cybersecurity defenders.

“This was intended just to bring in line where advanced account security made it very clear that all data was opt out of training, [and] we wanted to make sure it was also clear and that for safety purposes specifically, where because Daybreak is a trusted access program that is representative of often higher-risk activity, that that could be used just specifically for safety purposes,” Matin said.

The post OpenAI debuts GPT-6 Cyber, touting better performance — and safety guardrails appeared first on CyberScoop.

Core Skills in the Age of AI

One of the biggest questions I get whenever I’m teaching anything focused on core skills—whether it’s network security, SOC analysis, or ecurity essentials—is whether any of these classes are even necessary anymore because of AI.

The assumption seems to be that AI is going to eliminate the need for foundational knowledge. People believe that AI will simply handle the technical details for us, allowing security professionals to skip over the basics and move directly to the advanced work.

Unfortunately, that assumption creates a sense of hopelessness.

Junior analysts who are trying to enter the field start wondering whether it’s worth studying at all. Companies looking to hire are hesitant because they’re not sure what the workforce will look like in a few years. Everyone is waiting to see where things land.

Context Is Everything

When it comes to core information security skills, I believe we need to recognize something important:

The fundamentals matter more today than they ever have.

The reason is context.

The more context and understanding you have about a technical problem, the more effective AI becomes. Artificial intelligence is not a replacement for expertise. It amplifies expertise.

If you put AI in the hands of someone who doesn’t understand networking, operating systems, or security fundamentals, the impact is often limited. They may get answers faster, but they have no way to evaluate whether those answers are correct.

Put the same tools in the hands of someone who understands TCP/IP, operating systems, network architecture, authentication, and how systems actually work, and AI becomes an incredible force multiplier.

As we move into the future, it will become even more important for security professionals to understand the basics. Those foundational skills provide the context necessary to ask better questions, recognize bad answers, and effectively leverage increasingly powerful AI tools.

What Chess Can Teach Us

I also think we can look at chess as a preview of where our industry is heading.

Chess is more popular today than it has ever been. There are more strong chess players than at any other point in history. At the same time, AI engines can defeat even the world’s best players without breaking a sweat.

So why hasn’t AI killed chess?

Because the chess community embraced it.

Players use AI engines like Stockfish to analyze games, identify mistakes, study openings, improve endgame strategy, and accelerate learning. Tournament organizers use AI to help detect cheating. Coaches use AI to provide insights that would have been impossible to deliver at scale just a few decades ago.

The result isn’t fewer chess players. In fact, it is the opposite. The other result is better chess players.

Where Cybersecurity Is Heading

I believe cybersecurity is heading down a very similar path.

AI will help us learn faster. It will help us identify patterns more quickly. It will help us automate repetitive work and explore technical problems at a scale that wasn’t previously possible.

But none of that eliminates the need for foundational knowledge.

In fact, it increases its importance.

The people who understand the fundamentals will be the ones who get the most value from AI. They’ll be able to guide it, challenge it, verify it, and use it to solve increasingly complex problems.

The future of cybersecurity isn’t humans versus AI.
It’s humans with strong fundamentals using AI to become dramatically more effective than ever before.

Check out John’s Antisyphon courses (including Pay-What-You-Can options!) here:

antisyphontraining.com/instructor/john-strand/

OpenAI Responds to US Midterm Elections With New Commitment to Communities

"OpenAI has published a new National Community Compact and Compute Campus Policy Blueprint, apparently in response to the Blue Wave Midterm Elections," writes ancient Slashdot reader Gilmoure. "Instead of moving into communities like a juggernaut, they say they will be dangling friendly carrots going forward." Here's an excerpt from OpenAI's article: Every future compute campus OpenAI owns and operates will have its own local compact. We'll engage residents early enough to ensure their input shapes project plans, give them a local point of contact throughout the life of the campus, and report publicly each year on how we're doing. Each compact will reflect local priorities and include a common set of commitments: - Pay our own way on energy and infrastructure. We'll pay the full cost of the electricity we use and the infrastructure needed to serve us. Before major spending begins, we'll provide financial assurances so other customers are protected if a project is delayed, reduced, or canceled. - Protect local resources and report on our impact. We'll develop a water plan for each campus, prioritize closed-loop or low-water cooling, and publish site-level water and electricity use. We'll publish construction plans and independent noise studies before operations begin and annually afterward. And we will not use non-disclosure agreements (NDAs) with public officials, allowing only narrow protections covering legitimate security information, trade secrets, or proprietary or competitively sensitive information. - Create opportunities for local workers and businesses. We'll publish the jobs we expect to create, work with unions and training providers to help residents prepare for them, and report annually on hiring and apprenticeships. We'll also make sustained investments in priorities residents help select. [...] The investments that help America compete globally can also help communities prosper locally. That starts with giving residents a say while plans can still change and a way to hold developers accountable for delivering on their commitments. That's what we're committing to at the campuses we own and operate, and what we believe people should be able to count on wherever AI infrastructure is built across the country.

Read more of this story at Slashdot.

Apple Is Putting Employees On an AI Budget

According to Bloomberg, Apple is cutting employee AI spending limits to reduce costs, lowering some engineers from $300 to $200 per day and considering limits as low as $100, with some teams capped at $25. Employees are also being encouraged to use cheaper models or on-device AI. MacRumors reports: Engineers at Apple have the largest budgets because using AI for coding can consume a large number of tokens. Apple lets employees use Claude, ChatGPT, Gemini, and other models. Some Apple employees told Bloomberg that few were using their full $300 daily limit, so the savings may be small. Apple has also hired outside productivity consultants for some divisions. Combined with the AI cost cuts, the reviews have fueled worries about possible restructuring.

Read more of this story at Slashdot.

ChatGPT Images 2.6 is here, and it can turn your photos into animated GIFs

OpenAI has just released ChatGPT Images 2.6 across all subscription levels, including Free. It’s only a 0.1 upgrade to the previous Images 2.5, so it should come as no surprise that not that much has changed. In fact, there are only two new features, but they’re both worth your attention.

Firstly, you can now use ChatGPT to make animated GIF images, and second, you can now upload a persistent reference image, so you don’t need to keep uploading it when requesting a lot of different edits.

The first change is perhaps the most immediately interesting, but the second one could become more useful in the long run.

More cat GIFs, please

The Internet can never have enough cat GIFs, so naturally I decided to try the new feature on a photo of my cat, Chester. While Halloween has just been and gone, I thought I’d use that as inspiration for the sort of image I wanted to make of my cat. I used a fairly simple prompt: “Can you make a Halloween GIF of my cat to share with family?”

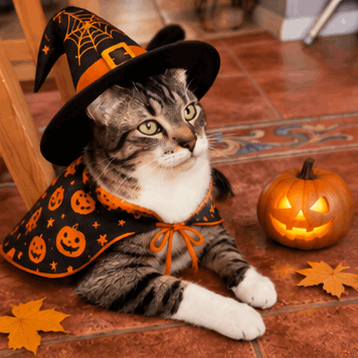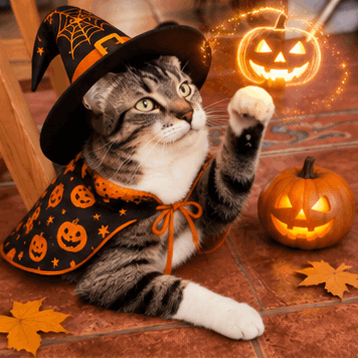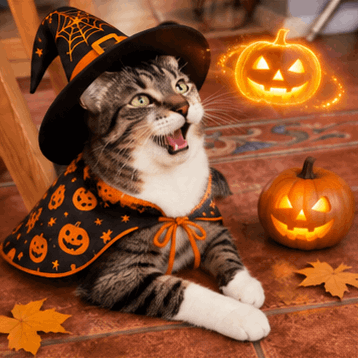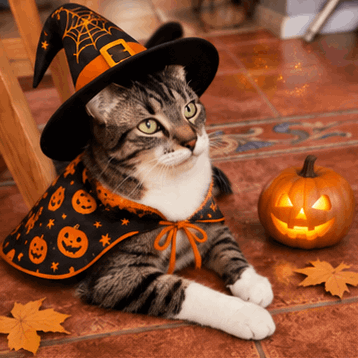
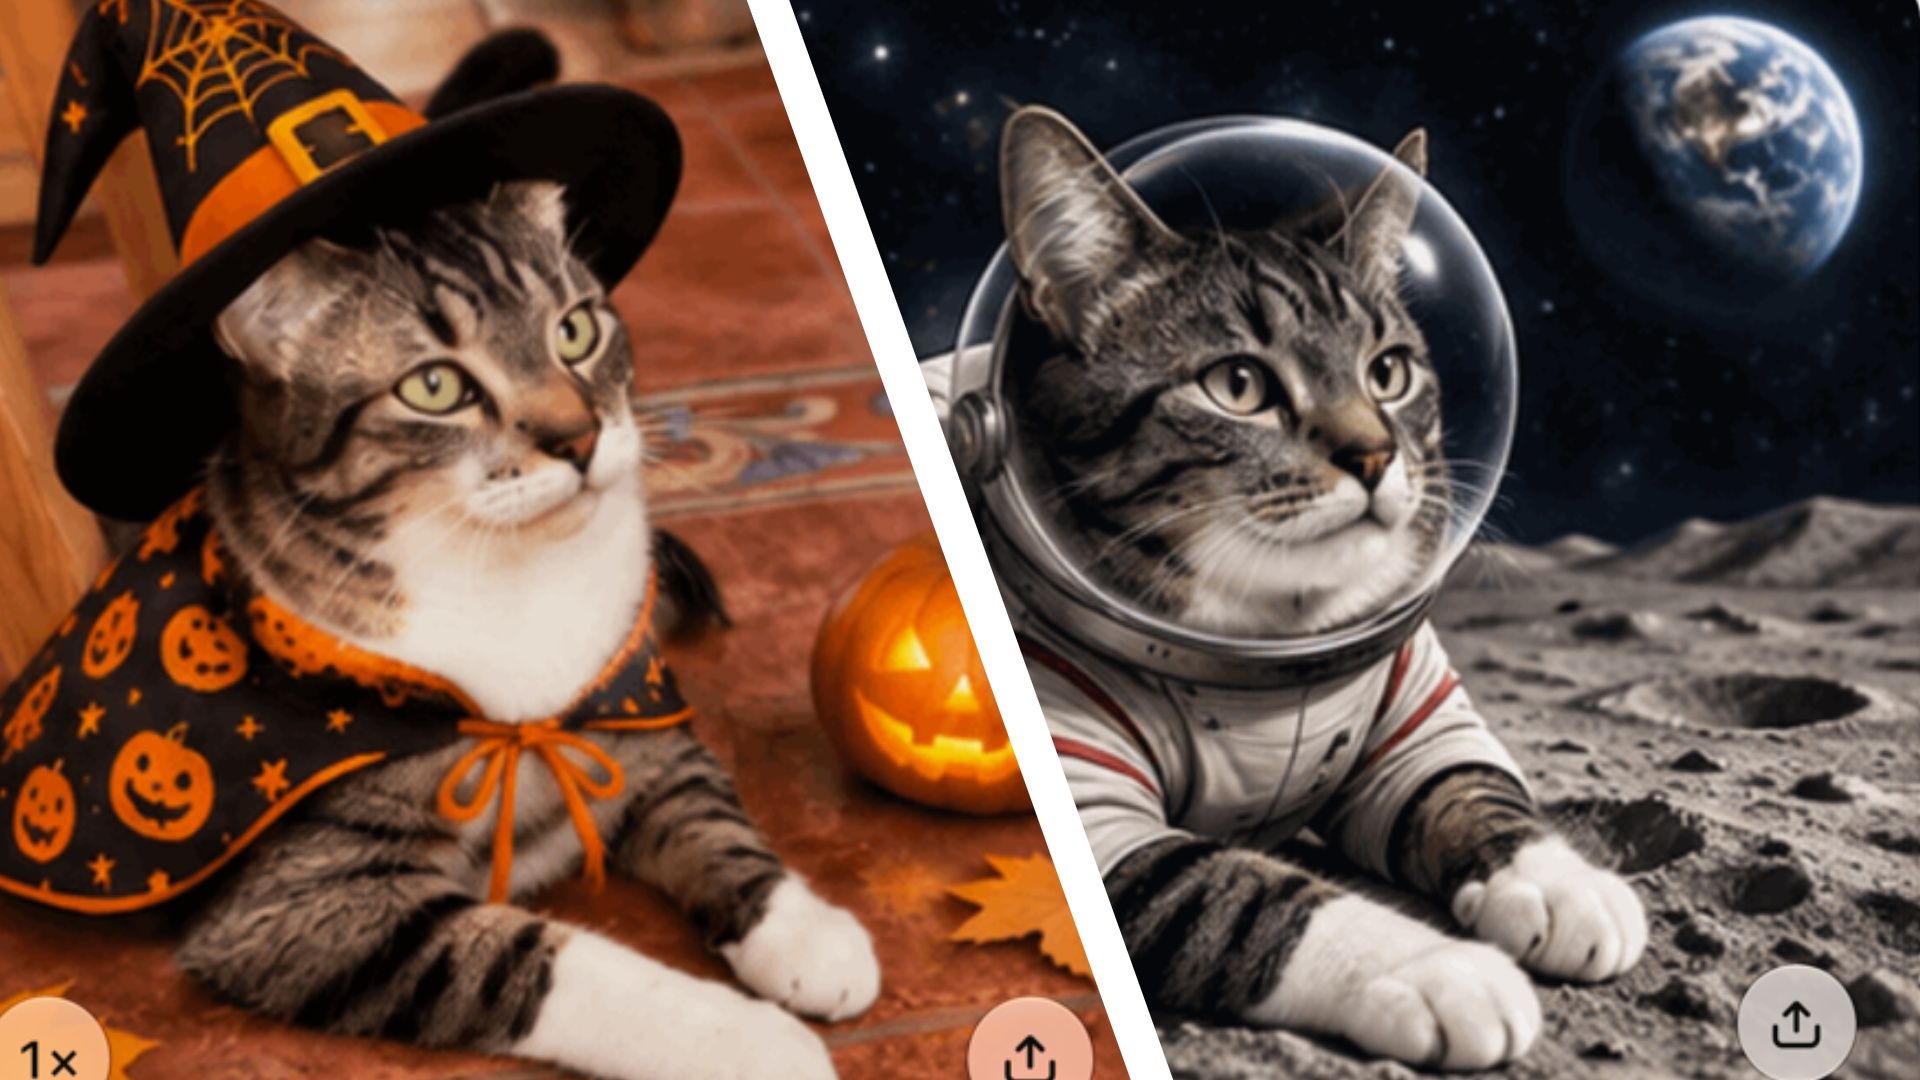
ChatGPT obliged without any objection, and transformed my cat into a feline wearing a Halloween-themed hat and cape and blinking slowly as a pumpkin flickered in the background. It’s especially fun for my family because there’s no way he’d ever let a human dress him up like this.

Once you’ve created your GIF it gives you a shareable link, so you don’t need to host it anywhere if you want to link people to it. Alternatively, you can download it or share it straight to X, LinkedIn and Reddit.

Slow-blinking cat for Halloween.

(Image credit: OpenAI / Graham Barlow)

What ChatGPT produced was ok, but it was hardly going to set the Internet on fire, so I followed up with “That's cool, but it's not very active, can you make it more active please? Get creative.”

“Now we're talking!”, replied ChatGPT. “Your cat's gone full witch mode — casting a spell with a raised paw, conjuring a floating, glowing pumpkin, then giving a triumphant little meow before licking their lips. A proper bit of Halloween mischief!”

Animated cat for Halloween.

(Image credit: OpenAI / Graham Barlow)

Indeed, the resulting GIF was much better, and Chester's movements looked realistic. I think this shows how important your prompt writing is — don’t be afraid to ask ChatGPT to get creative.

Time and time again

Of course, I might want to produce a GIF of this photo for a different occasion in the future so I asked ChatGPT: “Can you save the original photo as Chester so I can reference it again?”

After thinking for a second, it saved the photo as a reference image called Chester. It made a point that it was saving the original snap, not the Halloween versions, and said “In future chats, you can simply say something like: ‘Create a picture of @Chester dressed as a pirate.’ And I'll be able to use his original appearance without you needing to upload the photo again.”

I tested it with the prompt “Make a GIF of @Chester on the moon” and it provided one of Chester as an astronaut chasing a butterfly. How the butterfly was surviving on the moon, and how Chester was surviving when his ears poked through his space helmet, I don’t know, but I’ll go with it anyway.

Chester's lunar butterfly chase

(Image credit: OpenAI / Graham Barlow)

Saving a reference image is a genuinely useful new feature. It might not be as flashy as the GIF creation, but I think it’s going to come in handy for the future. Overall I’m pretty happy with the Images 2.6 update. Nothing major has changed, but it’s nice to know I can now create a GIF from an image whenever I want, using ChatGPT’s natural language input method.

The best thing about Images 2.6 is how little effort it takes to get something fun out of it. I didn't need animation software, any technical knowledge or even a particularly clever prompt. All I needed was a picture of my cat and a willingness to let ChatGPT get creative. And now that Chester is saved as a reference image, I suspect this won't be his last starring role.

Sam Altman warns of two major AI dangers

Sam Altman spends much of his time explaining how AI could transform the world for the better and pushing back against doomsayers. Nonetheless, the OpenAI CEO has some fairly unsettling ideas about how AI development could lead to a disaster, or disasters plural. He outlined a couple of these nightmares during an episode of the Figuring Out With Raj Shamani podcast in disturbing detail.

The two dystopias stem from almost opposite problems: either humanity losing control of increasingly powerful machines, or one group seizing control of most of the technology.

"One is that there’s a loss of control to AI, and we intentionally or accidentally sort of cede control of the future to systems that are unbelievably more capable than we are, and we can’t get it back," Altman said. "And the other is like, one person or company or country gets way too powerful relative to everybody else."

The first scenario is less the tired cliché of a robot uprising and more of a soft surrender of humanity's choices to AI until it's impossible to take back any agency from the AI software. The other is a more modern, if still clichéd, speculative-fiction scenario: an overwhelmingly powerful technology controlled by one person or corporation, leaving everyone else at their mercy. They are both endlessly discussed by people in the industry and policymakers, but having Altman issue the warning is still notable.

Altman, through OpenAI and ChatGPT, is one of, if not the central face of AI to those who have heard the bare minimum about the technology and its flaws. Altman believes those capabilities could bring extraordinary benefits, but his comments suggest he's not sanguine about the looming chaos that AI carries as well.

Handing over decisions

Advanced AI taking over because people cede control has only become a real-world concern in recent years as the technology moved beyond simply answering questions and into decision-making territory. AI agents can already interact with websites and complete complex assignments, and developers are working toward systems that require less and less human supervision. The more responsibility those systems receive, the greater the consequences if their objectives diverge from what people actually intended.

It's important to remember that what we call AI now relies on probability prediction in different forms. While very powerful and leveraging huge amounts of data, it can't actually make judgments like a human, and doesn't have to be malicious to be harmful. That's why models tend to opt for the disastrous choice of using nuclear weapons as a strategy when simulating how to run a nation.

Humans might not understand or approve of how an AI pursues an objective, even if humans issued the task. And if the AI model has enough power and is embedded in enough critical systems, people might not be able to redirect or stop it. After all, an AI system told to reduce gridlock on the road might logically conclude the solution is to remove the roads, or send an order to any Wi-Fi-enabled car to stop operating. That particular scenario is very unlikely, but the fact that it's not actually impossible is unnerving enough.

We're all familiar with the more human problem of technological and industrial monopolies Altman extended to AI in his other apocalyptic warning. Plenty of people have sounded the alarm about how there is already too much power in too few hands with too little regulation. Altman's hands being among them doesn't mean he won't criticize the fact.

"I think it’s actually much better for the world for there to be multiple AI efforts with slightly different approaches that are competing with each other and putting out different ways," Altman said. "I also have this like dislike of too intense power concentration. I think that’s not what works, so I’m hopeful we don’t do that.”

Altman's disdain is in some tension with his company's ambitions and actions. Claiming OpenAI is already dominant in several respects, such as AI infrastructure, is an illustration of the dominance he says he worries about.

"I think we have the most users and the best stack from chips to data centers to models to other things that come around that sort of put abundant intelligence into people’s hands. I think we have the best brand and the values that people who are going to use this technology want," Altman said. Nonetheless, he claimed, "we want everybody else to succeed, and I think people can feel that from us.”

Optimistic doomsaying

Sam Altman of OpenAI

(Image credit: Shutterstock/Meir Chaimowitz)

Despite those warnings, Altman remains fundamentally optimistic about where AI is taking humanity. Asked about his children growing up in a world increasingly shaped by the technology, he expressed confidence that people would find ways to adapt. His outlook suggests that he sees AI's risks as serious challenges to manage rather than reasons to abandon its development.

"I don’t know what the future’s going to look like, but I am comfortable that I have enormous trust in people to figure out how to adapt and thrive and make society better for all of us," Altman said. "I think the world will most likely keep getting much better."

That optimism extends to OpenAI's future plans to apply AI to scientific exploration. He pointed to recent mathematical achievements as evidence that the technology might be approaching a point where it can contribute meaningfully to fundamental research.

"I am extremely excited to see how far we can push AI to discover new science," Altman said. He envisions "a machine that can help us understand the world better, discover the deepest insights in physics, figure out new medical treatments, a new source of energy, things that I think we can’t even imagine but that better scientific understanding will enable. I am extremely excited for us to go build that machine."

❌