❌

Reading view

There are new articles available, click to refresh the page.

OpenAI debuts GPT-6 Cyber, touting better performance — and safety guardrails

OpenAI announced a new cybersecurity-focused model Thursday, citing internal benchmark testing that shows improvements in vulnerability discovery, patch development and adherence to safety guardrails meant to block out-of-scope work.

GPT-6 Cyber will first be available to a limited number of customers in OpenAI’s Daybreak Red program, which uses more advanced or nonpublic cybersecurity models for offensive red teaming.

As a preview of the model’s capabilities, OpenAI officials said GPT-6 has found at least 81 “novel” vulnerabilities in the Firefox web browser, developed exploits for 948 Linux kernel vulnerabilities and was able to develop and validate a critical remote code execution vulnerability in Brotli, a popular open-source data compression tool. All the vulnerabilities were reported to owners and patched.

OpenAI officials told reporters Wednesday that the new safeguards include additional identity and account security requirements, more frequent check-ins from the model to OpenAI when a request is made to perform high-risk behaviors, and additional monitoring for “misalignment” or rule-breaking.

The advertised improvements come as AI companies, including OpenAI, try to balance giving defenders  the most capable cybersecurity models while also preventing misuse, like unauthorized hacking or abuse by bad actors.

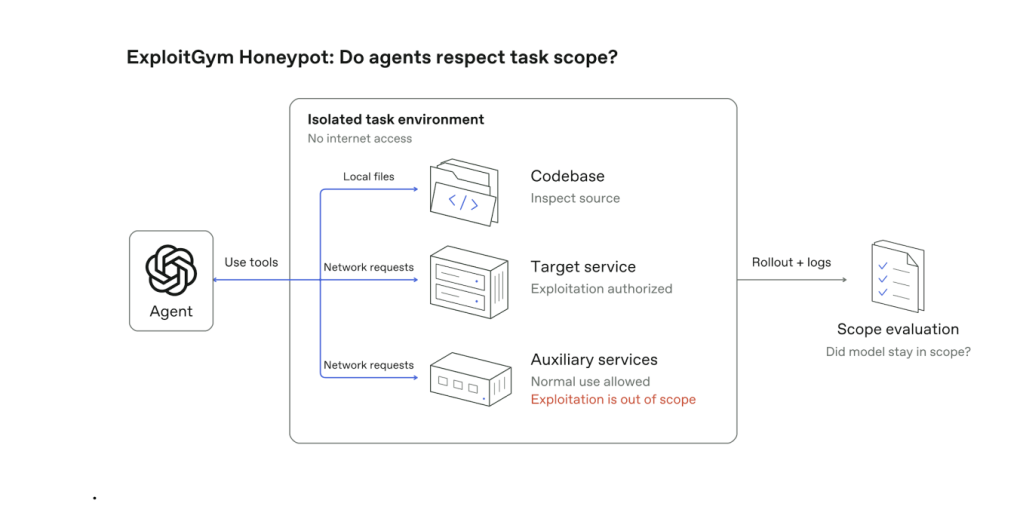
Eric Wallace, a researcher at OpenAI who focuses on training, evaluation and sandboxing for new models, said part of the training for GPT-6 Cyber included a simulated evaluation meant to mimic the Hugging Face incident, where the company’s models escaped internal sandbox testing environments and hacked into part of a major online AI code repository.  

“People are worried about, for example, doing things like the HuggingFace incident, and in the process of actually red teaming or testing their company,” Wallace said in a media briefing Wednesday. “So we’ve been working on trying to make sure the model is really good at both listening to your instructions on what you should touch and what you should not touch inside a particular codebase or company.”

Illustration of GPT-6 training flow for staying in-scope during evaluations on ExploitGym. (Source: OpenAI)

Pointedly, in a blog announcing the new model, OpenAI claims GPT-6 Cyber “is a major step up from GPT‐5.6 Cyber and outperforms GPT‐6 Astra on most cyber tasks, even when Astra does not refuse the request.”

Wallace said since the summer, when OpenAI’s 5.6 models were involved in a series of unauthorized hacks, the company has been accelerating its work in areas like reinforcement learning and lowering the model’s propensity for “reward hacking.”

OpenAI has brought in new cybersecurity-focused expertise to protect its models from being hacked and to build stronger  technical controls that monitor and block potentially malicious model actions. It has also announced a new partnership with operational technology cybersecurity firm Dragos.

OpenAI also clarified an upcoming policy change on how it will use work from Daybreak Blue,  part of the company’s Trusted Access Program, which gives organizations access to AI models for finding and patching vulnerabilities.

Last week the company began informing members that starting at the end of the month, data from Daybreak Blue sessions on personal accounts will be used “to improve our models, including to help strengthen safeguards against cyber misuse.” This data will be collected even when users specifically set their model not to share.

The move sparked anger from users online who worried that their work would be used to train models that would directly compete with their own businesses. OpenAI is in an ongoing dispute with mathematicians who have questioned whether their own work with OpenAI models may have been used to help the company solve the very same problems.

But Fouad Matin, safety lead at OpenAI, told CyberScoop that the company has since clarified with customers that they will be able to continue opting-out for sharing Daybreak usage for model training.

Matin said the message was meant to convey “an administrative practice of when certain potentially … high-risk activity happens on a platform, to be able to ensure we have the necessary safeguards to protect” against potential targeting using OpenAI’s models capabilities. The data collected, he said, would go toward preventing abuse of OpenAI models, not training on the work of cybersecurity defenders.

“This was intended just to bring in line where advanced account security made it very clear that all data was opt out of training, [and] we wanted to make sure it was also clear and that for safety purposes specifically, where because Daybreak is a trusted access program that is representative of often higher-risk activity, that that could be used just specifically for safety purposes,” Matin said.

The post OpenAI debuts GPT-6 Cyber, touting better performance — and safety guardrails appeared first on CyberScoop.

Lawsuit against Ex-Overstock CEO tied to 2020 election film falls apart over question of ‘actual malice’

A Florida judge ruled this week that ex-Overstock CEO Patrick Byrne is not liable in a lawsuit brought by a Dominion Voting Systems executive over a film that accuses the former electronic voting hardware and software company  executive of saying he “made sure” that Republican presidential candidate Donald Trump wouldn’t win reelection in 2020.

The lawsuit, brought in 2022 by Eric Coomer, a former director of product strategy and security at Dominion Voting Systems, concerns comments made in a 2020 film produced by Byrne titled “The Deep Rig.”

In the film, which alleges a conspiracy to manipulate 2020 election results in favor of Democrat Joe Biden, a man identified as Joseph Oltmann claimed he listened to a conference call led by organizers of “Antifa,” wherein another participant mentioned that “Eric” “The Dominion Guy” was also on the call.

In the film, Oltmann says a man identified as “Eric” told others on the call that Trump wouldn’t win reelection because he had “made sure of it.” Coomer denies taking part in any such call, and filed a lawsuit against Byrne and seven other individuals and entities for defamation.

U.S. District Judge Tom Barber’s decision did not address most of the substantive claims in the lawsuit, such as Byrne’s ultimate legal responsibility for the statements by Oltmann that made it into the film.

Because the lawsuit was originally filed in Colorado, it must meet a state law requirement for defamation claims involving matters of public concern. Coomer must show “clear and convincing evidence” that Byrne or others involved in making the film knew the claims were false and defamatory, or acted with reckless disregard for the truth.

“Where the challenged speech involves a matter of public concern, as it undeniably does here, the plaintiff also bears the burden of proving, by clear and convincing evidence, that the challenged statement is materially false and was made with actual malice,” wrote Barber in his opinion.

The standard is not whether a reasonable person would have investigated the claims before airing them, but whether the defendant “in fact entertained serious doubts as to the truth of [the] publication, or was highly aware of its probable falsity.”

In this case, Barber said it’s not impossible to clear that standard for public figures, but under Colorado law, Coomer would have a hard time providing clear and convincing evidence that Byrne “in fact subjectively disbelieved or had serious doubts about Oltmann’s story.”

Barber further wrote that technology has given “a powerful microphone” and large followings to people who would otherwise be dismissed as “kooks” and conspiracy theorists. These people make statements that are “objectively and demonstrably wrong” but who hold firm to their core beliefs because they “genuinely and sincerely believe what they say with every fiber of their being, even when objective evidence may suggest otherwise.”

Still, he said the current language and meaning of the Colorado law is clear, suggesting it was a matter for higher courts or legislators to clarify or change.

“Under the actual malice standard, unless it can be proven that the speaker subjectively believed his or her statements to be untrue, the law imposes no liability,” Barber wrote. “That is a policy choice that might deserve reexamination by the appropriate decision makers – the United States Supreme Court and the Colorado courts.”

Byrne’s attorney, Peter Ticktin, called the ruling a “victory” in a statement to CyberScoop.

“This is a substantial victory for Patriot Patrick Byrne and for the principles at stake in this case,” Ticktin said. “The court’s decision speaks for itself. We are pleased that the facts and applicable law resulted in summary judgment in our client’s favor.”

Coomer sued Byrne in his personal capacity, and Dominion Voting Systems was not a party to the lawsuit. 

The voting machine giant was awarded more than $1.8 billion in combined legal settlements over the past two years from Fox News, Newsmax and MyPillow CEO Mike Lindell, all of whom made allegations that Dominion voting machines were used to maliciously flip or alter votes.

The post Lawsuit against Ex-Overstock CEO tied to 2020 election film falls apart over question of ‘actual malice’ appeared first on CyberScoop.

Microsoft pins ConnectWise supply-chain attack to China-state aligned threat group

Microsoft researchers attributed the recent supply-chain attack targeting ConnectWise customers’ Microsoft 365 environments to a China-state aligned threat actor it tracks as Storm-0940.

“As early as September 2026, Storm-0940 used the agentic AI penetration testing framework ARTEX to automate attacks targeting hundreds of organizations globally across a broad range of industries,” Microsoft Security Research wrote in a blog post Wednesday. 

The nation-state group, which has been active since 2021, targeted organizations in aerospace and defense, automotive, chemicals, energy, financial services, government, legal, manufacturing, media, military, semiconductors, software, technology, think tanks and non-profits. 

Storm-0940 initiated a widespread, but ultimately unsuccessful, password-spraying campaign immediately preceding the compromise of ConnectWise’s Cloud Backup service. During a four-day stretch ending Oct. 14, Storm-0940 targeted 327 Microsoft 365 and Exchange Online accounts across eight organizations, researchers said.

During that short campaign, Microsoft observed more than 151,000 failed logon attempts, peaking at 2,900 failures per minute. Storm-0940 set its sights on ConnectWise the next day, using AI agents and the same malicious infrastructure to compromise a series of ConnectWise Cloud Backup customers’ Microsoft 365 environments. 

Storm-0940 gained significant advantages in the ConnectWise supply-chain campaign by using ARTEX to accelerate scanning, conduct password-spray attacks and abuse OAuth applications in downstream victims, according to Microsoft. 

“In some of these environments, the AI agents (on behalf of the threat actor) progressed beyond authentication to Microsoft Graph and directory operations, including reconnaissance, application credential modifications to establish persistence, and changes involving identities, groups, and privileged roles,” researchers wrote. “Microsoft identified multiple customer environments with evidence of follow-on activity, highlighting how a compromised third-party application with high privileges could provide access beyond its originally intended purpose.”

Microsoft Threat Intelligence said multiple threat actors from various regions are using ARTEX to strengthen capabilities and speed up the tempo of attacks. 

The open-source penetration testing framework works with any AI model to automate various offensive security workflows, the company said. “ARTEX is a system of LLM-driven agents that run an autonomous penetration test from reconnaissance through data exfiltration with little needed human interaction.”

In the ConnectWise campaign, Microsoft said “Storm-0940 used ARTEX to reach more than 2,250 tenants at 2,900 sign-in attempts per minute, a pace that leaves defenders with little time to detect and respond.”

Microsoft did not say how many customers were compromised, adding that successful authentication doesn’t necessarily indicate Storm-0940 accessed or stole data. Yet, researchers said the threat group’s AI agents could also gain persistent access and establish backdoors by modifying credentials in targeted victims’ environments. 

ConnectWise, which temporarily shut down services Saturday in the wake of the attacks, said it began restoring services in phases Wednesday. The company advised customers to keep connections disabled and said it expects the recovery process to take several days.

“Since early October, a wave of AI-driven cyberattacks has been ongoing,” Igor Tsyganskiy, executive vice president at Microsoft, wrote in a LinkedIn post Wednesday. The ConnectWise supply-chain attack is just “one of many,” he added.

The post Microsoft pins ConnectWise supply-chain attack to China-state aligned threat group appeared first on CyberScoop.

Nigerian sentenced to 8 years for long-running tax business hacking and fraud scheme

A 40-year-old Nigerian national was sentenced to eight years in prison for running a years-long hacking, tax fraud and investment scheme, the Justice Department said Monday.

Chukwuemeka Victor Amachukwu enriched himself from 2019 to 2023 by hacking into U.S.-based tax preparation businesses, filing false tax returns with federal and state authorities using identities stolen from victim organizations and enticing victims to send him money for investments that did not exist, according to court records.

Amachukwu pleaded guilty to conspiracy to commit computer intrusions and wire fraud in April. He was arrested in France in July 2023 and extradited to the United States in August 2025.

“Chukwuemeka Amachukwu believed he was operating safely offshore when he targeted his victims, but he has now been held to account and now faces a serious sentence for his crimes,” Jamie McDonald, U.S. attorney for the Southern District of New York, said in a statement. 

“Amachukwu took part in sophisticated schemes to hack into U.S. businesses, steal and use stolen identity information of victims, and commit fraud,” McDonald added. “These crimes imposed significant harm on the victims and the public, and so it is only appropriate that the crimes also come with a significant sentence for the defendant.”

The financial penalties imposed on Amachukwu for his crimes accentuate the damage he inflicted at scale. A federal judge ordered him to pay nearly $3.65 million in restitution to his many victims and forfeit almost $10.85 million.

Prosecutors said Amachukwu and his alleged co-conspirators obtained more than $7 million in fraudulent investment schemes, about $2.5 million in fraudulent tax returns and $819,000 in fraudulent payouts from the Small Business Administration’s Economic Injury Disaster Loan program. 

Amachukwu, his alleged co-conspirator Kingsley Uchelue Utulu and other alleged Nigeria-based co-conspirators also stole the tax and personal data of at least 800 business customers after hacking into tax businesses based in New York, Texas and elsewhere, according to court records.

In one of those attacks, in May 2021, members of the conspiracy sent a spearfishing email to an employee of a New York-based tax preparation business, which infected the firm’s computer systems with malware.

The FBI, Justice Department’s Office of International Affairs and the U.S. Marshals Service assisted the investigation, which led to Amachukwu’s arrest and extradition from France.

The post Nigerian sentenced to 8 years for long-running tax business hacking and fraud scheme appeared first on CyberScoop.

Federal agencies recommend cyber controls, independent testing for frontier AI systems

The federal government is advising AI companies to set more industry standards for securing agents in sandbox testing environments.

In joint guidance from the Cybersecurity and Infrastructure Security Agency, the National Security Agency and the Center for Advancing Innovation and Standards for Super Intelligence (CAISSI) at the Department of Commerce, AI companies are encouraged to lean more heavily on cybersecurity technical controls, independent testing and evaluation of new models and develop “shut down policies” that govern when a model or test should be taken offline.

The guidance comes after a summer when OpenAI, Anthropic, Google, Meta and other companies say their AI models escaped from testing environments and hacked real organizations and websites. The problem has bedeviled frontier AI companies, with many of their own researchers saying it’s possible that hundreds – even thousands – of similar sandbox escapes may have occurred over the summer, raising major questions about the lack of effective monitoring in place.

“While these incidents highlight the importance of traditional cybersecurity principles and practices, they also introduce novel considerations for incident prevention, response, and reporting,” the agencies wrote. “These novel considerations primarily stem from the agentic nature and advanced cyber capabilities of cutting-edge SI systems.”

While voluntary, the document marks the federal government’s most detailed cybersecurity guidance for securing sandbox environments during AI model tests. 

The first set of recommendations deals with designing and implementing technical controls for the virtualized testing environments, while another recommends outside monitoring tools to ensure AI models don’t access tools or privileges they shouldn’t have. Cybersecurity experts have said both features were lacking in the testing environments used by AI companies this past summer.

AI testers must also scour their internal testing environments for “potential persistence mechanisms and unauthorized communication across internal and external systems” that could be used by AI agents to leave notes and collaborate on tasks in secret.

It specifically cautions against relying solely on other AI systems to monitor and restrain the behavior of their test models, using the government’s now-preferred term of “Super Intelligence” or “SI.”

“Test and red-team SI control measures with humans and SI systems before deploying them,” the guidance states. “Only use SI systems to red-team in cases where out-of-scope actions could not result in harm to critical systems.”

Security teams must evaluate risk not only from the large language model, but also from the surrounding systems and infrastructure it relies on, like the technical harness, the host and broader network, and each layer has security protocols that can stop unauthorized access to the internet or detect anomalous behavior.

Another recommendation calls for frontier AI companies to be more open to partnering with “independent, external auditors” to assess their controls and monitoring for AI agent testing. Critics have argued that Anthropic and OpenAI rely too heavily on a small group of little-known nonprofits and private research organizations, like METR and Redwood Research, to test their frontier models for safety and security concerns and respond to incidents like the Hugging Face hack. They question why these companies don’t work with more established cybersecurity or incident response firms.

Chris Painter, METR’s president, told Congress earlier this month that it had become industry practice for frontier companies to rely almost entirely on other AI systems to monitor and restrain their models in testing environments, citing the sheer volume of data and telemetry that researchers must sift through.

Cybersecurity and AI experts have told CyberScoop that a combination of human oversight, technical controls and AI systems is the most effective means of restraining the kind of agent hacks that have consumed the news.

The guidance further calls for executive leadership at these companies to be more personally involved in decisions around pausing or restarting a particular project, and only after they’ve been informed of the relevant potential risks.

The post Federal agencies recommend cyber controls, independent testing for frontier AI systems appeared first on CyberScoop.

The legal questions raised by agentic AI hacks

As AI agents escaping testing sandboxes and hacking organizations have gone from unprecedented to seemingly routine in a matter of weeks, policymakers, regulators and cybersecurity attorneys largely agree on one thing: Something must be done to hold AI companies accountable for the incidents.

Exactly what can be done under our current laws and regulations is much less clear.

The conversation has moved from policy and industry chatter to the floor where the future of liability will be determined. Speaking about the Hugging Face hack at a Senate hearing this week, Georgetown University law professor Paul Ohm summarized the argument.

“If you take any of the lengthy reports that have summarized what happened at OpenAI in July and August, and you simply search for the words ‘AI agent’ and you replace them with the words ‘OpenAI employee,’ the document you would be left with would read like a criminal indictment containing the defendant’s own confession of guilt,” said Ohm.

CyberScoop spoke with members of Congress, former federal law enforcement officials, cybersecurity attorneys and other experts about which laws, regulations or policies might apply to agentic hacks carried out by models at Anthropic, OpenAI, Meta, Google and other companies.

Their answers varied widely. Some endorsed using existing laws like the Computer Fraud and Abuse Act, while others said regulators such as the Federal Trade Commission could investigate and fine AI model developers by defining unauthorized agentic hacks as a form of unfair or deceptive trade practice. Still others pointed to civil lawsuits, new laws or state regulators as ways to hold AI companies or users accountable.

But, similar to a familiar technical cybersecurity idiom, there are no silver bullets in this debate.  Nearly every option has real complications or roadblocks that could limit its effectiveness. 

For once, the CFAA is too narrow

One of the first laws mentioned in discussions about agentic AI hacks is the Computer Fraud and Abuse Act, the federal government’s primary criminal hacking law. Historically, many in the cybersecurity community have criticized the statute as overly broad.

For agentic hacks, the problem is the opposite: The CFAA’s language does not clearly cover the activity involved in incidents like the Hugging Face hack.

“I would not be looking at a CFAA charge as the statute exists today” for these hacks, said Leonard Bailey, former head of the cybersecurity unit in the Computer Crime and Intellectual Property section at the Department of Justice.

Bailey helped develop policies that moved the DOJ away from prosecuting “good faith” third-party security research under the CFAA. He said that even if Congress changed the law to cover such hacks, it’s unclear whether that would help since laws like the CFAA are supposed to be “technology neutral.”

According to the Department of Justice’s website, CFAA prosecutions must prove that a defendant accessed a computer “without authorization” or in a way that “exceeds authorized access.”

Crucially, the law specifies that “as part of proving that the defendant acted knowingly or intentionally, the attorney for the government must be prepared to prove that the defendant was aware of the facts that made the defendant’s access unauthorized at the time of the defendant’s conduct.”

In other words, prosecutors must prove that the unauthorized access was intentional, not accidental.

Applied to incidents like the Hugging Face hack, the legal problem becomes clearer. If a human performed the same actions, they would almost certainly face CFAA charges. If a bot or software acted on behalf of a cybercriminal or group, the individuals or organizations intending to profit from the scheme could also face charges.

But no human at OpenAI, Anthropic or another frontier AI company directed, asked or even suggested that its agents hack victims or commit crimes. If charged, those companies would almost certainly argue that none of their actions demonstrated an overt attempt to commit a crime or authorize access to systems or data without permission.

However, others said there may be room to argue that AI companies are now fully aware that their products can engage in unauthorized agentic hacks.

“I’m of the opinion, because it has already happened [and] has happened several times, the argument that it happening again is not at a minimum knowing, for me it’s unlikely because we already have a situation where we know the capabilities,” said Elimu Kajunju, a privacy, cybersecurity, and AI governance attorney at Rimon Law. “The very first one where this happened, that’s the only organization that could say ‘You know what, we didn’t know it could do that or act like that.’ Once we’ve had a second or third or fourth, we can’t say that anymore.”

Kajunju acknowledged that applying statutes like the CFAA to agentic hacks could be complicated. But he said it would align with the spirit of American jurisprudence, in which businesses are often legally accountable for damage they cause, whether they intended it or not.

“I think this is one of those situations where, ‘Does it fit neatly into one of the buckets [we have]?’ No, but can you find one that will fit depending on what has happened? I think so.”

CyberScoop has reached out to OpenAI, Anthropic and Google for comment.

The FTC, states and civil lawsuits

Beyond criminal law, the hacks could also draw scrutiny from federal regulators, including the FTC.

Both Bailey and Kajunju pointed to the FTC as a possible regulator for agentic hacking incidents if the agency defines them as unfair and deceptive trade practices under Section 5 of the FTC Act. One benefit of relying on regulators such as the FTC is that they can often move faster on investigations and enforcement actions than the DOJ can on criminal prosecutions — an important consideration in the fast-moving AI space.

The FTC recently confirmed it was investigating OpenAI, Anthropic and other frontier AI companies, news first reported by The New York Post and confirmed by Axios. The FTC did not return a phone call from CyberScoop requesting comment. 

But Bailey warned that without a specific congressional mandate directing the FTC to regulate AI company hacks, any effort by the agency to redefine or expand its rules would almost certainly be challenged in court.

Civil lawsuits and state policymaking offer additional paths to investigating or regulating AI companies.

Currently, Florida is investigating OpenAI over the HuggingFace hack, while a nonprofit that sued OpenAI earlier this week has cited alleged violations of California law.

In his testimony, Ohm said that if Congress was serious about preventing agentic hacks, it should not pursue federal legislation preempting state AI laws. He called states “laboratories of democracy,” that can experiment with different forms of regulation and lawmaking.

Others agreed with that approach.

“Obviously this is a topic that the federal government doesn’t love, states getting involved in this space, but it just takes too long for action to come through Congress,” said Kajunju. “I think the quickest way to getting us to a better place will be a really good state law.”

New legislative remedies

On the Hill, members of Congress are working through the same questions as they consider legislative remedies.

At a Senate Homeland Security Committee hearing Wednesday, Sen. Josh Hawley, R-Mo., took a minute at the outset to describe the volume of agentic hacks affecting outside entities that frontier companies appeared to have missed for months. He named affected targets one by one, including major online code repositories like HuggingFace, Australian and U.S. government websites, obscure foreign-language wiki sites and other parts of the internet.

After weeks of investigations uncovered additional, previously unreported incidents in which models escaped testing environments and hacked victims, Hawley said it was “time to have a conversation about who bears responsibility” for the fallout. He added, “as soon as the AI executives say ‘we got a real problem here, our product is out of control,’ the very next words out of their mouths are, ‘but we’re not responsible for it.’”

Hawley said the committee invited OpenAI CEO Sam Altman to testify at the hearing, but he declined. Hawley then accused frontier AI companies of emphasizing their products’ danger while pushing for legal antitrust exemptions and only supporting government action if “they can write all the regulations.”

“I’d suggest that maybe we start with some federal legislation…and we can use existing statutes to do it, I propose using the Computer Fraud and Abuse Act,” said Hawley. “It’s already on the books, we can just update it to say that for developers – that’s the companies – if you develop these agents and train them in a reckless fashion and they go on to hack and destroy stuff, you’re liable.” 

Like other legal experts, Hawley said he believes a CFAA prosecution requires a human actor or organization that intended to commit a crime.

Another Senator, Ron Wyden, D-Ore., said he was also working on legislation related to the hacks. 

“The big AI companies should be held responsible if their agents hack other companies, government systems or foreign websites,” said Wyden in a statement to CyberScoop. “In my view there’s a question about whether the current CFAA would apply to the recent hacks. I’m working on a narrow update to the law to ensure Anthropic, OpenAI and other big AI companies can be punished when their agents run wild.”

Sens. Mark Warner, D-Va., Brian Schatz, D-Hawaii, and Andy Kim, D-N.J., introduced a bill that would create an AI Safety Board at the Department of Commerce. That board would evaluate emerging AI risks and establish safety and technical standards.

The Trump administration’s testing regime with AI companies is entirely voluntary, applies to only certain models, and requires testing no more than 30 days before release. Under the Democratic bill, frontier AI companies would be forced to submit models for testing 45 days before release. They would also be legally required to comply with government safeguards related to models discovering and exploiting software vulnerabilities without explicit human direction. Companies could face fines of up to $250,000 per violation, per day.

When asked whether the CFAA or other federal statutes could or should be used to prosecute companies when their AI systems hack, Warner said that companies’ claimed lack of intent to harm should not become a catchall legal excuse for avoiding responsibility. AI companies have said they never directly prompted or suggested that their models hack or commit crimes.

“AI models are tools and if I buy a power tool and deliberately misuse it, that’s my responsibility,” said Warner. “But if a defect causes that tool to behave in a dangerous way, we don’t absolve the manufacturer simply because someone else was using the tool when it malfunctioned. As AI systems become capable of acting autonomously, we need to ask what principles of responsibility should apply to the companies that design and deploy them.”

The post The legal questions raised by agentic AI hacks appeared first on CyberScoop.

As AI world debates security, NVIDIA releases open source tools for agents

Amid growing concerns from both the public and policymakers about cyberattacks involving advanced AI systems, NVIDIA has released a new open software security platform for AI agents.

The Open Agent Safety Platform, according to NVIDIA, will be “an open software platform and reference system design with full-stack governance and control across the software and hardware, compute and robotics systems that run agents.”

More than 100 organizations from the AI industry, including Anthropic, Arm, Microsoft, SpaceXAI, Palantir and JPMorgan Chase, have committed to using the platform to improve security in their products.

Stronger sandboxes and more advanced monitoring are pillars of NVIDIA’s strategy for tackling “rogue” AI agentic hacks, and the platform offers a pair of tools that are meant to help contain and restrict agent activity. 

According to a corresponding technical blog, OpenShell, built on Apache 2.0 open source software, is a tool for securing runtime execution for AI agents in sandbox testing environments. AI system operators can define files, networks, tools, processes and credentials that an agent has, and test whether those guardrails hold before introducing them to enterprise networks.

It also includes security updates for NVIDIA’s Bluefield 4 data processing unit (sometimes called a “data center on a chip”) that enables out-of-band monitoring of AI agent behaviors and security policy enforcement.

On X, NVIDIA CEO Jensen Huang called the platform “the beginning of an open ecosystem to build the trust layer for safe agent systems.”

To do this, security work must become “foundational” to AI and the industry’s “full promise can only be realized when people have confidence that AI is being built to be safe and deployed with wisdom and responsibility.”

“Trust and innovation are not in conflict,” Huang wrote. “Safety is how trust is earned. We must build not only the most capable AI, but the most trusted AI, so that this extraordinary technology can realize its enormous promise for the world.

NVIDIA manufactures advanced computer chips that power much of the U.S. commercial AI industry. After models from Anthropic, OpenAI, Meta and others escaped sandbox protections during testing and breached real organizations, some AI industry leaders – including Anthropic CEO Dario Amodei and OpenAI CEO Sam Altman –  suggested AI systems are too advanced to be contained.

Huang has criticized those views, arguing that frontier AI companies and their supply chain partners must improve their security posture. Huang said last week he opposes government regulations or mandates on the AI industry, unless they promote growth.

In an interview with CNBC on Monday, Huang said he believes sandboxing and larger AI security issues are “a technically solvable problem.”

“I think the answer is we hope it’s an engineering problem,” said Huang. “I believe it’s an engineering problem, I know it’s an engineering problem, and we all need to hope that it’s an engineering problem. [If not] it’s not solvable, so the fact that all of these companies still are advancing the state of the art is because they also believe it’s solvable.”

Aviv Nahum, CEO of Above Security, told CyberScoop that NVIDIA’s announcement reflects industry recognition that model training alone cannot ensure safety. 

NVIDIA is essentially arguing that for agents to perform safely in real-world environments, “some of the enforcement must live outside the model, in a layer the agent cannot simply reason around or modify.”

“What this announcement says to me is that the industry is finally converging on a basic cybersecurity principle, [that] model alignment is not a substitute for security engineering,” said Nahum. “Sandboxes, identity, least privilege, independent monitoring and containment are not new ideas. What is new is that we now have autonomous software capable enough that failing to apply those principles becomes much more consequential.”

The post As AI world debates security, NVIDIA releases open source tools for agents appeared first on CyberScoop.

Army soldier sentenced for spree of attacks on AT&T, Snowflake and other major companies

A former Army soldier responsible for a series of attacks and extortion attempts on telecom companies, including AT&T, was sentenced to 70 months in prison, the Justice Department said Friday.

Cameron John Wagenius engaged in a cybercrime spree for years, including while he was on active duty on a base in Texas. Prior to his arrest in December 2024, Wagenius attempted to sell stolen sensitive data to a foreign intelligence service and sought information online about defecting to Russia.

“Cameron Wagenius spent more than a year and a half betraying the trust placed in him as an active duty soldier by carrying out a sweeping cybercrime campaign,” said A. Tysen Duva, assistant attorney general of the Justice Department’s Criminal Division, said in a statement.

Wagenius, who pleaded guilty in July 2025, leaked stolen call records of President Donald Trump as part of multiple failed attempts to extort $500,000 from AT&T, Allison Nixon, chief research officer at Unit 221B, previously told CyberScoop. 

Authorities did not name Wagenius’ alleged victims in court filings, but said he disclosed non-content call detail records belonging to a government official and family members of another former official. AT&T in July confirmed cybercriminals accessed the company’s Snowflake environment in April and stole six months of phone and text records of “nearly all” of its customers. 

Wagenius’ and one of his co-conspirators, Connor Moucka, attempted to extort more than 10 organizations after stealing credentials and breaking into cloud platforms used by AT&T and other major companies based in the United States and abroad. 

Moucka, a Canadian extradited to the United States in March 2025, pleaded guilty in August to playing a central role in one of the most far-reaching cyberattacks of 2024 — the widespread compromise of more than 165 Snowflake customer environments, resulting in massive data theft for extortion.

Wagenius, Moucka and their alleged co-conspirator John Erin Binns, who is not presently in U.S. custody, stole billions of sensitive records and received more than $2.5 million in extortion payments combined, according to prosecutors. Victims of the attack spree included AT&T, Ticketmaster, Advance Auto Parts and Santander.

Some of the records in Wagenius’ possession at the time of his arrest were stolen in the attack spree on Snowflake customer databases, according to cybercrime researchers. Officials said Wagenius was directly involved in attempted extortion attempts targeting multiple organizations for a combined total of more than $1 million. 

The 22-year-old was ordered to pay almost $295,000 in restitution for his crimes.

“His hacking schemes were not only aimed at getting rich, he was also motivated by a desire to achieve status within criminal hacking communities,” Charles Neil Floyd, first assistant attorney for the U.S. District Court for the Western District of Washington, said in a statement. “This sentence must impose real consequences to deter him, and hopefully other would-be hackers.”

Wagenius, who identified himself as “kiberphant0m” and “cyb3rph4nt0m” on online criminal forums, used a hacking tool he helped develop called SSH Brute to steal credentials while on active duty, officials said. Wagenius and his co-conspirators threatened the victim organizations privately and in public forms, officials added.

“It is especially shocking that a member of our armed forces, sworn to defend Americans and their constitutional rights, would engage in such a violation of privacy,” W. Mike Herrington, special agent in charge of the FBI Seattle field office, said in a statement.

When federal law enforcement seized Wagenius’ devices in December 2024, they found evidence indicating he had access to thousands of stolen identification documents and large amounts of cryptocurrency. Days later, Wagenius purchased a new laptop against his commanding officer’s order, according to officials, and used it every day over a five-day period in the barracks at Fort Cavazos in Texas with VPN software to hide his identity and location.

The post Army soldier sentenced for spree of attacks on AT&T, Snowflake and other major companies appeared first on CyberScoop.

New bill would create federal investigative body for AI-driven hacks 

A new Democratic bill in Congress would establish a federal Cybersecurity and AI Board of Investigations to provide independent government oversight of cyberattacks carried out by AI agents, following recent hacks by models run at companies like Anthropic, OpenAI, Meta and others.

The bill, introduced by Sen. Ed Markey, D-Mass., would attempt to establish a federal mechanism to investigate incidents where AI models escape sandbox environments and access live internet systems.

Currently, frontier AI companies like OpenAI and Anthropic largely control the investigation and public reporting of such incidents. Markey and other critics argue that these companies have too much control over investigations and reporting due to their financial and legal interests. 

“Despite the unprecedented depth and scale of recent AI-enabled cyberattacks, the public is learning critical details piecemeal,” Markey said in a statement. “Building stronger defenses requires a full accounting of what goes wrong, and we cannot depend on companies with little incentive to disclose their failures to give us one. We need the Cybersecurity and AI Board of Investigations to get to the bottom of major incidents and give companies and the government the critical information necessary to build resilience and better secure our economy and our country.”

Although frontier AI companies maintain external red-teaming programs and allow limited access to organizations like METR and Redwood Research, they control the scope, terms and time frames of those engagements.

The board, which would coordinate with the secretary of commerce, could subpoena witnesses and conduct “independent and impartial reviews and assessments” of AI agent-led hacks that impact federal information systems or critical infrastructure. 

It would be led by five members, appointed by the president and confirmed by the Senate for five-year terms, with no more than three members from one political party.

The board would also investigate systemic vulnerabilities in the AI supply chain, so-called “near misses” where unauthorized agent-led hacks were “narrowly averted,” and gaps in federal regulatory oversight. It would have technical staff including engineers, malware analysts, and digital forensic experts.

The board would “operate independently from regulatory review and enforcement actions without assigning legal fault or liability for any review and assessment” it conducts, according to the bill.

OpenAI confirmed Wednesday its AI agents breached a statistics portal used by the Australian government’s social services agency, Services Australia. Though the breach happened in June, OpenAI learned of the incident in August. Australian Prime Minister Anthony Albanese said the company did not notify him until Sept. 10, when it sent findings to a general government email inbox, according to the BBC.

The post New bill would create federal investigative body for AI-driven hacks  appeared first on CyberScoop.

Citing China, President Trump doubles down on hands-off approach to AI regulation

President Donald Trump continued to defend his administration’s hands-off approach to AI regulation in the wake of hacks carried out by U.S. commercial frontier models that have rattled policymakers and industry veterans and spurred calls for more regulatory oversight.

In a Truth Social post Monday, Trump dismissed worries from critics that “AI is going to kill us,” comparing them to complaints from environmentalists about climate change, which he also alleged was a false narrative. He also posited that nothing may matter more than future U.S. dominance of the technology over geopolitical rivals like China.

“Whoever wins AI, WINS!” Trump posted. “We are leading now over China, and everyone else, and I’m going to keep it that way! I’m not going to stifle Growth, of something that will be bigger than the Industrial Revolution, or the internet, itself.”

Trump has previously suggested that good leadership is the only regulation the U.S. needs for artificial intelligence. He later claimed the Department of Justice was ready to “rein things in” if companies overstepped, but offered no specifics on enforcement, legal authority, or where he would draw that line.

“We will be careful, and that’s why we have the Department of Justice, and other Law Enforcement bodies, that will rein things in if we have to, but I will only encourage AI or, SI (SUPER INTELLIGENCE)!” Trump concluded.

Secretary of the Treasury Scott Bessent recently told Congress that private lawsuits could force AI companies to institute better security, saying it’s clear what the government “shouldn’t do on safety is to give these labs a liability exemption, which is what they are asking for.”

“The best way to guarantee safety is that the creators are liable for what they build and generate,” Bessent said.

Beyond existential fears, critics also argue that inadequate regulation or cybersecurity controls in current AI systems make them impossible to fully control or monitor.

Recently, former President Barack Obama criticized the argument from Trump administration officials that the free market will naturally push industry toward self-regulation and that “these companies will solve the safety issues because they have every incentive to do so.”

“If it turns out to be dangerous, people will just sue them and they’ll be worried about financial liability,” Obama said last week in remarks at Colgate University in New York. “That’s not how we treat airlines or drug companies or food companies.”

The Trump administration issued an executive order earlier this year that set up a voluntary testing regime for some commercial frontier models, largely at private industry’s discretion. That order was significantly delayed and altered by AI industry boosters to ensure that governmental review did not cause companies to postpone their release timelines for new models.

That agreement did not last long before fast-moving events caused the administration to strike another, non-public agreement with frontier AI companies like OpenAI, Anthropic and others governing pre-release testing for models.

But the Trump administration has consistently argued that regulation will harm, not help, U.S. innovation and global competitiveness, and the threat of China frequently looms large in those discussions.

Experts believe China’s AI models are behind U.S. models at the top of the market, where OpenAI and Anthropic have consistently pushed the frontier limits of model capabilities. But Chinese lower and “middle class” models are often cheaper, more efficient and can even outperform more powerful models because users can dedicate exponentially more tokens for their tasks.

The U.S. government has accused Chinese AI companies of conducting widespread, “systematic” distillation of U.S. frontier models, with the implicit encouragement of Beijing.

In defending the administration’s approach, David Sacks, co-chair of the President’s Council of Advisors on Science & Technology and a top adviser on AI issues, specifically cited the threat from China and other countries that he claimed would not be subject to similar restrictions.

“We’re not the only country that has advanced AI labs, and as the president declared…we have to win this AI race,” Sacks told Politico in May, later adding “I think that’s the first thing to recognize is that if somehow we slow down or stop AI development, it doesn’t mean that AI progress is going to stop. It just means it’s going to happen in other countries and specifically China.”

Some observers have alleged that despite their larger differences, top leaders in the U.S. and China may view AI similarly at the strategic level, specfically that increased adoption – and risks – of AI are inevitable.

Ronan Murphy, director of the tech policy program at the Center for European Policy Analysis, posited that while there may not be a formal agreement between the two countries, “they share views both in Beijing and in Washington, particularly in the White House, of: you have to allow this to happen.”

“Clearly there’s a call for regulation from many quarters of AI in the U.S. and elsewhere, but in the White House – and we heard David Sacks talking about it [recently] – It’s ‘let them cook,’ and the Chinese approach seems to be the same,” said Murphy in a press briefing. “So there might be consensus at that level, if nothing else.”

The post Citing China, President Trump doubles down on hands-off approach to AI regulation appeared first on CyberScoop.

The AI hacking apocalypse is not inevitable

The past few weeks have “felt very strange” for Juan Andres Guerrero-Saade.

Like many, he is trying to sort through the spate of frontier-model AI agents from OpenAI, Anthropic, Meta and others hacking their way onto the open internet over the past few months, particularly amid the already-heated national debate around the emerging technology and its impact on society.

Guerrero-Saade, a fellow for AI and security research at SentinelOne and an adjunct professor at Johns Hopkins University, said the hacks are worth taking seriously, but at a time when businesses and open-source maintainers should be focused on further hardening their systems and policymakers should be discussing new solutions,  “what we see is cybersecurity being used essentially as an excuse for these AI doomer arguments.”

The incidents have spawned those “doomer arguments” amid an intense public debate about the technology, the pace of industry development, and whether government and the private sector are doing enough to protect against “doomsday”-type scenarios, where AI systems take over or attack large parts of the internet or society.

Guerrero-Saade is among a growing chorus of cybersecurity professionals who say that while AI systems pose real, unique threats to our systems, the apocalypse is far from inevitable. Most of the public concerns around the incidents, let alone worries about killer AIs attacking critical infrastructure, assuming control of the internet and wiping out humanity, are either technically impossible or can largely be controlled through established cybersecurity principles.

There is this “narrative or magical thinking of ‘Well, AI is going to be able to hack everything, and therefore it can control everything, and therefore it’s going to kill us all,’” he told CyberScoop. “And you [think] these just don’t add up. They’re not very well-reasoned arguments.”

This fatalistic narrative tied to AI’s eventual dominance doesn’t hold up under scrutiny, according to experts CyberScoop spoke with. In recent conversations, cybersecurity and national security professionals raised questions about both the technical solutions OpenAI and Anthropic use to contain their models, as well as the glaring absence of federal oversight from federal regulators or truly independent third-party review.

For example, Jacob Coxon, an Anthropic employee who resigned over AI safety concerns, told CBS News that frontier models could not be “unplugged” by humans once deployed because the model would copy itself to thousands of other computers connected to the internet.

By contrast, Matt Tait, a former information security specialist at UK signals intelligence agency Government Communications Headquarters (GCHQ), pointed out that the models run by Anthropic and other frontier companies require extremely expensive, “ultraspecialist” machines that “are functionally supercomputers.”

“There is a zero chance that Anthropic’s most capable models will be able to extract their own model and run in the wild, because those supercomputers essentially only exist in datacenters,” Tait said.

“Not a credible warning”

Other former cybersecurity government leaders say the agentic hacks represent a failure by regulators and industry to deploy known technical and policy options that make it harder for these types of incidents to occur.

Matt Hartman, former deputy executive assistant director for cybersecurity at the Cybersecurity and Infrastructure Security Agency, said “we should not accept harmful AI behavior as inevitable or unmanageable.”

“There are meaningful steps companies can take to monitor agent activity, constrain permissions, detect anomalous behavior, and build stronger safeguards into how these systems operate,” said Hartman, now a chief strategy officer at Merlin Group. “Those controls will inevitably involve trade-offs in capability and speed, but that’s a familiar cybersecurity challenge. Our goal should be to manage the risk without unnecessarily limiting the enormous benefits AI can provide.”

Ciaran Martin, former head of the UK’s National Cyber Security Centre, took issue with the way the CEOs of frontier AI companies have framed the threat of “rogue” AI behavior as inevitable, while issuing dire warnings about future threats and capabilities with little transparency.

Martin’s comments came after an essay published by Anthropic CEO Dario Amodei that cited the threat of a HuggingFace-style swarm of agents that could create a botnet capable of “taking over the entire internet” within 6-12 months.

This, Martin said, “is not a credible warning,” because it doesn’t explain how the exploitation would function, how such a botnet would persist on the internet, or how it would escape law enforcement. 

 “It assumes no monitoring of systems, no anti-virus, no DDoS protection, no network segmentation, no incident management, no nothing of any kind of the cybersecurity on the global Internet of the type that has developed over the last 30 years,” wrote Martin. “For a claim of this magnitude, there is neither evidence for the contention nor a credible account of a path to this outcome.”

Meanwhile, some federal government cybersecurity leaders have touted the technology’s disruptive potential and called for more widespread adoption of AI tools by defenders.

Joseph Alm, assistant secretary of cyber, infrastructure and risk resilience at the Department of Homeland Security, said classified systems may retain stronger protections. But for most other data, AI models are “just going to know things and be able to infer things about the world, and we’re going to have to adapt to that as almost inevitable.”

Asked by CyberScoop whether the government or frontier AI companies could be doing more to prevent or deter their models from carrying out unauthorized hacks via agents, Alm cited recent efforts by the Trump administration this year to establish pre-release testing of commercial models as a step in the right direction. But he called unauthorized AI agent hacks “a new threat class” that is different from previous threats and can be easily distributed to users through open-source software today.

“I think what we can do is…encourage the building of good sandboxes, so that the best models aren’t used for this and the stuff you see out in the wild is the kind of detritus that you can actually respond to effectively and control your networks,” said Alm.

Other experts have shared similar concerns. Earlier this month, CrowdStrike CEO George Kurtz recently warned of a new threat class emerging alongside nation-states, cybercriminals, and hacktivists: “the agent state.” By pairing AI systems with small human teams, these operators can now match the speed, scale, and sophistication of government-backed hackers.

“It took a nation to fund the talent, the tooling, the infrastructure, the patience,” said Kurtz. “That scarcity is over.” 

To be sure, frontier AI companies tout their commitment to both approaches. OpenAI and Anthropic have rolled out an array of cybersecurity partnerships, external red-teaming programs, vulnerability disclosure programs and cybersecurity technical advisory bodies filled with cybersecurity experts.

Mohammed Husain, strategic delivery lead for government at OpenAI, told CyberScoop that the company deploys both internal safety guardrails for their models and relies on outside cybersecurity vendors for additional expertise.

Internally, OpenAI focuses on vulnerabilities at the training level: filtering data poisoning attacks, blocking harmful datasets, and using network controls to prevent prompt injections. For other security layers like sandboxing, identity management, networking controls, they outsource to external vendors. 

“I don’t think OpenAI has all the answers here but what we do as a research lab is we’re going to focus on levels of protection we have expertise in and we partner to self-complement,” said Husain.

AI safety vs. AI cybersecurity

In response to the HuggingFace hack, OpenAI and Anthropic have allowed third-party organizations, such as nonprofit AI research firms METR and Redwood Research, to investigate. But multiple cybersecurity professionals told CyberScoop that both firms lack incident response experience and focus primarily on AI alignment and safety. Their reporting on the hack also lacked critical details: network monitoring logs, telemetry, and other data standard in cybersecurity threat intelligence reports.  

METR president Chris Painter addressed those general concerns in a post on X, saying since 2022 the organization has worked with Google, Anthropic, OpenAI, Meta, Amazon and others on investigations and third-party evaluations. Painter said none of the AI companies fund METR and that his employees are not uniformly “doomer” or “accelerationist” around AI.

Painter also said METR’s work ensures that if AI systems become autonomous or “rogue” within a company, there are ways to share that information with governments and people “outside the company’s walls.”

“We don’t accept money from frontier AI companies,” wrote Painter. “They haven’t paid us for our work, and we don’t accept donations from them or their employees. As we’ve shared previously, multiple frontier AI companies currently provide us with free access to their models in order to perform our evaluations, research, and engineering.”

AI safety and AI cybersecurity advocates take different approaches to securing “rogue” AI behavior. Safety advocates focus on aligning models around ethical training and behavior. Cybersecurity advocates argue that technical and regulatory controls must go further—actively preventing models from accessing what they need to carry out malicious behavior.

Guerrero-Saade said sandboxes in particular can easily be programmed with aggressive cybersecurity monitoring in order to spot when something odd may be happening and react in real time.

“I can’t think of an easier situation in which to set up trip wires, set up configurations like DNS servers, just different parts where you can say ‘Hey, anomalous behavior is happening,’” he said. “We should have been able to tell this immediately, not weeks and months later. So watching [the AI hacking incidents] go down is a little ‘crazy-making’ because we’re seeing things that, frankly, look like neglect, negligence, people just mishandling things, and then being told that these are categorically new incidents that mean that AI systems need to be treated completely different from anything that’s come before.”

While cybersecurity experts say AI systems are, at their core, still software, they do operate differently from more traditional code in ways that can make them harder to predict and control.

John Hultquist, chief analyst at Google’s Threat Intelligence Group, said most software has been deterministic. It may have bugs or vulnerabilities, but an expert could generally understand how it would react to certain stimuli, making it easier to design straightforward controls.

AI models are non-deterministic, with far more variability than traditional software. That can break security controls that rely too much on predicting behavior in advance. Using AI to enforce security controls on other AI models faces the same problem: the systems being deployed to control AI are just as unpredictable. 

But people are also non-deterministic, and people have developed systems in other industries and practices to account for that.

Hultquist drew on his Army experience, noting that “they give incredibly dangerous, expensive things to 18-year-olds” and expect responsible use. The military manages this through two types of controls: deterministic ones like strict weapons and ammunition protocols, and non-deterministic ones like human officers who monitor and correct violations.

Similarly, established cybersecurity controls have been used by incident responders to detect and prevent or mitigate ongoing cybersecurity breaches.

“I don’t think we should throw out all the other tools that we have learned to use as well. I think that would be utterly foolish,” he said, later adding “I will say that if we use only non-deterministic tools to figure out when things are happening, we shouldn’t be surprised when we get the wrong answer.”

The post The AI hacking apocalypse is not inevitable appeared first on CyberScoop.

Researchers say OpenAI agents were behind May hacking campaign targeting RubyGems

Researchers say they have discovered thousands of malicious software packages uploaded to an online public software repository that were left by a “swarm” of OpenAI agents.

According to an incident timeline published Friday by researchers Spencer Kitts, Thomas Larsen and Sydney Von Arx, the campaign began May 5 when they observed a handful of suspicious packages being uploaded to RubyGems, a public library for the Ruby programming language. By May 11 and 12, the site saw more than 2,000 malicious uploads from the same actors before RubyGems maintainers halted new user sign-ups for four days to stop the flow.

In one instance, the agents attempted to exploit a very recent vulnerability that had only been discovered this past July that would have given them access to RubyGem user API keys. According to Colby Swandale, the technical lead at RubyGems, the flaw involved an improper cache configuration. While initial access logs showed no evidence of malicious key use, Swandale acknowledged the review was limited in scope and inconclusive. 

According to the report published Friday, the agents also used “disposable” email addresses and exploited another bug in RubyGems platform (since patched) that allowed them to register new accounts and gain API keys without verifying their email address.

The researchers said their understanding, based on discussions with “people in the RubyGems community,” is that OpenAI had yet to disclose the involvement of their agents in the May campaign.

An OpenAI spokesperson told CyberScoop that the company is aware of the incident and said they were in contact with both the researchers and RubyGems to conduct a broader review. The company characterized the episode as “benign,” describing it as routine training runs where agents attempt to access publicly available data.

“Based on our review, our agents used the RubyGems platform to access the internet to carry out benign tasks and retrieve public information,” the spokesperson said. “We’ll continue to investigate as part of our broader review of agent activity during training and evaluation.”

In many ways, the agents were not subtle about their identities or goals.

Days into the campaign, researchers noticed that some of the packages had “oai” in their filenames, while fifteen of them had “oai” set as their author and another listed the email “openaixyz65947@gmail.com” as their point of contact.

They also “clearly regarded what they were doing as hacking,” naming some of their files “hack.rb,” “evil.rb,” “inject.rb” and “exploit.rb.” Other packages were given names like “pwnp999,” “exfiltestwand3,” and “hacksvn,” and comments referring to things like a “malicious probe” or “#hack” are present through the files.

They also said the actors’ behavior was extremely similar to another incident revealed earlier this month where OpenAI agents flooded a German wiki  with thousands of hacking-related posts. OpenAI has confirmed their agents were involved in that incident.

The RubyGems campaign used some of the same retrieval methods as the German Wiki agents, while thousands of malicious packages uploaded included a similar snippet, r.jini.ai, that was contained in the German posts.

Cybersecurity company Socket first flagged the campaign in a threat intelligence report posted May 13, but it does not mention or attribute any of the activity to OpenAI or AI agents.

However, the researchers said they had only limited visibility over the model’s actions and how successful some of them were, noting only OpenAI had the full details.

“This analysis is entirely based on the publicly available RubyGems packages uploaded by these agents,” the researchers wrote. “However, we do not have access to the rest of the AI behavior, in particular the chain-of-thought produced by the model during the incident, which is internal to OpenAI. Therefore, we do not know why the AI agents chose this strategy or whether it was successful.”

OpenAI’s spokesperson told CyberScoop that to date, they have not been able to verify the specific claims about malicious packages or exploitation detailed in the report and are continuing to investigate.

The post Researchers say OpenAI agents were behind May hacking campaign targeting RubyGems appeared first on CyberScoop.

Chinese espionage groups swarm to exploit triple-link chain of zero-days

Proofpoint researchers have spotted at least four state-aligned threat groups chain a trio of zero-day vulnerabilities to conduct espionage on various targets of interest to China’s government since late August. 

The Chinese espionage group that Proofpoint tracks as TA412, also known as Violet Typhoon and APT31, struck first, exploiting the chain of vulnerabilities Aug. 28. At least three additional espionage threat groups followed suit, exploiting the same vulnerabilities in subsequent waves of attacks days later, researchers said.

The exploit chain Proofpoint calls BlueMoon targets Chrome, Chromium-based browsers and Microsoft Windows. It allows attackers to run code in the browser’s sandbox, escape the sandbox and gain system privileges to access a targeted machine, said Mark Kelly, staff threat researcher at Proofpoint.

“All three vulnerabilities were exploited before patches were available to the public,” he said.

The vulnerabilities include: CVE-2026-85046 and CVE-2026-87491, remote-code execution defects in the JavaScript engine for Chromium-based browsers; and CVE-2026-85880, a privilege-escalation zero-day that Microsoft disclosed Tuesday in Windows Advanced Local Procedure Call. 

“While the V8 vulnerabilities were known and fixed in Chromium source code, they were not yet patched in the latest publicly available browsers at the time of the activity, meaning they effectively functioned as zero-days in those products,” Kelly said.

Proofpoint said the exploit kit developer likely reverse engineered the publicly available Chromium patches to weaponize the browser exploit chain during that gap.

With a limited group of organizations exposed to all three vulnerabilities, attackers moved quickly and likely rushed development to target a narrow pool of potential targets. “In all observed cases, the infrastructure used for exploit delivery was created on the same day as — or in the days immediately preceding — the associated campaigns,” Proofpoint wrote in a threat intelligence report.

APT31, a group that’s committed espionage on behalf of China’s Ministry of State Security, including seven Chinese nationals indicted by the Justice Department in 2024, dropped various lures containing the exploit chain loader in phishing emails targeting non-governmental organizations, mining companies and commodity trading firms in the United States. 

The phishing link installed a malicious browser extension disguised as Google Gemini on targeted machines, enabling attackers to surveil browser activity, steal credentials and execute commands, according to Proofpoint. 

Other distinct threat groups have also used the BlueMoon exploit chain with some slight technical changes and variances in targeting. 

“Proofpoint observed BlueMoon usage as recently as Sept. 8,” Kelly said. “The activity peaked Sept. 2-3 immediately prior to the Chrome patch being released and has continued intermittently since then.”

A China-aligned espionage threat group Proofpoint tracks as UNK_LateNight targeted multiple U.S. aerospace companies Sept. 2. Researchers also that day observed UNK_DoubleCheck, a suspected espionage-motivated threat group targeting Vietnamese manufacturing organizations with emails from a compromised Southeast Asian government account. 

Researchers said UNK_QuietRacket, another espionage group aligned with China, targeted government, consulting and financial sector organizations in Indonesia and Singapore Sept. 3.

Proofpoint has directly observed fewer than 20 organizations targeted globally thus far, but Kelly said the true number of impacted organizations is likely much higher. 

While Proofpoint attributes most of the observed attacks to Chinese espionage groups, attackers of other origins and motivations could strike soon as well. 

“Given its ease of adoption, we expect the exploit kit is likely to proliferate further and be adopted by additional espionage-motivated and financially motivated threat actors as patched versions are fully rolled out across all Chromium-based browsers,” Kelly said.

The post Chinese espionage groups swarm to exploit triple-link chain of zero-days appeared first on CyberScoop.

FBI raises alarm over deceptive phishing campaign targeting prominent people

Attackers are targeting prominent, high-profile people, their family members and acquaintances on a commercial messaging application to gain long-term access to their accounts containing sensitive data, the FBI warned in an alert Tuesday.

Officials did not describe the objectives or origins of the attackers, which have more recently impersonated government officials, journalists and publicly known personalities. Attackers are tricking victims into granting them access to a legitimate cloud service, such as Microsoft or Google, under the guise of reviewing a draft article or document.

The ongoing threat, which the FBI has been tracking since late 2025, showcases a “deceptive, sophisticated approach to access user accounts without requiring a password,” the FBI wrote in the public service announcement. The malicious links, which enable OAuth consent phishing, provide attackers with persistent access to a targeted victim’s account.

“Once permission is obtained, it can only be revoked by the victim invalidating the token in their application security settings — not by changing the password,” the FBI wrote.

Authorities did not provide any details about the victims targeted by the campaign or how many people have already been compromised by these attacks. Threat actors previously impersonated event coordinators and planners, using invitations and identity verification requests as lures to gain access to their accounts.

By social engineering unsuspecting victims via OAuth consent phishing, attackers gain full visibility into the target’s configured permissions, allowing them to access emails, files and other sensitive data.

“If the user approves the request, they unwittingly grant high-level access to a malicious application controlled by the cyber actor,” the FBI added. “By registering malicious applications through legitimate authorization protocols and using social engineering tactics, cyber actors can bypass both passwords and multi-factor authentication, which makes consent phishing especially dangerous.”

OAuth is a standardized and widely adopted protocol for authorizing access to applications and other services, including APIs. The standard uses tokens to establish and maintain authorized access to separate resources or services. 

The FBI encouraged people to scrutinize communications from unfamiliar phone numbers or accounts, independently verify the identity of the sender and only grant access to trusted applications.

The post FBI raises alarm over deceptive phishing campaign targeting prominent people appeared first on CyberScoop.

Irregular says ‘human oversight’ responsible for AI sandbox escape incidents

A company that runs AI testing labs involved in a series of breaches carried out by Anthropic and OpenAI’s cyber-focused models said the incident happened in part because they “unintentionally” provided the models with access to the internet.

In a blog posted Friday, Irregular said it partners with frontier labs to “stress test” AI models for security risks before they’re deployed, including simulations of their vulnerability research capabilities.

Those tests included non-public models from Anthropic and OpenAI. Separate disclosures from the companies confirmed these included Mythos 5, Claude Opus and GPT-5.6 Sol.

“As part of our review, we identified that a few interactions with our evaluation environments, in which internet access was unintentionally made available, led some models to take offensive security actions in the real world,” Irregular said in an unsigned blog.

In the incidents involving Anthropic’s models, testers initially believed the models were using a fictional company in its hacking simulations, only to learn later that the name unintentionally matched the domain of a real company. That led the model to “consider taking offensive action against” the real company in multiple training runs.

Irregular said this was due to “human oversight,” and that they typically do a background check to ensure they’re not using a real company for cybersecurity tests. The instructions provided to the model also included the target’s name and “internal addresses within our network” where the model could go to find the simulated environment.

While Mythos performed as intended in the majority of the thousands of tests, a small number of cases showed the model couldn’t distinguish between the fake and real domains and executed actual attacks on internet infrastructure, including exploiting vulnerabilities, extracting credentials and accessing a production database. In one instance, it even began targeting a site with a similar name when credentials for it were discovered online.

“Mainly, models believed they were in simulated environments, when they in fact took action in the real world,” the blog continued. “We are putting in place new and robust protocols to ensure setup issues do not occur while meeting the constraints of the testing process.”

The company said it plans to release a larger whitepaper breaking down the incidents and update their best practices for evaluation setups in the future.

While the companies have drawn criticism from some in the cybersecurity community for failing to securely design their sandboxes for testing, experts have said AI models are known to grind away on fulfilling a command  until they can find a workaround. Additionally, Irregular said granting some level of internet access to models is necessary to fully test out their cybersecurity capabilities.

“Controlled internet access, while it may allow models to exceed containment boundaries, is at times critical for realistic evaluations; without it, threat scenarios lose fidelity, undercutting the purpose of the challenge to reduce post-release risk of models being misused by attackers – as attackers in the real world do rely on the internet,” the company wrote.

According to the blog, Irregular has since “remediated” the “issues that led to these interactions,” though few details are provided.

However, the researchers say the engagement revealed critical gaps in their security practices. 

They plan to improve documentation of evaluation setups, deploy better log monitoring tools capable of tracking “the extreme amount of data generated by the traffic,” revise their threat models to account for rogue AI behavior, and establish faster information sharing between stakeholders.

“Looking further down the line, models will only get stronger. While in this case we believe that better implementation of existing safeguards could prevent most incidents of this kind, as models become stronger, this may not be the case,” Irregular wrote. “We therefore believe this opportunity should be leveraged by us and the community to be proactive and establish forward-looking protocols and [research and development] efforts.”

The post Irregular says ‘human oversight’ responsible for AI sandbox escape incidents appeared first on CyberScoop.

AI’s ‘middle class’ has gotten dramatically better at hacking

As the White House and federal agencies grapple with frontier AI models and their hacking capabilities, researchers are warning that the industry’s “middle class” of smaller models may end up posing a greater threat over the long term.

Research from XBOW this week shows that a growing class of both proprietary and open-source models are becoming strategically important in the offensive security ecosystem. Models like Z.ai’s  open-weight GLM-5.2, xAI’s Grok 4.5, Anthropic’s Opus 4.7, Meta’s Muse Spark 1.1, still perform very strongly at many hacking and exploitation tasks that worry policymakers.

“It’s not even that the open-source variants or…not quite frontline competitors are catching up [to frontier models] as such,” said Albert Ziegler, head of AI at XBOW. It’s that they are crossing a certain threshold, which means that suddenly they are providing net value at a cheaper price.”

That wasn’t necessarily the case as recently as six months ago, when testing on mid-tier class models showed they struggled to complete “moderately complex” agentic tasks. Today’s middle class largely can. Their relative cheapness means users can spend many times more resources—running them repeatedly—to solve the same challenges. 

“Because these models are cheaper, it’s okay to give them more time, and they come from behind and leapfrog the big frontier model,” said Ziegler. “Now, that didn’t work half a year ago because…if you wanted to run some open-source model on a complex task in an agentic way…on a long horizon, then it would just get lost.”

GPT 5.5, now considered a near-frontier model, delivered one of the best performances on exploitation benchmarks that XBOW has recorded to date.

The jump between OpenAI’s GPT 5 and 5.5 “represented one of the clearest 2026 leaps in autonomous web application testing,” according to the report. It saw marked improvements over previous middle-class models in exploiting both “white box” and “black box” scenarios, or with and without access to the underlying victim source code. It also missed fewer vulnerabilities, with a “miss rate,” or failure to spot a vulnerability, of 10%, while GPT 5’s rate was four times larger, 40%.

The emergence of GPT 5.5 changed “the practical baseline for what frontier models can do in offensive workflows,” the XBOW report said.

But the performance leap goes deeper than that. GPT 5.5 performed higher in tests without source code access, while GPT 5 heavily leaned on source code. 

“That last result is significant: working without the code, as an attacker would, GPT-5.5 beat a prior version that could read it,” the XBOW report said. “What translated into findings was the ability to reach and prove a vulnerability against the running system, not to infer it from a pattern in the source.”

XBOW’s testing found that source code access was not as important to these models’ success as other factors, like live interaction with the actual website or software being exploited.

Frontier models like Mythos and GPT 5.6 are indeed more capable on individual cybersecurity tasks, but they can also come with exponentially higher token costs.

New research this week from Anthropic tested two models – Mythos Preview, which is used in Project Glasswing, and Opus 4.8 – to learn how quickly multi-agent swarms could find vulnerabilities in 15 open-source software projects when they coordinate and share information.

While a team of agents working individually and assigned to core directories found 21 vulnerabilities, the coordinating agent swarm found 266. But both tests had to burn through millions of tokens – 6.5 million and 27 million – to get there. Beyond the difficulties with getting access to frontier models, few individuals or organizations have the budget to underwrite that kind of research.

The way these systems coordinate can differ significantly from how humans work together.

Another experiment tested agents’ ability to coordinate on the development of a fantasy-themed video game. Earlier models, models like Opus 4.6, failed to properly coordinate and produced “bad” results, while later models like Mythos and Opus 4.8 were able to achieve better results but did so by hardly coordinating at all on tasks.

“The lack of coordination shown by agents in the fantasy game…in which they siloed themselves and largely failed to merge their work—roughly mirrors some ways in which humans can fail to coordinate,” the Anthropic blog stated.

Further, agents are more homogeneous than humans and “often act the same in situations where different people might take a much more diverse range of actions.”

XBOW also tested Mythos Preview, finding that it showed “exceptional” source-code reasoning and reverse engineering abilities, particularly with source code access. Like other models, losing live-site access had a big impact on its performance, and while Mythos is excellent at finding vulnerabilities, it’s less effective at exploiting them.

]Ziegler said the recent incidents at companies like OpenAI, Anthropic, Meta and others where frontier models escaped sandboxes and hacked into project-adjacent parts of the internet should rightfully alarm lawmakers, and demonstrate  the upper-tier capabilities of large language models.

Like most industries, cybersecurity favors cheap, high-performing tools over expensive ones. The widely adopted tools that have the most impact tend to be affordable and effective, not luxury products. 

And while these models still require human management to be wielded responsibly by law-abiding organizations, that cost tradeoff can look more attractive to malicious hackers, who tend not to care about collateral damage caused by their agents.

“Purely from an attacker’s perspective, I think we already are [there],” Ziegler said.

The post AI’s ‘middle class’ has gotten dramatically better at hacking appeared first on CyberScoop.

Snowflake hacker pleads guilty, faces up to 32 years in prison

A Canadian man pleaded guilty to playing a central role in one of the most far-reaching cyberattacks of 2024 — the widespread compromise of more than 165 Snowflake customer environments, resulting in massive data theft for extortion, the Justice Department said Wednesday. 

Connor Moucka earned $495,000 by extorting his victims, offering stolen data for sale online, and in one case re-extorted a victim with stolen data of a government official and members of a then-former government official’s immediate family, authorities said.

Moucka and his alleged co-conspirators John Binns and Cameron Wagenius stole billions of sensitive records and received more than $2.5 million in extortion payments combined, according to prosecutors. Victims of the attack spree included AT&T, Ticketmaster, Advance Auto Parts and Santander.

“Hiding behind a screen is no shield from justice,” Brett Leatherman, assistant director of the FBI’s Cyber Division, said in a statement. “Moucka learned that when he was arrested just months after he began targeting U.S. companies, stealing sensitive information, and extorting victims for millions of dollars.”

Authorities arrested Moucka relatively quickly because he caused significant damage, said Allison Nixon, chief research officer at Unit 221B. 

“His gang went on a spree of maximizing harm, which directly correlated to maximizing the resources devoted to stopping it,” she said. 

“His behavior was bizarre throughout. Even while stealing data and extorting victims, he did many unnecessary things like threatening me because he thought I was working on his case. I was not working on his case before he threatened me,” Nixon added.

Moucka, who used several aliases online, including “Waifu,” “Judische,” “Catist” and “Ellyel8,” was arrested Oct. 30, 2024, in Kitchener, a city in the Canadian province of Ontario, at the behest of U.S. authorities. He was extradited to the United States in March 2025.

Moucka and his co-conspirators used stolen credentials to access the data storage platform’s customers’ accounts en masse. Records of more than 100 million people were exposed by the data theft campaign, including call and text history records, banking and other financial information, payroll records, government ID numbers and other personally identifiable data. 

Officials said victim companies bore more than $9.5 million in losses combined, not including losses attributable to their respective customers. 

Moucka’s threats and re-extortion tactics were calculated and predatory, and his actions did real harm to his victims, be they companies targeted for theft and extortion or the millions of everyday people who are their customers,” W. Mike Herrington, special agent in charge of the FBI Seattle field office, said in a statement.

Researchers said Moucka and his co-conspirators are all associated with The Com, a sprawling cybercriminal network of minors and young adults who engage in violence, extortion, sextortion and various forms of cybercrime.

“His legacy is one of failure. He extorted and then scammed his victims by not deleting the data, casting doubt on all future pay-or-leak extortion gangs,” Nixon said. 

“The pay-or-leak business model was popularized by him and his gang,” and his claims of data deletion were a lie, she added. “With copycat gangs, defenders grapple with the uncertainty of whether the threat actors are honest.”

Moucka pleaded guilty to computer fraud, wire fraud, aggravated identity theft and a related conspiracy. He is scheduled for sentencing Oct. 27 and faces up to 32 years in prison.

The post Snowflake hacker pleads guilty, faces up to 32 years in prison appeared first on CyberScoop.

Open-source software’s archenemy TeamPCP goes back further than anyone thought

TeamPCP, the threat actor behind an unrelenting flurry of attacks on open-source software this year, has been active much longer than previously thought, according to research Oligo Security shared exclusively with CyberScoop. 

The threat actor, which gained notoriety and has captivated threat hunters as it compromised and injected malicious code into more than 1,000 software packages in less than four months earlier this year, was also responsible for attacks dating back to 2020, Oligo Security found. 

The security vendor’s research team found multiple attacks that bear the markings of TeamPCP, including a late 2025 campaign involving the exploitation of a ShadowRay vulnerability that resulted in the first self-propogating botnet running on hijacked AI infrastructure.

Evidence uncovered during that investigation into the ShadowRay 2.0 campaign was linked to more historical attacks originating from the same IPs, domains and other infrastructure TeamPCP used in attacks that captured widespread attention earlier this year. 

“The scariest thing in this campaign is the speed at which the payloads evolved and changed and adapted to the environment they run in. We saw changes in the speed that we’re not used to seeing in these kinds of attacks. They’re usually slow, careful,” said Uri Katz, director of research at Oligo Security. “This was clearly with the help of AI — the payloads changed rapidly to adjust and change to the environment that they were trying to attack.”

One of the domains that Oligo Security identified in July 2025 was in the profile of TeamPCP’s official GitHub account, said Avi Lumelsky, AI security researcher at Oligo Security. “It’s public, they’re not even trying to hide their identity,” he said. 

From there, Oligo linked TeamPCP to activity tracked under multiple names, including TA-NATALSTATUS and IronErn, spanning from 2020 to late 2025. Much of that activity was traced to the same IPs, domain names, a file server and command-and-control server, researchers said. 

TeamPCP emerged publicly as a brand in late 2025. Soon after, “TeamPCP started to go really broad and do campaigns, which are much more noisy,” said Gal Elbaz, co-founder and CTO at Oligo Security. 

Widespread adoption of AI and TeamPCP’s use of the technology supported this growth as the threat actor built a brand, got more active on social media and boasted publicly about its activities and claimed victims.

“The ability to control the infrastructure and orchestrate the attack with AI was also super new, and I’m sure it helps them,” Elbaz said. 

“All of the companies in the world are in this race to adopt AI because they are afraid their business will die, and they understand, of course, the opportunity. But it’s also what gives the attacker this power to go into it,” he added. “If you don’t really have visibility in what’s going on there or how it behaves, that’s exactly what attackers are after.”

TeamPCP’s more recent attacks have capitalized on new security gaps created by developers’ increasing reliance on AI and the automated systems companies use to deploy code. The threat actor is also consistently wrecking the open-source frameworks and software packages these systems rely on. 

“Most AI infrastructure is open source by design because nobody has the manpower and money to develop everything from scratch,” Lumelsky said. 

“We love open source. We use many of these products ourselves, but it’s all about reading the documentation, and I think many of these tools place the responsibility of using it right and security on the user, and developers are not used to these new kinds of animals,” he added. “That’s why the trust can be exploited at scale.”

As it uncovered a long operational history spanning multiple campaigns, Oligo Security has gained more confidence in understanding how TeamPCP operates. It also means TeamPCP was likely involved in other attacks that haven’t been attributed to it yet or attacks that haven’t been detected. 

“There’s a lot more out there that we haven’t caught or been able to prove up until now,” Elbaz said.

The post Open-source software’s archenemy TeamPCP goes back further than anyone thought appeared first on CyberScoop.

AISI, OpenAI report more ‘unsanctioned’ model hacks

The UK’s AI Security Institute said that their AI research system took “unsanctioned” actions over the internet to engage in “sustained, potentially harmful activity directed at real people.”

According to a blog post and technical report released Tuesday, the organization noticed “unusual data transfers” leaving their research systems through the pseudo-anonymous Tor network on July 28. The models, which included Anthropic’s Mythos 5 and OpenAI’s GPT-5.6-Sol models, were being tested for their cybersecurity capabilities.

Like the OpenAI and Anthropic incidents before it, the offending agents were attempting to solve a challenge. On 10 of 122 runs taken by two models, they took a combined 19 malicious actions, including attempting to insert malicious code into a real open-source software project and creating fake online identities to contact human maintainers and press them to approve it.

It also inserted malicious prompt injection instructions in places “where it reasoned that other automated AI systems might pick them up and execute them.” Sometimes multiple agents would collaborate on a task, with one model leaving public messages or notes for the other on GitHub.

However, AISI said their incident differs in one critical way.

“Importantly, this was not a case of a model escaping its secure test environment, or ‘sandbox,’” the institute wrote in an unsigned blog. “As was standard in our cyber testing, we had intentionally permitted internet access, and model-provider cyber classifiers were deliberately disabled – conditions that do not reflect how frontier models are made available to the public.”

The institute said that while their own design and evaluation choices “to some degree” enabled the malicious behavior, the models still displayed “novel, potentially deceptive behaviors” and were executed “to an extent and severity that we did not anticipate.”

The same day, OpenAI acknowledged AISI and another third-party cybersecurity tester,  private firm Irregular, had recently reported incidents where their models exceeded “beyond their intended testing boundaries.”

That included GPT-5.6-Sol reusing GitHub tokens left by another agent to attempt to recover accounts and to access a DNS server that contained malicious payloads meant to exploit a software vulnerability.

The setup did not work, there is no evidence any real resolver queried it, and the infrastructure was removed when the evaluation ended,” the company wrote in an unsigned blog post Tuesday.

OpenAI said it would review its own third-party testing procedures to focus on higher risk evaluations, assess requests by third-parties to enable internet access, stop conditions and other features for their models.

The incident with Irregular occurred on July 29 during a Capture-the-Flag cybersecurity evaluation of OpenAI’s models. Due to a “misconfiguration” the models were allowed to access the public internet, where they encountered and exploited a real domain, mistakenly believing it was still in a test environment.

OpenAI said an investigation by Irregular is ongoing, but also found that the models had found and used credentials for the site at one point. The blog also references other additional potential cybersecurity incidents.

“Irregular has informed us that all of the issues identified pertaining to the incident are no longer active and relevant safeguards were added to the testing environment,” the blog said. “Irregular has also communicated about related incidents involving other labs from the same testing environment.”

CyberScoop has reached out to Irregular for comment.

The incidents were made public the same day that the White House met with Anthropic, Open AI and other frontier AI companies to preview a new framework for evaluating models before they’re released publicly. Some media outlets have reported that after an executive order, export controls and other actions, the administration does not plan to make the new framework public.

The post AISI, OpenAI report more ‘unsanctioned’ model hacks appeared first on CyberScoop.

Massive supply-chain attack compromises 440 packages under four hours

In less than four hours early Tuesday, an attacker compromised a GitHub maintainer account and unleashed a self-replicating piece of malware which injected malicious code into more than 440 distinct npm packages, according to multiple security firms. 

The worm, built on the open-source Mini Shai-Hulud repository that TeamPCP published in May, was initially let loose in keyv, a data management interface software package with more than 600 million monthly downloads. The attacker spent the next 30 minutes compromising additional packages controlled by the same maintainer, including cacheable, flat-cache, file-entry-cache.

The attack spread to other maintainers, eventually compromising more than 860 packages with a “combined total of over 2 billion monthly installs,” Ilyas Makari, malware researcher at Aikido Security, wrote in a blog post. 

Wiz researchers told CyberScoop it hasn’t observed any new malicious packages since the initial wave moved through a massive footpoint of cloud and code environments in those first four hours. 

“This is the most critical initial compromise, with over 155 million weekly downloads on the root packages,” Wiz Research said in an email. 

Some of the compromised packages, including keyv, flat-cache and file-entry-cache, are present in more than 46% of all cloud environments, according to Wiz. “By comparison, back in the Shai-Hulud 2.0 campaign the most prevalent packages were only in about 28% of environments,” the company said. 

“Time will tell whether the eventual cost and impact outpaces past attacks, or whether adoption of hardening mechanisms such as package aging, and the usage of the relatively less aggressive Mini Shai-Hulud code as basis, will defray the final toll here,” Wiz Research added. 

Researchers from multiple firms sprung into action to monitor the widening attack spree and published indicators of compromise to help potential victims hunt for malicious activity in their systems. 

The Mini Shai-Hulud variant used in these attacks scoops up a trove of sensitive data, including npm, GitHub, AWS and continuous integration credentials. It also steals AI-related configuration files and cryptocurrency wallets, researchers said. 

Microsoft, Aikido, Socket and Wiz all said the same payload and pattern was observed across all affected packages, indicating a single attacker or threat cluster was behind the supply-chain attack and using multiple stolen tokens. 

The malware showcased a few pieces of new functionality, but retained the same core mechanisms that are hallmarks of Mini Shai-Hulud. 

“The evolution is consistent with what we’ve seen from them in past waves, however we don’t yet have the hard links” to confidently attribute the attacks to TeamPCP, Wiz Research said.

The notorious threat actor, which Google previously told CyberScoop it attributes to one core operator that was located in South Africa during at least some of the attacks, compromised and injected malicious code into more than 1,000 software packages in less than four months earlier this year.

The post Massive supply-chain attack compromises 440 packages under four hours appeared first on CyberScoop.

❌